TL;DR: A flat agent loop asks one prompt to explore, plan and execute at once, and small models drift between the three while the tool budget drains. Agent harnesses with a mode layer add a short controller turn per iteration that reads the scratchpad and the remaining budget, names one mode and hands one instruction to a delegate turn running under that mode’s prompt and tools. The cost is one extra short generation per step, and the return is a loop you can steer and traces that arrive already partitioned by phase.
Why Agent Harnesses Need a Mode Layer
The control loop around a model, the agent harness, decides how well an agent can keep improving, a core concern in recursive self-improvement.
Most agent harnesses still run the loop that ReAct (Reasoning and Acting; Yao et al., 2022) made standard: one prompt, one model, a thought and then an action, repeated until the task is done or the step limit hits. It works well for frontier models on short tasks. On a long task with a small open-weight model such as Qwen3-8B or Gemma 4 E4B, the same prompt has to decide whether to look around, lay out a plan or commit to a change, and the model tends to repeat whichever it did last. The two failure modes are familiar to anyone who reads such transcripts: episodes that explore for forty steps and never edit, and episodes that edit on step one with no idea what the repository contains.
Hierarchical Control Behind the Mode Layer
The fix predates agents built on large language models (LLMs). Hierarchical reinforcement learning separates a meta-controller, which picks a subgoal or sub-policy from the current state, from a controller that pursues it. Kulkarni et al. (2016) made that two-level split work on Montezuma’s Revenge, where flat exploration finds almost no reward. The meta-controller’s decision is cheap because it is made rarely and over a small discrete set, and that is the property to copy.
The options framework of Sutton et al. (1999) supplies the vocabulary. An option is a sub-policy with an initiation set and a termination condition. A mode in an agent harness is an option whose policy is the base model under a mode-specific prompt, whose initiation set is “the controller named it” and whose termination condition is the end of one delegate turn. Framed that way, the design questions become concrete: what the controller sees, how its answer is parsed, and what makes it switch.
The Two-Turn Loop: Controller, Then Delegate
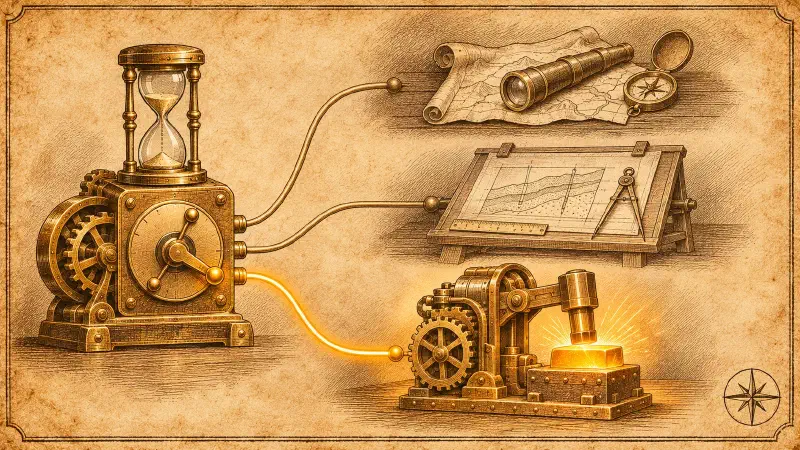
Each iteration makes two model calls. The controller turn receives a compact view of state: a summary of the scratchpad, the list of modes with one line each, the last few mode choices with their outcomes, and the budget left. It answers with a mode name and a single instruction for the next turn in a fixed format, such as a MODE: line followed by an INSTRUCTION: line, and it calls no tools.
The delegate turn receives the mode’s own system prompt, the scratchpad, the instruction and only the tools that mode is allowed to use. An explore turn may read and run probes but not write, and a plan turn produces a numbered plan and nothing else. An execute turn may edit and run code, and its result, pass or error, is appended to the scratchpad before the next controller turn. The scratchpad carries state between the two roles, and it is memory rather than learning: scratchpad-only agents start every new episode from the same weights.
Agent Harness Modes at a Glance
| Mode | Controller hands over | Delegate may do | Turn ends when |
|---|---|---|---|
| explore | A question about the environment | Read files, list directories, run read-only probes | The answer is written to the scratchpad |
| plan | The scratchpad summary and the budget left | Write or revise a numbered plan, no tool calls | The plan is written to the scratchpad |
| execute | One plan step | Edit files, run code or tests, call task tools | The step’s result, pass or error, is recorded |
Agent harnesses built this way need no second model. The same weights run both turns, and the mode prompt does the specialisation, which is the practical point for small deployments: one model served once, with a controller prompt short enough that the extra call costs a few hundred output tokens. Where a stronger model is available, the controller is the role to give it, since its decisions are few and consequential while delegate turns are many and cheap.
Parsing the Mode Choice Without Breaking the Loop
The weakest link in the two-turn design is the string between the turns. A model asked for MODE: explore will, over thousands of turns, also produce **Mode:** Explore, Next mode: explore, explroe and a paragraph of reasoning that mentions all three modes. If the parser is one strict regex, each of those costs an iteration or ends the episode, and a harness that fails on formatting measures sampling luck rather than the agent.
The robust pattern is a ladder of parsers, tried from strict to lenient, with a default at the bottom:
import re

MODES = ("explore", "plan", "execute")

def edit_distance(a: str, b: str) -> int:
    prev = list(range(len(b) + 1))
    for i, ca in enumerate(a, 1):
        cur = [i]
        for j, cb in enumerate(b, 1):
            cur.append(min(cur[j - 1] + 1, prev[j] + 1, prev[j - 1] + (ca != cb)))
        prev = cur
    return prev[-1]

def pick_mode(reply: str, remaining: int, previous: str) -> str:
    head = reply[:500]
    m = re.search(r"mode:\s*\**\s*([a-z]+)", head, re.I)          # 1. labelled line
    if m and m.group(1).lower() in MODES:
        return m.group(1).lower()
    m = re.match(r"\W*([a-z]+)", head, re.I)                      # 2. bare name first
    if m and m.group(1).lower() in MODES:
        return m.group(1).lower()
    for word in re.findall(r"[A-Za-z]{4,12}", head[:120]):        # 3. typo tolerance
        for mode in MODES:
            if edit_distance(word.lower(), mode) <= 2:
                return mode
    return "execute" if remaining <= 2 else previous              # 4. safe default
Three details matter. The fuzzy rung scans only the first line or so, because “place” and “plane” are within two edits of “plan” and any long reasoning paragraph contains one of them. The default is budget-aware, since with two steps left the useful action is almost always to execute. And every rung below the first is logged, so a rising fuzzy-match rate shows up as a prompt problem before it shows up as a score problem.
Mode Controllers in LangGraph
Graph-based frameworks expose the same primitive one level up. In LangGraph, a conditional edge is a function from state to the name of the next node, and a mode controller is that function with a model call inside it. The parsing ladder belongs inside the edge, not in the nodes, so each specialist node receives a clean mode name and nothing else.
Budget as State: Remaining Steps Shape the Choice
A controller that cannot see the budget explores until the budget ends. The harness should keep a per-episode ledger with the total and remaining action count, optionally with per-mode caps such as at most four explore turns in a row, and render it into the controller prompt as plain numbers. The ledger also names the termination: solved, budget exhausted or failed. That label matters later, because an episode that ran out of steps mid-plan is a different training example from one that broke the build.
With the budget in view, the controller’s behaviour shifts: explore early, plan once there is enough to plan with, execute while steps remain, and skip exploration entirely on a task type it has met before. That last shortcut looks like cheating to anyone who expected a tidy explore, plan, execute sequence on every episode, and it is not. If executing from step one secures the environment’s pass signal, that is the correct adaptation, and the controller that found it is doing its job. The mode layer exists to make the choice visible and steerable, not to enforce a ritual.
Tagging Traces by Mode for Later Training
The last reason agent harnesses should split the loop is the data they leave behind. If every delegate turn’s prompt and completion are stored with a phase field holding the mode name, the episode trace arrives at training time already partitioned. You can train on execute rows only, down-weight exploration, hold out plan rows for a separate planner, or compare the token mix per mode across rounds without re-reading a transcript.
Plan-and-Act: Separating Planning From Execution
Plan-and-Act (Erdogan et al., 2025) shows what the separation buys. A Planner that writes structured plans and an Executor that turns them into browser actions, with the Planner trained on synthetic plan annotations of successful trajectories, reached a 57.58 percent success rate on WebArena-Lite, and the authors credit the gain to keeping high-level planning apart from low-level execution. Self-generated data obeys the same logic: a plan row and an execute row come from different distributions, and a loss that averages them teaches the model to draft plans while it edits.
For a loop that trains on its own successful episodes, phase tags also make the training window easier to reason about. Sliding-window supervised fine-tuning (SFT) on recent successes can be applied per mode, so an improvement in planning is not diluted by a thousand near-identical execute rows.
If each round trains a fresh Low-Rank Adaptation (LoRA) adapter, the tags let you ask whether the adapter changed which modes the controller picks and how long each mode runs. That is a more useful diagnostic than the pass rate alone, because a controller that stopped exploring and a delegate that got better at editing produce the same score for different reasons.
FAQs
What is an agent harness?
An agent harness is the code around a model that turns it into an agent: the loop, the prompts, the tool interfaces, the memory carried between steps, the budget and the stopping rules. The model supplies the policy and the harness supplies the control flow, so changing the harness changes behaviour without touching the weights.
How is this different from a ReAct loop?
A ReAct loop makes one call per step, in which the model reasons and acts in the same output under the same prompt. A mode-based loop makes two calls per step, and the first only chooses a mode and writes an instruction. That adds a little latency and spares one prompt from covering exploration, planning and execution equally well.
What happens when the controller picks the wrong mode?
One delegate turn is spent, its result lands in the scratchpad, and the next controller turn can correct course. That is why a mode’s termination condition is a single turn rather than a whole sub-task. The remaining risk is a loop between two modes, which a per-mode cap and the budget ledger end.
Why do small models need modes in an agent harness?
A single prompt has to decide whether to look around, plan or commit to a change, and small models tend to repeat whatever they did last. A mode layer moves that decision into a short controller turn, so each delegate turn runs under one focused prompt with only the tools that mode allows.
How do mode tags help with training data for agents?
Storing the mode name with every delegate turn partitions the episode trace by phase without relabelling transcripts. You can train on execute rows only, down-weight exploration, hold out plan rows for a separate planner, or compare the token mix per mode across training rounds.