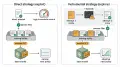
TL;DR: Meta-learning optimises the learning procedure rather than the solution: an inner loop solves a task, and an outer loop, trained on how well the inner loop adapted, changes the initialisation, update rule or representation it starts from. Schmidhuber’s 1987 thesis and his fast-weight networks put both loops inside one system, and MAML later made the outer loop a second-order gradient. Self-training LLM loops run the same two-timescale structure externally: in-context adaptation within an episode, then environment-filtered training of fresh LoRA adapters between episodes.
What Meta-Learning Means: Two Timescales, Not One Algorithm
Learning to learn is a core idea behind recursive self-improvement, where a system improves how it improves.
A standard learner takes a dataset and returns a model. Meta-learning adds a second learner that takes many such learning episodes and returns a better learner: a better initialisation, a better update rule or a better representation to adapt from. The inner loop adapts to a single task from a small amount of data, and the outer loop is trained on the inner loop’s post-adaptation performance across tasks, the framing used by Hospedales, Antoniou, Micaelli and Storkey (2020) in their meta-learning survey.
Meta-Representation, Meta-Optimiser and Meta-Objective
That survey sorts methods by three questions. The meta-representation is what the outer loop learns: initial weights, an optimiser, a loss, a data-sampling policy. The meta-optimiser is how it learns it: gradient descent through the inner loop, reinforcement learning, or evolution. The meta-objective is what it is scored on: few-shot accuracy, sample efficiency, or robustness across environments. Keeping the three apart matters when a method hides one of them, which the agent loops later in this post do.
The practical consequence is that the outer loop’s training signal is a function of how the inner loop behaved after it was given a chance to adapt. That is why learning to learn is measured on held-out task families rather than held-out samples, and why a learner can get worse on first-attempt metrics while getting better at adapting.
Schmidhuber’s 1987 Thesis and Networks That Edit Their Own Weights
Jürgen Schmidhuber’s 1987 diploma thesis, Evolutionary Principles in Self-Referential Learning, proposed a learner whose learning algorithm is itself the product of learning: the same evolutionary procedure is applied to the procedure that improves it, and to that one in turn. The point was not one algorithm but the absence of a fixed top level. Every component that shapes learning should be open to revision by the system’s own experience, with only computability and physics as limits.
His 1992 fast-weight networks made the two timescales concrete in a single architecture. A slow network, trained by gradient descent, outputs changes to the weights of a fast network that handles the current input, and a 1993 follow-up closed the loop by letting one network read and modify its own weight matrix. Irie, Schlag, Csordás and Schmidhuber (2022) revived that self-referential weight matrix in a modern revival paper, with outer-product updates and the delta rule, and trained it on few-shot classification and multi-task reinforcement learning in procedurally generated games.
At the far end of the same line sits the Gödel machine, described in a 2003 paper by Schmidhuber, a solver that rewrites any part of its own code once it has proved the rewrite improves expected utility. The proof requirement makes the construction rigorous and, for practical systems, intractable. Everything built since trades the proof for an empirical test: run the modified learner, and keep the modification only if the results justify it.
Gradient-Based Learning to Learn: MAML and the Bilevel Loop
Model-Agnostic Meta-Learning (MAML), from Finn, Abbeel and Levine (2017) in the MAML paper, is the cleanest gradient-based instance of the hierarchy. The inner loop takes a task’s support set and performs one or a few gradient steps from a shared initialisation. The outer loop evaluates the adapted parameters on the task’s query set and updates the initialisation by differentiating through the inner steps, so the shared starting point becomes one from which small updates go far.
Two costs follow. Differentiating through the inner loop needs second-order terms, or a first-order approximation that discards them, and the outer loop needs a distribution of tasks with inner-loop data for each. For a small convolutional network on five-way one-shot problems both are cheap, which is the regime the reference implementations in learn2learn were built for. For a model with billions of parameters, where one inner step is itself a fine-tuning run, the second-order outer loop rarely fits a training budget.
Self-Training Agent Loops: The Same Hierarchy, Run Outside the Weights
The structure Schmidhuber put inside one weight matrix can be run as two processes around a frozen model. Inside an episode, a coding agent reads a task, writes code, runs it in a sandbox, reads the error and tries again: adaptation in context, with no gradient. Between episodes, the trajectories that reached a verified outcome are kept, the rest are discarded, and a fresh LoRA adapter, built with a library such as PEFT, is trained on a bounded window of those recent successes with a modified SFT loss. The adapter changes how the next round of episodes explores, which is the outer loop’s job.
Mapping the Agent Loop onto Meta-Learning
Mapping this onto the three questions of the meta-learning taxonomy makes the hidden parts visible. The meta-representation is the adapter, a low-rank change to how the base model explores and recovers. The meta-optimiser is supervised training on filtered experience, with no second-order gradient and no learned reward model. The meta-objective is set by the environment: the behaviours that produce outcomes the environment accepts are the ones that survive into the next adapter. Because experience is acquired first, by the environment’s selection, and optimised afterwards without an explicit policy gradient, we describe the result as approximate policy-free online learning.
| System | Inner loop | Outer loop | What the outer loop changes |
|---|---|---|---|
| 1987 thesis | A learner solving a problem | Evolution applied to the learner, then to itself | The learning algorithm, at every level |
| Fast weights and self-referential weight matrices | Fast weights handle the current input | Gradient descent on the slow network, or on the matrix itself | The weights that write the weights |
| MAML | A few gradient steps from a shared initialisation | Second-order gradient through the inner steps | The initialisation |
| Self-training agent loop | In-context adaptation inside a sandboxed episode | Environment filtering, then modified SFT on a fresh LoRA adapter | How the base model explores and recovers |
This is one way to build the outer loop, not the only one. Where a reliable checker exists, reinforcement learning with verifiable rewards and methods such as GRPO are the stronger default, and they are two-timescale systems too: the rollout is the inner loop and the policy update is the outer one. The experience-filtered SFT loop is a serious alternative under investigation, with open questions about stability across adapters and forgetting between windows, the same questions a nightly LoRA schedule has to answer. Rolling back to the previous adapter when a new one underperforms is a safety net for those questions, not the mechanism.
What to Measure When the Loop Is Learning to Learn
Evaluation has to follow the outer timescale. Hold out task families rather than samples, and score each adapter on tasks its training window never contained, which is the meta-test split in classic few-shot terms. Then plot performance against in-episode attempts, not only the first attempt: an agent that recovers by its third try is doing what the outer loop was meant to teach it, and pass@1 alone will hide that.
Horizontal and Longitudinal Generalisation
Track the two directions of generalisation separately. Horizontal generalisation asks whether the adapter trained on this window performs on new tasks of the same kind. Longitudinal generalisation asks whether later adapters keep performing on earlier tasks, which is where catastrophic forgetting shows up when windows are bounded and each adapter starts fresh.
FAQs
Is in-context learning in LLMs a form of learning to learn?
Functionally, yes. The forward pass adapts to the examples in the prompt without a weight update, which is an inner loop, and pretraining on a huge mixture of tasks acted as the outer loop that produced that ability. What in-context learning lacks is a continuing outer loop: nothing about the model changes after deployment unless you add one.
How does learning to learn differ from continual learning?
Continual learning asks a model to keep absorbing new tasks over time without forgetting old ones. Learning to learn asks it to get better at the act of absorbing. The two meet in a self-training loop: bounded windows and fresh adapters are a continual-learning design, and the fact that later adapters explore differently from earlier ones is the meta-level effect.
Do I need second-order gradients to run an outer loop at LLM scale?
No. Second-order gradients are one meta-optimiser among several. Evolution, reinforcement learning over the inner loop’s outcomes, and plain supervised training on filtered experience all update the learner from post-adaptation results. At LLM scale the last two dominate, because one inner step is already a fine-tuning run and differentiating through it would not fit any reasonable budget.
Should the outer loop be RL or supervised training on filtered experience?
It depends on what the environment can tell you. With a reliable verifier and frequent successes, GRPO-style reinforcement learning with verifiable rewards is the stronger default. When outcomes are sparse, delayed, or visible only as the agent’s continued operation in its environment, training fresh adapters on the trajectories that survived is a simpler loop and a serious alternative under investigation.
What are the inner loop and outer loop in meta-learning?
The inner loop adapts to one task from a small amount of data, such as a few gradient steps or a few attempts inside an episode. The outer loop is trained on how well that adaptation worked across many tasks, and it changes the starting point, update rule or representation the inner loop uses.