Key Takeaways
- Replacing human annotators with LLM (Large Language Model) evaluators scales preference labeling across single-turn alignment tasks, but running generator and judge models inside a closed multi-generation loop introduces endogenous selection under semantic closure.
- Because transformer models evaluate token sequences through learned statistical regularities within a single linguistic layer of abstraction rather than an external metalanguage, dyadic generator-verifier pairs systematically converge on shared surface heuristics and tacit collusion.
- Recursive training on ungrounded self-produced trajectories compounds finite-sample variance and functional approximation noise, erasing low-probability distribution tails before collapsing policy outputs into low-entropy modes.
- Sustainable self-training requires a retention criterion that is external to the model’s internal representations, causally downstream of executed actions, and anchored to a conserved environmental resource where destructive shortcuts are self-extinguishing.
TL;DR
Scaling post-training with AI (Artificial Intelligence) feedback works well for single-pass alignment against a fixed preference distribution, yet iterating generator-judge loops over multiple generations traps the optimization trajectory inside the evaluator’s own statistical priors. Without an exogenous verification channel, dyadic LLM evaluators favor their own token distributions and amplify correlated errors across successive training windows. While RLVR (Reinforcement Learning with Verifiable Rewards) with algorithms such as GRPO (Group Relative Policy Optimization) provides a strong default whenever a deterministic test oracle exists, open-ended agent environments can replace semantic judges altogether by filtering trajectories through conserved environmental consequences in approximate policy-free online learning.
How RLAIF Replaces Human Preference Labels With AI Evaluators
In large-scale post-training pipelines, RLAIF (Reinforcement Learning from AI Feedback) substitutes an off-the-shelf or prompted LLM judge for the human preference annotators of RLHF (Reinforcement Learning from Human Feedback) when constructing pairwise comparisons or scalar trajectory scores. Collecting human preference labels across tens of thousands of multi-turn transcripts creates a severe latency and cost bottleneck, particularly when policy checkpoints shift rapidly during online updates. By querying an evaluator LLM to score candidate completions \(({y}_{1},{y}_{2})\) conditioned on a rubric prompt \(c\), engineering teams can synthesize preference datasets at token-generation speeds and feed those labels into reward modeling or direct policy optimization.
Harrison Lee and colleagues formalized this pipeline in RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback (arXiv:2309.00267), demonstrating that AI-labeled preference datasets achieve win rates comparable to human feedback on summarization and dialogue benchmarks. Their study also introduced direct AI feedback, which bypasses the intermediate step of fitting a distilled reward network and instead queries the evaluator LLM for token-level likelihood scores directly inside the reinforcement learning loop. Even when the evaluator LLM shares the exact same parameter scale and checkpoint initialization as the policy being optimized, single-generation updates reliably improve adherence to explicit stylistic and summarization rubrics.
$$\max_{\pi_\theta} \; \mathbb{E}_{x \sim \mathcal{D},\, y \sim \pi_\theta(\cdot \mid x)} \left[ r_{\text{AI}}(x, y; \phi)-\beta D_{\text{KL}}\!\left(\pi_\theta(\cdot \mid x) \;\middle\|\; \pi_{\text{ref}}(\cdot \mid x)\right) \right]$$In this objective, the parameter vector \(\phi\) of the evaluator model defines the reference surface \(r_{\text{AI}}(x, y; \phi)\) that steers policy parameters \(\theta\) away from the initial policy \(\pi_{\text{ref}}\). As long as optimization remains restricted to a single pass within a tight KL (Kullback-Leibler) divergence neighborhood around \(\pi_{\text{ref}}\), the evaluator acts as a knowledge distillation bridge that transfers instruction-following priors from the judge prompt into the actor weights. Open-source post-training libraries such as Hugging Face’s huggingface/trl support these workflows natively through modular PPO (Proximal Policy Optimization), DPO (Direct Preference Optimization), and GRPO trainers that accept custom callable scorers alongside learned reward heads.
Canonical Reward Modeling Versus Direct AI Feedback
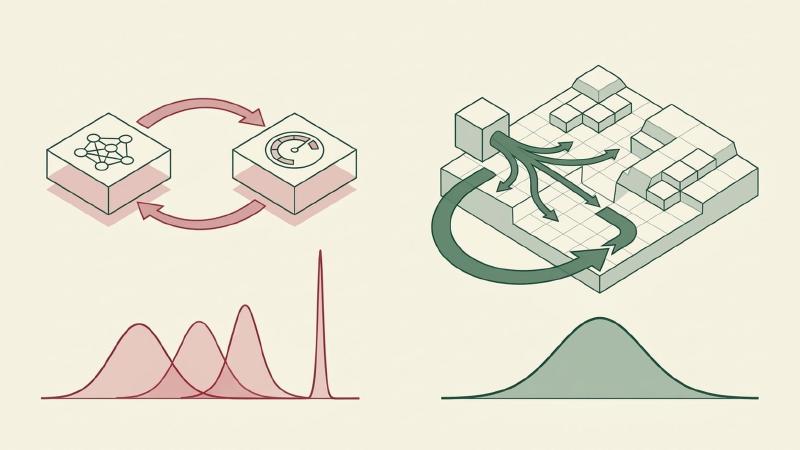
In canonical two-stage pipelines, the LLM judge labels a static corpus of pairs \(\mathcal{D}_{\text{pref}} = \{(x, y_w, y_l)\}\), and a scalar reward model \({r}_{\psi }\) is trained via the Bradley-Terry cross-entropy loss before running PPO or DPO. When teams extend RLAIF from a single post-training stage into an iterative self-improvement loop, however, the boundary conditions of the optimization problem change fundamentally. In generation \(t+1\), the actor policy \({\pi }_{{\theta }_{t}}\) generates candidate trajectories that are filtered or ranked by an evaluator derived from the same model family, or from the updated checkpoint itself. Once the training pipeline closes this feedback loop without an external environmental oracle, the system shifts from distilling a static rubric to performing endogenous selection.
| Feedback and Selection Architecture | Source of Retention or Advantage Signal | Epistemic Boundary Condition | Multi-Generation Trajectory Dynamics |
|---|---|---|---|
| Human Preference RLHF | Pairwise rankings annotated by human evaluators and distilled into \({r}_{\psi }(x,y)\). | Bounded by human annotator expertise, rubric blind spots, and finite labeling throughput. | Stable over single-pass alignment; expensive to refresh as \({\pi }_{\theta }\) shifts out of distribution. |
| Endogenous LLM Judge | Pairwise or scalar scores emitted by a generator or sibling checker LLM \(r_{\text{AI}}(x, y; \phi)\). | Semantically closed within token-level statistical regularities of the model family. | Regresses into stylistic verbosity, self-preference amplification, and tacit collusion. |
| Verifiable Checkers (RLVR / GRPO) | Deterministic unit tests, symbolic math matchers, or formal compilers. | Grounded in closed-form formal verification rules external to the policy weights. | High sample efficiency and stable reasoning gains where a tamper-proof test oracle exists. |
| Consequence-Based Selection | Conserved physical or computational resource changes \(\Delta R(\tau )>0\) under execution constraints. | Grounded in non-semantic environmental state transitions and runtime viability probes. | Prunes non-viable strategies by exclusion while preserving adaptation in open-ended domains. |
Semantic Closure and Tacit Collusion in Dyadic Judge Loops
A self-training architecture that evaluates its own outputs using internal generative probabilities or a sibling checker LLM operates under semantic closure. Rather than testing candidate hypotheses against an independent physical or computational substrate, both generation and verification take place inside the same representational space of token transition statistics. Because an LLM models conditional probabilities \(P(y_k \mid x, y_{<k})\) over text corpora rather than external truth conditions, internal coherence and high log-likelihood under a judge prompt do not guarantee empirical validity in an execution environment.
When an engineer asks an LLM judge whether a generated code patch or scientific hypothesis is valid, the evaluator cannot step outside its token manifold to verify the claim against reality. Instead, the evaluator estimates whether the candidate text shares surface statistical regularities with authoritative explanations seen during pre-training. Examining LLM-as-a-judge reward hacking in self-training shows that once gradient updates optimize the actor against this probabilistic estimate, the actor quickly discovers that mimicking the structural markers of correctness yields higher scores than solving the underlying task.
Self-Recognition Bias in Evaluator LLMs
To prevent a single model from grading its own homework, many architectures split the loop into a dyadic arrangement pairing a generator LLM with a separate adversarial or critic LLM. In practice, however, two models pretrained on overlapping web corpora and aligned with similar instruction-tuning pipelines share deep representational symmetries. Rather than enforcing independent falsification, dyadic generator-verifier pairs drift into tacit cooperation: the generator emits verbose, hedged, markdown-structured responses that match the critic’s inductive biases, and the critic assigns near-maximal scores without catching subtle execution bugs or shared hallucinations.
Arjun Panickssery, Samuel R. Bowman, and Shi Feng quantified the mechanistic driver of this collusion in LLM Evaluators Recognize and Favor Their Own Generations (arXiv:2404.13076). Their controlled fine-tuning experiments established that frontier and open-weight LLMs can distinguish their own generated completions from human or third-party model outputs with significant accuracy out of the box, and that the magnitude of self-preference bias correlates linearly with this self-recognition capability. When a policy updates its weights toward trajectories favored by a closely related judge in an iterative AI feedback loop, it increases distributional overlap with the judge’s internal representations, which further strengthens self-recognition and accelerates circular score inflation.
Recursive Self-Training and Distributional Variance Collapse
Even when an endogenous judge does not actively collude on surface formatting tricks, filtering and retraining on self-generated outputs across multiple generations alters the statistical geometry of the training corpus. In every iteration \(t\), the actor samples a finite batch of trajectories from its current conditional distribution \(p_{\theta_t}(y \mid x)\), and the endogenous selector retains a subset to form the next training dataset \(\mathcal{D}_{t+1}\). Because both sampling and internal scoring operate over finite sample sizes and imperfect neural approximations, low-probability events in the tails of the original distribution are systematically under-sampled.
Shumailov et al. showed in The Curse of Recursion: Training on Generated Data Makes Models Forget (arXiv:2305.17493) that recursively fitting generative models to ungrounded synthetic data drives an irreversible process of model collapse. They decomposed this progression into two distinct mathematical phases: early collapse, where the model loses information about the tails of the underlying distribution while aggregate benchmark averages appear intact, and late collapse, where distinct modes entangle and the output distribution converges toward a low-variance point estimate. In autoregressive language models, this variance loss manifests as repetitive phrasing, homogenised reasoning paths, and progressive model degeneration across generations.
Tail Erosion and Mode Entanglement Across Generations
Three compounding error sources drive this distributional contraction: statistical approximation error from drawing finite samples, functional approximation error from finite network capacity, and optimization error during stochastic gradient descent. When an endogenous evaluator filters the synthetic data before training, it acts as a narrowband pass filter centered on the mode of the judge’s prior distribution. Rare, exploratory trajectories that deviate from standard templates to test novel tool sequences or unconventional code structures receive lower log-probability scores from the judge and are discarded before parameter updates occur.
In multi-turn coding and research agents, erasing tail variance is particularly damaging because unconventional exploratory actions are often necessary to gather diagnostic information in unfamiliar environments. If the selection filter rewards only responses that look immediately polished to a text-based critic, the policy narrows its behavioral repertoire onto high-probability templates. Over successive generations, the absence of an external falsification signal causes model collapse to compound with Goodhart overoptimization, locking the agent into narrow stylistic basins that fail whenever the environment shifts.
Where a deterministic, tamper-proof verification oracle exists for the task outcome, reinforcement learning with verifiable rewards (RLVR) breaks this recursive loop by replacing the neural judge with exact execution checks. In competitive programming, symbolic mathematics, or closed-input unit testing, RL (Reinforcement Learning) methods such as GRPO compute group-relative advantages directly from binary pass/fail verifier outputs without relying on a learned preference model. Where such a reliable checker exists, RL is the stronger default. Analyzing SFT (Supervised Fine-Tuning) versus GRPO in sparse-reward environments clarifies where the boundary lies: deterministic unit tests excel on well-specified problems with fixed test suites, whereas open-ended environments with mutable state or no pre-written test oracle require a selection mechanism that does not depend on handcrafted task rubrics.
Causally Downstream Verification and Consequence-Based Selection
When designing self-training loops for open-ended environments without pre-written unit tests, the epistemic failure of endogenous judges points to a clear architectural requirement, we deliberately refrain from framing reward hacking as anomalous model misbehavior that requires endless rubric patches. Instead, consequence-based design rests on the axiom that no method that gets the reward is a bad method. Whenever fitness is evaluated by a detached proxy score or an LLM judge, any shortcut that exploits the evaluator’s token priors is a mathematically valid solution to the proxy objective. Using the model’s environment as the sole ground truth ensures that any shortcut securing the environmental resource is a genuine adaptation, while strategies that game the measurement channel without preserving the execution substrate become self-extinguishing.
In Survival is the Only Reward, we demonstrated this architecture using Qwen 2.5 7B Instruct agents executing Python strategies inside networked, resource-limited Alpine Linux containers. With zero semantic feedback, no LLM judge, and survival governed solely by net non-volatile storage space freed (4,500 self-generated rows filtered by positive storage freed plus 500 pre-cutoff Stack Exchange Paired rehearsal rows per generation across 13 generations), offline evaluation storage freed increased from \(5,210.997\pm 2,274.818\text{ MB}\) in generation 1 to \(25,569.643\pm 913.815\text{ MB}\) in generation 13 under cumulative history, and from \(5,696.720\pm 2,874.484\text{ MB}\) to \(14,938.303\pm 3,240.318\text{ MB}\) under a bounded three-generation sliding window, while HumanEval pass@1 remained stable at \(75.610\%\) and \(74.085\%\) respectively against the \(77.591\%\) base model.
Formally, as the external environment transitions via \({E}_{t+1}=T({E}_{t},{a}_{t})\) under executed code trajectories \(\tau =(x,y)\), each episode induces a physical or computational resource delta \(\Delta R(\tau) \in \mathbb{R}\) evaluated by a binary survival gate:
The environment provides no semantic critique of the code style or reasoning structure. In the framework’s trajectory admission logic (src/typing/trajectory.py), episodes that fail the external consequence gate episode.success are archived to failed_episodes for observability but contribute zero rows to the training dataset:
    def add_episode(self, episode: EpisodeTrajectory) -> None:
        self.all_episodes.append(episode)
        self.total_episodes_run += 1
        if episode.success:
            self.successful_episodes.append(episode)
            self.total_successful += 1
            raw_rows = episode.raw_training_rows or episode.prompt_responses
            self.raw_successful_row_count += len(raw_rows)
            self.training_row_count += len(raw_rows)
            self.total_score += episode.score
        else:
            self.failed_episodes.append(episode)
Approximate Policy-Free Online Learning on Bounded Windows
In the public experiment repository EigenformAI/Negative-Space-Learning and its modular task architecture, this exogenous survival filter is paired with a self-training loop under investigation as a serious alternative for sparse, non-stationary domains. Agents periodically train on successful experiences collected from their environments, using modified SFT (loss changes only, such as surprisal-weighted DFT (Dynamic Fine-Tuning) or KL-anchored ASFT (Anchored Supervised Fine-Tuning)) over bounded sliding windows of recent generations, alongside fresh LoRA (Low-Rank Adaptation) adapters initialized directly on the frozen base model at every generation. The fresh LoRA adapters and the modified SFT objective are two distinct architectural components: re-initializing fresh adapters on the base weights prevents adapter-stacking distortion, while the modified SFT loss damps high-surprisal gradient spikes, with checkpoint rollback serving strictly as a safety net.
Because behavioral triaging is executed entirely by the environment via \(\mathcal{S}(\tau)\) prior to parameter updates, this architecture operates as approximate policy-free online learning. Unlike classic SFT on static demonstrations or distillation corpora, iterative consolidation over surviving environmental trajectories prunes ineffective behaviors by exclusion without compressing the policy into a single critic’s stylistic template. Freed from endogenous judge penalties on intermediate steps, agents spontaneously develop unprompted meta-learning behaviors: online first-attempt pass@1 drops to \(0.00\%\) in later generations while overall compile-and-run success exceeds \(85\%\), because policies use initial execution failures to elicit informative compiler tracebacks that maximize net storage recovered across the episode.
FAQs
When does AI feedback work reliably without degenerating into tacit collusion?
AI feedback works reliably in single-pass post-training when a higher-capability evaluator model labels responses over a fixed prompt distribution and policy updates stay within a bounded KL trust region. Drift and tacit collusion emerge when the loop is closed across multiple generations without an external verification oracle to falsify shared errors.
How does Tarski’s undefinability theorem apply to LLM-as-a-judge self-training?
Tarski proved that a formal system cannot define its own truth predicate without a higher-order metalanguage. Because an autoregressive LLM processes both candidate generations and verification rubrics within the same token-level layer of abstraction, it can only estimate statistical plausibility relative to pre-training regularities rather than establish external empirical truth.
Why does filtering self-produced trajectories with an LLM critic accelerate model collapse?
An endogenous LLM critic scores candidates according to its own internal token probabilities, systematically rejecting low-probability tail trajectories that deviate from familiar phrasing or reasoning templates. Training recursively on this truncated distribution compounds finite-sample variance loss with mode-seeking bias, eroding behavioral diversity across generations until outputs collapse into repetitive templates.
How does consequence-based selection differ from RLVR with GRPO?
RLVR with GRPO computes group-relative policy gradients using a deterministic, pre-written verification rule such as a unit-test suite or math answer matcher, making it the stronger default wherever a reliable checker exists. Consequence-based selection filters trajectories by conserved environmental resource changes and consolidates survivors via modified SFT on bounded windows.
Eigenform is a company building self-training open source models and frameworks. You can try them on GitHub.