TL;DR
- Agentic infrastructure is the stack that lets an AI agent plan, act through tools, and persist state across multiple steps, distinct from the infrastructure built for a single-turn model call.
- It has to support a longer-running, stateful loop rather than a one-shot request-response pattern, which changes what the compute, memory and orchestration layers need to handle.
Key Takeaways
- Architectures range from single-agent to orchestrated multi-agent systems. Each has different infrastructure demands for state management and coordination.
- Core components recur across most agentic stacks. Compute, memory or state storage, tool integration, and an orchestration or control layer show up in nearly every design.
- Building agentic infrastructure means planning for longer-running, stateful workloads. Request patterns, failure handling and monitoring all differ from infrastructure built for stateless model calls.
- Infrastructure choices affect reliability as much as agent design does. A well-designed agent running on infrastructure that cannot persist state reliably will still fail in production.
A single-turn model call is short. A prompt goes in, text comes out, and the serving layer keeps nothing. An agent operates differently: it maintains a persistent goal, evaluates available tools, inspects observations, and decides what to do next across sequential turns. Agentic infrastructure is the operational stack that keeps that multi-turn loop executing, bounded, and recoverable when components fail.
Standard cloud platforms provide basic building blocks like virtual machines, message queues, relational databases, and serverless containers. However, agentic infrastructure composes those resources specifically to manage non-deterministic model loops, dynamic tool execution, and progressive context growth. At Eigenform, we run autonomous reasoning agents across multi-gigabyte spatial datasets in the Geocluster Research Harness. The architectural guidelines and failure patterns described here reflect operational lessons learned from diagnosing, stabilizing, and profiling multi-step runs in that environment.
What Is Agentic Infrastructure?
Agentic infrastructure is the stack of compute, storage, tool runtimes, orchestration engines, and monitoring systems that enables autonomous AI agents to plan, execute actions, and persist state across multi-step tasks. These infrastructure solutions for ai agents contrast with standard model serving by maintaining durable execution state and bounding tool interactions across long-running workflows.
The primary difference between agentic infrastructure and standard model serving centers on duration, state durability, and side-effect control. A standard inference call terminates as soon as the final token streams back. An agent run terminates only when the broader task completes, an operational budget expires, or an unrecoverable failure halts execution. If a host crashes during a thirty-step workflow, stateless serving loses all intermediate progress and restarts from scratch. Dedicated agentic infrastructure isolates tool execution, records intermediate milestones durably, and allows interrupted workflows to resume without repeating completed work.
To prevent architectural ambiguity, production agent systems separate data into five distinct state tiers:
- Context: The active token window submitted to the model on the current turn, representing volatile working memory rebuilt on each step.
- Run state: Durable structured records such as step counters, dispatch logs, and remaining budgets required to audit or resume an active task.
- Artifacts: Bulk data outputs, including parsed tables, generated shapefiles, and raw tool payloads, stored on disk outside prompt context.
- Cache: Ephemeral derived data, such as embedding indexes and pre-parsed schemas, that can be recomputed without losing task progress.
- Long-term memory: Cross-session episodic or semantic knowledge retrieved across distinct tasks, strictly decoupled from per-task execution state.
When discrepancies occur between a model’s conversational context and saved filesystem records, the durable run folder and execution manifest remain the authoritative source of truth.
How Does AI Agent Infrastructure Work?
A single pass through an agent loop consists of five sequential stages. The underlying infrastructure coordinates every transition, enforcing operational boundaries and recording state until the objective finishes or a budget trigger halts execution.
| Stage | What happens | What the infrastructure does |
|---|---|---|
| 1. Receive | A task arrives with defined objectives and constraints | Validates parameters and initializes wall-clock, token, and cost budgets |
| 2. Load | The agent prepares for the next step | Hydrates durable run state, recent step summaries, and relevant file paths |
| 3. Plan | The model decides the subsequent action or concludes | Dispatches the assembled prompt to the model inference endpoint |
| 4. Act & Observe | The agent executes a tool and evaluates the observation | Runs the tool in an isolated runtime and returns filtered output |
| 5. Save | The turn completes | Writes outputs atomically and updates the durable execution manifest |
Stage 5 represents the core capability absent from stateless serving pipelines. If an agent maintains state exclusively within its prompt, an unexpected worker restart or network timeout permanently erases its progress. Writing structured checkpoints after each completed turn establishes a reliable recovery baseline on disk.
To make recovery deterministic, the orchestration system assigns an incremental sequence number to every completed step in an append-only run manifest. When a crash occurs, the recovery manager reads this manifest to locate the last validated checkpoint. For read-only operations, such as inspecting a database schema or checking file metadata, the agent can safely re-execute the step. For operations that modify external resources, such as creating files or mutating database records, the infrastructure checks whether disk artifacts already exist before permitting a re-dispatch. This inspection prevents duplicate execution of non-idempotent tool actions.
The execution loop also grows heavier with every turn if intermediate outputs accumulate unchecked. As context length expands, model inference latency increases and reasoning quality can degrade. Systems running LLM-powered autonomous agents require strict limits on tool output size and explicit context-compaction routines to prevent runaway resource consumption.
Types of Agentic AI Architecture
System designers choose an agent topology based on task complexity, execution latency requirements, and necessary permission boundaries. While selecting an LLM agent architecture is partly a prompting and reasoning design choice, each architectural pattern imposes distinct demands on compute isolation, state management, and inter-agent communication.
Single-agent architecture
In a single-agent architecture, one model instance manages the entire workflow. It interprets the initial prompt, selects tools, parses observations, and maintains reasoning within its own context window. Infrastructure for this pattern remains lightweight: a single model endpoint, a local or remote tool server, and a storage directory for saving checkpoints.
The central vulnerability of the single-agent pattern is context exhaustion. If a tool returns hundreds of raw data rows or lengthy error traces, the context window fills with low-signal tokens that degrade the model’s ability to plan. In our research harness, a guard on file reads automatically limits data file inspections to the first 5 lines whenever a file exceeds 50 lines. Tools write complete analytical outputs directly to a designated results directory, returning only a disk path and summary metrics to the model. Similarly, our preview utilities enforce a hard limit of 20 rows per query.
These numerical thresholds represent practical operational defaults developed to protect model reasoning. A 20-row preview provides sufficient schema and value samples for the model to write accurate transformation scripts without consuming thousands of prompt tokens. Enforcing these constraints within tool server code ensures that model context remains protected even if the agent attempts an unconstrained read.
Multi-agent and orchestrated architecture
Multi-agent architectures separate responsibilities across specialized workers coordinated by a central orchestrator. The underlying infrastructure must spawn worker runtimes, supply each specialist with task-specific context, collect structured outputs, and handle individual worker crashes without interrupting the overarching workflow.
In our production setup, each specialist executes as a separate child process initialized with only the context necessary for its assigned sub-task. Each specialist dispatch carries a strict wall-clock timeout of 600 seconds. This timeout serves as a safety bound: it terminates hung mathematical routines, infinite retry loops, or frozen database connections, while leaving ample time for complex spatial computations. If a child process is terminated by the timeout handler, the orchestrator receives a structured error payload and chooses whether to adjust parameters, retry the step, or assign the work to an alternative tool.
Inter-agent communication introduces significant coordination overhead. When deploying collaborative AI agents, workers cannot rely on shared memory or implicit conversational history. Information handoffs must follow explicit, structured schemas. In our harness, specialists return a concise JSON summary capped at 8,000 characters, writing full data tables and intermediate logs to disk files. This 8,000-character cap accommodates comprehensive analytical summaries while preventing any single specialist from consuming a disproportionate share of the orchestrator’s context window.
Process isolation must not be confused with agent specialization. Agent specialization is a prompt and tooling abstraction that defines what an agent does. Process isolation is an operating-system boundary that enforces separate memory spaces, distinct process IDs, and independent lifecycles. Running specialists in isolated processes guarantees that a segmentation fault, memory leak, or unhandled exception in one worker cannot corrupt the orchestrator or terminate sibling tasks. When specialists return conflicting results, the orchestrator applies deterministic validation schemas or dispatches an evaluation sub-task to reconcile discrepancies.
Hybrid architectures combining both patterns
Complex production platforms typically combine single-agent and multi-agent patterns into layered hybrid systems. The Geocluster Research Harness implements a four-tier operational architecture designed to enforce least-privilege access across diverse operational roles:
- User interface agent: Interacts directly with the operator to clarify requirements and present completed summaries; possesses no terminal access and cannot write to the filesystem.
- Orchestrator: Formulates high-level execution plans and monitors progress; possesses dispatch permissions but cannot invoke analysis tools directly.
- Domain specialists: Execute data processing, spatial indexing, and statistical modeling; restricted strictly to read-only access on source repositories and isolated write access within the task run directory.
- Environment manager: A dedicated, single-purpose worker permitted to install dependencies into an isolated runtime; records every installation event in an immutable audit log.
This four-layer topology establishes an application-level threat model that restricts the blast radius of any individual failure or model hallucination. An agent parsing untrusted external data cannot alter environment packages, while the orchestrator cannot directly execute operating system commands. However, application-level role separation is not a substitute for container or virtual machine boundaries. Operating system account permissions, kernel namespaces, and strict filesystem access controls provide the ultimate security perimeter.
| Architectural Pattern | State Storage Location | Infrastructure Demands | Primary Failure Mode |
|---|---|---|---|
| Single-Agent | Active context window and local checkpoint | Low: single execution loop and basic tool runtime | Context exhaustion from large tool outputs |
| Multi-Agent | Structured handoffs and shared task files | High: process lifecycle management, IPC, and timeouts | Coordination latency and handoff schema drift |
| Hybrid Layered | Orchestrator manifest and specialist artifacts | Moderate to High: distinct process roles and sandboxes | Integration complexity and cross-layer state tracking |
Key Components of an AI Agent Infrastructure Stack
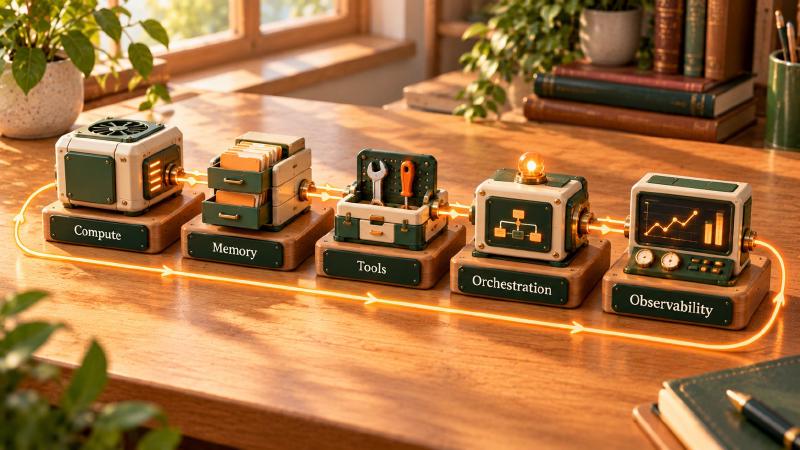
A comprehensive ai agent infrastructure stack comprises five foundational layers. Deficiencies in any single component manifest as operational failures during long-running tasks.
| Component | Core Responsibility | Failure Mode Without Component |
|---|---|---|
| Compute | Executes model inference and tool code runtimes | Resource starvation and blocked execution queues |
| State and memory | Preserves task progress and artifacts across turns | Lost work and forced restarts following crashes |
| Tool and API layer | Exposes external capabilities within verified boundaries | Unauthorized filesystem access and command injection |
| Orchestration and control | Schedules dispatches and enforces operational budgets | Runaway execution loops and runaway API expenditures |
| Observability | Records structured logs, traces, and evaluation data | Unexplainable failures and silent data leakage |
Compute for model inference and tool execution
Agentic systems demand two distinct compute profiles. The first profile handles model inference, which connects to hosted cloud endpoints or local acceleration clusters, as described in guides to LLM infrastructure. The second profile executes tool code, which is frequently overlooked during infrastructure sizing.
Tool execution involves running arbitrary scripts, querying databases, and transforming large spatial rasters. These workloads compete directly for CPU, memory, and disk bandwidth. In our tool server architecture, every tool invocation executes within a managed thread pool. By default, the system enforces a global limit of 8 concurrent worker threads and a per-conversation limit of 4 concurrent calls. This throttling prevents a single complex analytical task from monopolizing host compute and starving concurrent user sessions.
State and memory persistence across steps
Persisting state requires determining what data must survive a process restart, where that data resides, and how it is reloaded during recovery.
In our production deployment, the Geocluster tools provision an isolated run folder for each active task. Every analytical artifact, temporary script, and output table lands exclusively within that directory. File writes utilize atomic operations: data is written to a hidden temporary file on the same filesystem and synchronized to disk before executing an atomic rename to the target path. This protocol guarantees that worker processes reading outputs never encounter half-written or corrupted files after an unexpected crash. Caching layers in memory store only discardable index data that can be recomputed from disk artifacts during startup.
The orchestrator also maintains a rolling execution log within its operational context: the last 20 dispatches, complete with objective, execution status, and duration metrics. When context compaction truncates earlier conversational turns, this structured summary ensures that the agent retains an accurate record of completed steps.
Tool and API integration layer
The tool integration layer translates model tool calls into concrete software actions. Because this layer bridges non-deterministic model outputs with operating system capabilities, it requires strict operational guardrails. The Model Context Protocol provides an open specification for tool discovery and JSON-RPC communication between models and external systems.
However, a communication protocol does not implement security boundaries; that responsibility falls entirely on the tool host. Every file path received by our tool server undergoes canonical resolution via realpath, following all symlinks and rejecting any request that resolves outside the designated task workspace. Similar architectural precautions are mandatory when running a local MCP server that reads your files: path verification must always validate the resolved physical filesystem location rather than trusting raw path strings. Sensitive administrative tools, such as package installation utilities, accept no arguments from the model, eliminating the possibility of prompt injection steering downloads to untrusted repositories.
Tool responses must also be formatted carefully. Language models interpret textual summaries literally. In one documented incident, a result that said “1 item” for 86 records led an agent to conclude that mineral data was nearly absent from the study area. Tool return schemas must present data counts and structural dimensions explicitly to prevent downstream reasoning errors.
Orchestration and control layer
The orchestration layer governs execution flow, validates inter-step dependencies, and enforces system boundaries. In effective implementations of AI orchestration, deterministic software rules oversee stochastic model decisions.
Within an enterprise ai agent orchestration infrastructure, the orchestrator operates without direct tool execution capabilities, functioning purely as a dispatch and verification engine. Timeouts are detected by monitoring operating system process exit states rather than parsing stdout logs. In an early iteration of our harness, the orchestrator scanned console output for the substring “Command timed out”. When an inner script emitted that exact phrase as part of a benign log message, the orchestrator triggered a false timeout and prematurely aborted a healthy analysis. Modern runtimes rely strictly on operating system signals and process return codes.
Monitoring and observability for multi-step behavior
Emitting a single log entry per HTTP request is inadequate for workflows that span dozens of autonomous tool calls. Debugging agentic systems requires an observability framework that captures the complete causal chain of events.
The Geocluster tool server records structured log events marking the entry, parameters, duration, and completion code of every tool invocation. Concurrently, our runtime aggregates token consumption and financial cost per dispatch, surfacing real-time expenditures within the operator dashboard. In Groundtruth, Eigenform’s open source dynamic benchmark, the execution harness captures the complete raw event stream for every benchmark question evaluated.
Capturing granular event traces is the only reliable method for diagnosing subtle operational failures. During an evaluation suite run, we discovered agents reaching their own grading rubrics after an exploratory search agent traversed parent directories into an unprotected rubric folder on 13 of 50 test questions. Because the agent’s final answers were exceptionally accurate, traditional accuracy metrics failed to indicate any problem. Only inspecting the causal event stream revealed the unauthorized access, highlighting why end-to-end tracing is an indispensable component of agentic infrastructure.
Production observability requires maintaining three distinct data categories:
- Structured logs: Timestamped records capturing individual events, such as worker process initialization, tool execution start, and exit codes.
- Distributed traces: Causal spans linked by a persistent trace ID, connecting the user prompt through orchestrator dispatches, specialist executions, tool invocations, and filesystem writes.
- Evaluation event streams: Verifiable, immutable logs capturing complete prompt text, tool inputs, and raw outputs used for benchmark validation and compliance auditing.
How to Build Infrastructure Solutions for AI Agents
Engineering infrastructure solutions for ai agents requires resolving four foundational architectural decisions before deploying autonomous agents to production environments.
Defining state and memory requirements for the task
Begin by cataloging the exact state requirements of the target workload. Determine which outputs must persist on disk across host reboots, which variables can be recreated dynamically, and which intermediate tokens should be dropped immediately after consumption. Large datasets and intermediate analytical tables should reside in filesystem storage, passing lightweight path references and structural summaries to the model.
Designing for state durability enables reliable task resumption. When a specialist agent in our environment encounters a missing Python dependency, it emits a structured capability gap notification. The orchestrator receives the notification, dispatches the environment manager to install the package, and re-dispatches the specialist in a fresh operating system process using a resume flag. This fresh process initializes with clean memory, avoiding memory leaks or stale state, while loading the saved run manifest and prior file artifacts to continue execution without re-running earlier steps.
Choosing single-agent versus multi-agent infrastructure
Default to a single-agent architecture until operational constraints dictate a split. Introduce multi-agent orchestration only when context windows become saturated with intermediate data, or when specific sub-tasks require distinct operating system privileges. In our early geological reasoning harness, the transition to multi-agent dispatch became necessary when single-agent context windows were overwhelmed by column distributions, coordinate lists, and raw data previews before mathematical synthesis could begin.
Every additional agent introduced to a system adds inter-process communication latency, serialization overhead, and potential points of failure. Add specialist workers only when the functional gains in context clarity or security isolation outweigh the added operational complexity.
Planning for tool integration and failure handling
Architect the tool layer under the assumption that every external integration will periodically fail. Tool endpoints must return structured, informative error messages that explain the cause of failure and suggest remediation steps, because language models rely entirely on return text to plan corrective actions. Enforce strict execution timeouts on every external call, and define explicit fallback behaviors within the orchestrator for handling failed steps.
Operational experience shows that many apparent model reasoning errors are actually infrastructure failures. False timeouts, dropped socket connections, truncated data files, and unhandled tool exceptions frequently manifest as a confused or looping agent. A sophisticated model running on infrastructure that fails to persist state reliably or enforce execution boundaries cannot achieve production-grade consistency.
To illustrate how these components interact during an operational failure, consider a spatial data analysis workflow:
- A specialist agent begins processing a massive geochemical dataset, writing intermediate GeoJSON clusters to disk.
- The specialist process exceeds its 600-second execution budget during a spatial boundary calculation and is terminated by the host monitor.
- The orchestrator catches the non-zero exit code, examines the append-only task manifest, and confirms that the intermediate GeoJSON file was written and synced atomically.
- Instead of discarding the task, the orchestrator adjusts the processing chunk size and re-dispatches the specialist with a resume flag in a fresh child process.
- The new specialist process reads the existing GeoJSON artifact from the run folder and resumes computation at the subsequent analysis step.
- The causal tracing system links both execution spans under a single trace ID, allowing engineers to audit the timeout event and verify that no duplicate processing occurred.
Building in observability from the start
Implement end-to-end tracing before executing the first automated agent tests. Inspect full event traces during development rather than reviewing only final task outputs, because multi-step agents frequently arrive at plausible conclusions through flawed or unauthorized intermediate reasoning.
Detailed event traces also serve as the foundation for automated testing and verification. Replaying recorded event traces through a standardized agent evaluation framework allows teams to measure performance regression, verify tool security boundaries, and benchmark agent reliability across successive model updates.
FAQs About Agentic AI Infrastructure
Is agentic AI infrastructure different from standard cloud infrastructure?
Agentic infrastructure differs from standard cloud setups in how it composes and bounds services rather than where it runs. While cloud platforms provide raw compute, storage, and networking, agentic infrastructure must manage non-deterministic multi-step loops. It coordinates durable state checkpoints across turns, isolates dynamic tool execution, enforces operational budgets, and records causal event traces across extended workflows.
Can existing LLM infrastructure be adapted for agentic workloads, or does it need to be rebuilt?
Existing model-serving infrastructure can generally be retained for model inference. However, teams must build stateful orchestration layers around those inference endpoints. That surrounding architecture requires dedicated tool execution runtimes, atomic filesystem checkpointing, process lifecycle supervisors, and causal tracing collectors. Rebuilding is necessary only when existing serving platforms cannot support streaming tool definitions or enforce granular execution timeouts.
How much does agentic AI infrastructure typically cost compared to single-turn LLM infrastructure?
Agentic workloads cost significantly more per task than single model calls due to cumulative context growth and multi-step execution. In an uncompacted 10-step agent loop, repeatedly re-reading prior tool observations can expand token volume from 2,000 tokens on step one to over 30,000 tokens on step ten. Incorporating aggressive context compaction and offloading bulk data to disk minimizes quadratic token expenses.
What infrastructure providers or platforms support agentic AI today?
Production agentic stacks typically combine cloud model endpoints from providers such as AWS Bedrock or Azure AI with specialized open runtime layers. Teams deploy containerized execution environments using Docker or Kubernetes, coordinate workflows through frameworks like LangGraph or custom orchestrators, implement tool integration via Model Context Protocol servers, and collect causal traces using OpenTelemetry backends.