TL;DR
- A machine learning model is a program that learns from examples to make predictions. Evaluation metrics in machine learning score how good those predictions are, and different jobs need different scores.
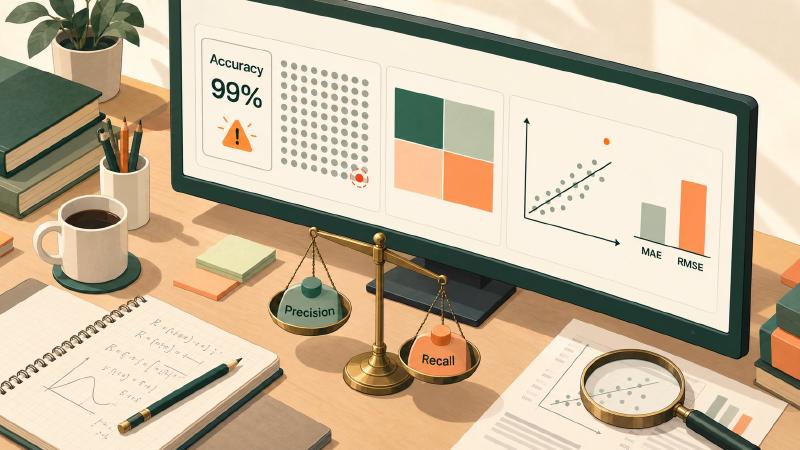
- A high score can hide a useless model: if 1 transaction in 100 is fraud, a model that never spots fraud is still right 99% of the time.
- Choose the score based on which mistakes hurt most, because teams improve and compare their models by that score.
Key Takeaways
- Accuracy is often the wrong default. When the cases that matter are rare, a model can be 99% accurate while catching none of them.
- Precision and recall trade off against each other. Precision asks how many alerts were right, recall how many real cases were caught; raising one usually lowers the other, like a smoke alarm that is too jumpy or too quiet.
- Scores for predicting numbers treat big misses differently. When a model predicts numbers such as prices, one common score barely notices a single big miss while another punishes it: in our example, 2.8 against 4.56.
- The right score follows from what mistakes cost, not from habit. A missed fraud and a false alarm rarely cost the same, and that difference should decide the score you improve.
Each of the evaluation metrics in machine learning rewards a particular kind of behaviour, so a model can look strong on one and still fail at the problem you care about.
We run into this on our own benchmark. Groundtruth, Eigenform’s open source dynamic benchmark, grades AI models on 150 geology questions, and the choice of score shaped every result we published. Below are the key metrics for classification (sorting cases into categories), regression (predicting numbers) and ranking (putting results in order), and how to choose between them.
What Are Evaluation Metrics in Machine Learning?
An evaluation metric in machine learning is a number that measures how well a model’s predictions match the correct answers on data it did not train on. Accuracy, precision, recall, mean absolute error and R² are common examples. Each one reflects a different idea of a good prediction, so it has to match the task.
Model evaluation metrics are not the same as the loss function a model minimises during training. The loss has to be smooth enough to optimise; the metric has to mean something to the people who use the model. Sometimes they coincide, as with mean squared error, but often they do not: most classifiers train on log loss and are judged on precision or recall.
Metrics are computed on a held-out test set, data kept aside during training, so the score reflects new cases rather than memorised ones. The definitions below follow the standard implementations in scikit-learn.
Key Evaluation Metrics in Machine Learning
The different evaluation metrics in machine learning fall into families by task: classification metrics judge labels, regression metrics judge numbers, and ranking metrics judge order. Picking a metric is one decision within AI model evaluation, alongside the choice of test data, benchmarks and human review.
Evaluation metrics for classification in machine learning
Classification metrics start from four counts. A true positive is a real case the model flagged, a false positive is a flag on a non-case, a false negative is a real case the model missed, and a true negative is a non-case left alone.
| Metric | Question it answers | How it is computed | Watch out for |
|---|---|---|---|
| Accuracy | How many predictions were right? | Correct predictions ÷ all predictions | Misleading when one class is rare |
| Precision | Of everything flagged, how much was right? | True positives ÷ all flagged | Ignores the cases the model missed |
| Recall | Of all real cases, how many were caught? | True positives ÷ all real cases | Ignores false alarms |
| F1 score | One number that balances both | Harmonic mean of precision and recall | Hides which side is weak |
| ROC-AUC | Does the model rank real cases above non-cases? | Area under the ROC curve, from 0.5 (random) to 1.0 (perfect) | Can look strong on heavily imbalanced data |
A worked example shows why accuracy misleads. Take 1,000 transactions, 10 of them fraud. A model that never flags anything is right 990 times, so its accuracy is 99.0%, and its recall is zero.
Now take a model that flags 30 transactions, 8 of them real fraud. Its accuracy drops to 97.6%, yet it catches 8 of the 10 frauds (recall 80%), and 8 of its 30 flags are right (precision 26.7%), for an F1 score of 0.40. On accuracy the useless model wins; on recall the useful one does.
When the class you care about is rare, the precision-recall curve usually says more than the ROC curve, because a ROC curve gives credit for the huge number of easy true negatives.
Regression evaluation metrics
Regression models predict numbers, so their metrics measure distance from the true value.
| Metric | What it measures | Units | Effect of one large error |
|---|---|---|---|
| MAE (mean absolute error) | Average size of the errors | Same as the target | Counted in proportion |
| MSE (mean squared error) | Average squared error | Squared units | Strongly amplified |
| RMSE (root mean squared error) | Square root of MSE | Same as the target | Amplified, but readable |
| R² (coefficient of determination) | Share of the target’s variation the model explains | None; 1 is perfect, 0 matches predicting the average | Pulled down, can go negative |
Suppose five predictions miss by 1, 1, 1, 1 and 10 units. The MAE is 2.8, the MSE is 20.8 and the RMSE is 4.56. The single large miss barely moves MAE but dominates RMSE, which is why RMSE suits problems where big errors are disproportionately costly and MAE suits problems where every unit of error costs the same.
Ranking and other task-specific metrics
Search and recommendation models are judged on order. Precision@k and recall@k look only at the top k results, mean average precision (MAP) rewards relevant items ranked early, and NDCG (normalised discounted cumulative gain) discounts relevant items the further down the list they appear.
Generated text needs other measures again. BLEU and ROUGE count word overlap with a reference text, which works for translation and short summaries but not for open-ended answers.
For free-text answers we use rubric scoring. Groundtruth grades each answer from 0 to 10 against a question-specific rubric, and a pairwise mode asks which of two answers is better, run twice with the order swapped to cancel position bias.
How to Choose Evaluation Metrics for Your Model
Choosing among evaluation metrics in machine learning comes down to a few questions, asked in order: what kind of task it is, how balanced the classes are, and what each kind of error costs.
Start from the task type
The task narrows the family. Labels call for classification metrics, numbers for regression metrics, ordered lists for ranking metrics, and free text for rubric or judge-based scores. No single metric works across all of them.
Check how balanced the classes are
If the cases you care about are a small share of the data, accuracy will mostly measure the easy majority. Report precision and recall, or the precision-recall curve, alongside it, and look at the confusion matrix before trusting any single number.
Price the errors: false positives against false negatives
The decisive question is what each mistake costs in practice. A missed fraud loses money; a false alarm costs a reviewer’s time. Write both costs down, then let them pick the metric.
| Situation | Costliest error | Metric to lead with |
|---|---|---|
| Fraud or disease screening | Missing a real case (false negative) | Recall, with precision as a check |
| Spam filtering, automated rejections | Flagging a good item (false positive) | Precision |
| Balanced classes, similar error costs | Neither dominates | Accuracy or F1 score |
| Forecasts where big misses hurt most | Large errors | RMSE |
| Forecasts where every unit costs the same | Any error, equally | MAE |
| Search results and recommendations | Wrong items near the top | NDCG or precision@k |
Check the metric’s resolution before trusting a gap
A metric is only as precise as the test set behind it. On Groundtruth, with 50 questions per question set, the smallest mean gap we could tell apart from noise was 0.27 to 0.45 points on the 0 to 10 scale, depending on the set.
Across eight models and 1,200 graded answers, only 2 of the 7 gaps between neighbouring models cleared that bar. Before reading a leaderboard, check its benchmark statistical significance: a difference smaller than the noise floor is not a difference.
Keep measuring after launch
A metric chosen at launch stays meaningful only while new data looks like the test set. Tracking the same metric on fresh, labelled samples is how model drift shows up before users notice it.
Choosing LLM Evaluation Metrics
The judgment call behind evaluation metrics in machine learning shows up again in LLM evaluation metrics, just with different numbers. A free-text answer has no single correct label, so each Groundtruth rubric has a gate component worth 2 to 4 points: if the answer misses the claim the question exists to test, the whole answer scores zero, however fluent the rest.
Grading thousands of answers by hand is slow, so most teams score them with an LLM judge, another model that applies the rubric. That judge brings its own biases, which then have to be measured like any other metric.
Metric choice, test data and judging rules belong together in an AI evaluation framework, so every model is measured the same way each time it changes.
FAQs
Is a loss function the same as an evaluation metric?
Not always. The loss function is what the model minimises during training, so it must be smooth enough to optimise. The evaluation metric is what people use to judge the result. Mean squared error can serve as both, but classifiers usually train on log loss and are judged on precision, recall or F1 score.
What is the difference between precision and recall?
Precision is the share of the model’s positive predictions that were correct: of everything it flagged, how much was right. Recall is the share of real positive cases the model found: of everything it should have flagged, how much it caught. Raising the decision threshold usually increases precision and lowers recall, and the reverse.
What evaluation metrics are used for classification?
The core classification metrics are accuracy, precision, recall, the F1 score and ROC-AUC, all built from the confusion matrix of true and false positives and negatives. For imbalanced data, precision, recall and the precision-recall curve are more informative than accuracy, which can stay high while the rare class is missed entirely.
What evaluation metrics are used for regression?
The standard regression metrics are mean absolute error (MAE), mean squared error (MSE), root mean squared error (RMSE) and R². MAE treats every unit of error equally, MSE and RMSE punish large errors much more heavily, and R² reports how much of the target’s variation the model explains compared with predicting the average.
How do you choose the right evaluation metric?
Start from the task type, then check whether the classes are balanced, then compare what a false positive and a false negative cost in practice. Lead with the metric that tracks the costliest error, report one or two others beside it, and check that the test set is large enough to separate real differences from noise.