TL;DR
- Generative AI’s biggest challenges cluster around reliability (hallucination, non-determinism), risk (data privacy, security, IP and bias) and organizational readiness (cost, integration, skills, adoption).
- Each has a practical mitigation, but none of them go away just because a model gets more capable: they need to be designed for, not assumed away.
Key Takeaways
- Hallucination and non-determinism are technical, but manageable. Grounding, evaluation and human review reduce the risk without eliminating the underlying behavior.
- Data privacy, security and IP risk require policy as much as technology. Access controls and usage policy matter alongside technical safeguards.
- Cost and integration challenges are usually underestimated at pilot stage. What works at small scale often does not transfer cleanly to production cost and complexity.
- Most challenges compound if left unaddressed rather than resolving on their own. Waiting for better models to fix these issues tends to delay the mitigation work that actually solves them.
Enterprise teams deploying foundation models into customer-facing production face an operational gap between pilot demonstrations and enterprise workloads. While single-turn conversational prototypes suggest smooth intelligence, deploying automated pipelines and tool-using agents exposes structural vulnerabilities. Addressing these generative ai challenges requires engineering leaders to establish repeatable, empirical safeguards.
This guide focuses on text-based and tool-using language model systems entering production, though its architectural principles apply across multimodal systems and autonomous agents. In lightweight pilots, occasional factual errors or latency spikes are tolerable. In production, where models execute database queries, process customer records, and generate correspondence, errors cascade into compliance liabilities and unbudgeted cloud costs.
Systematic deployment demands that organizations classify vulnerabilities, quantify error rates, and implement defense-in-depth controls before software reaches users. The nine risks analyzed below represent a practical operational taxonomy grouped across reliability, compliance, infrastructure, and organizational readiness, rather than an exhaustive theoretical ranking.
What Are Generative AI Challenges?
Generative AI challenges are the technical, regulatory, and organizational obstacles that prevent artificial intelligence models from operating reliably, securely, and economically in production environments. These hurdles encompass factual hallucinations, non-deterministic responses, proprietary data leakage, intellectual property exposure, infrastructure cost overruns, and internal organizational friction across enterprise deployments.
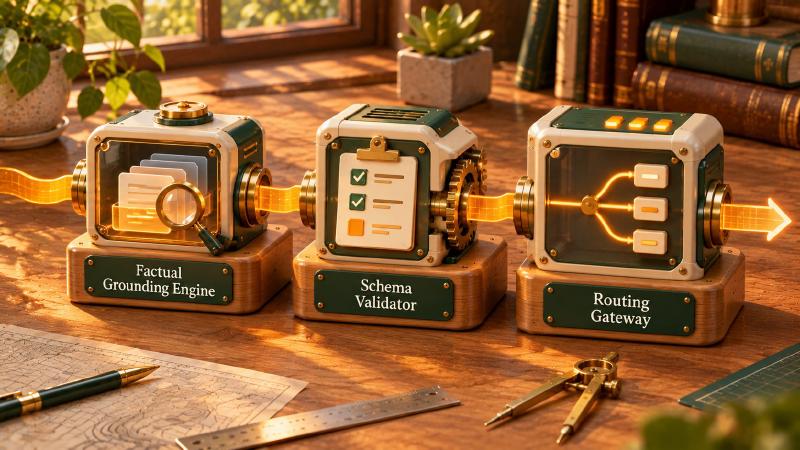
Addressing these generative ai challenges requires engineering teams to move beyond ad-hoc prompting and build structured defensive harnesses that mitigate operational risks and support enterprise adoption strategies. Production systems rely on automated evaluation gates, strict data access boundaries, dynamic routing layers, and disciplined change management frameworks.
When engineering managers ask what are some of the challenges of generative ai during architectural reviews, discussions usually center on output accuracy alone. However, production failures stem equally from fragile system integrations, latency spikes, unbudgeted inference expenses, and user hesitation among frontline staff.
| Risk Category | Primary Challenge | Root Cause | Engineering Mitigation | Intended Risk Reduction |
|---|---|---|---|---|
| Reliability | Hallucination | Probabilistic token sampling | Source-grounded evaluation and retrieval | Reduces factual errors and catches unsupported claims |
| Reliability | Non-Determinism | Temperature and decoding variance | Schema enforcement and multi-run voting | Constrains syntax and reduces downstream parser crashes |
| Compliance | Data Privacy | Context leakage and training ingestion | Local sanitization and VPC endpoints | Limits exposure of confidential enterprise data |
| Compliance | IP and Copyright | Training data provenance ambiguity | Synthetic generation and license logging | Reduces commercial licensing and copyright exposure |
| Compliance | Bias and Skew | Distributional imbalance in pre-training | Subgroup benchmarking and fairness gates | Helps detect and mitigate demographic disparities |
| Infrastructure | System Integration | Brittle API schemas and latency | Microservice wrappers and retry queues | Improves fault tolerance during upstream outages |
| Infrastructure | Cost at Scale | Unbounded context and token volume | Multi-model routing and caching layers | Limits unbudgeted inference spend at high volume |
| Organization | Skills Gap | Novel evaluation and prompting paradigms | Internal benchmark suites and training | Develops internal technical ownership across teams |
| Organization | Change Resistance | Misaligned workflows and user distrust | Human-in-the-loop sign-offs and pilots | Supports team adoption and workflow trust |
Generative AI Challenges: 9 Enterprise Risks and Practical Mitigations
Hallucination and factual inaccuracy
Hallucination occurs primarily because autoregressive language models operate by predicting mathematically probable tokens rather than querying verified facts. When an input prompt lacks sufficient reference context or touches gaps in a model’s parametric memory (the static knowledge encoded in neural network weights during training), the system generates fluent, grammatically convincing statements that are completely untrue. In enterprise settings such as legal document review, financial reporting, or customer triage, ungrounded outputs can cause severe reputational and economic harm.
Mitigating factual inaccuracy requires teams to ground generation strictly in verifiable source documents using retrieval-augmented generation (RAG). However, retrieving excerpts is insufficient without automated verification, because retrieval can return incomplete or irrelevant passages. Teams should implement source-grounded evaluation frameworks that score generated claims directly against retrieved reference text, prompting the model to abstain or escalate when evidence is missing.
Rigorous verification requires independent testing pipelines. We observed this challenge directly when evaluating frontier models across Groundtruth’s 150 complex domain reasoning tasks: models frequently cited non-existent journal articles and invented domain thresholds with high confidence. To solve this, teams must learn how to test generative AI using systematic assertion suites, factual consistency rubrics, and synthetic perturbations rather than relying on qualitative spot-checks.
Non-determinism and inconsistent output
Standard large language model inference is inherently non-deterministic. Identical prompts can yield different text completions across successive API calls because decoding algorithms sample from token probability distributions. Even when temperature is set to zero, underlying floating-point non-associativity across parallel GPU clusters can introduce minor numerical variations in token logits. For software architectures expecting predictable JSON structures or deterministic business logic, this variance breaks downstream parsers and degrades system reliability.
Software developers often underestimate this variance by testing a single prompt pass during development. In production, error rates compound across sequential steps. If each step succeeds independently with 95 percent probability, an unbroken eight-step chain has a 0.95^8 ≈ 66.3 percent success rate, meaning roughly 34 percent of runs encounter at least one step failure. When errors compound, workflow failures can exceed 40 percent. Reducing brittle dependencies requires wrapping model outputs in strict structural schemas using Pydantic, JSON Schema, and grammar-constrained decoding (which restricts token logits to valid grammar).
Beyond structural constraints, testing protocols must evaluate output distribution over repeated invocations. Critical operational steps should employ majority-voting ensembles or self-consistency loops, executing multiple independent passes to confirm consensus before triggering downstream database actions.
Data privacy and security risk
Enterprise adoption often stalls over confidential data exposure. When employees paste internal strategy documents, customer personally identifiable information, or source code into commercial model endpoints, data handling depends on provider terms. On consumer tiers, inputs may be logged, reviewed, or ingested into future training datasets. Furthermore, malicious prompt injection attacks can manipulate prompts to override system instructions and exfiltrate private conversation history.
Organizations must enforce strict data boundaries before deploying generative tools to staff. Technical controls should route requests through private virtual cloud endpoints where vendors contractually guarantee zero data retention and exclude customer inputs from model training. Sensitive entities like account numbers, names, and passwords must pass through local deterministic sanitization masks prior to leaving corporate boundaries.
Software architectures should also isolate retrieval databases with granular role-based access controls. An AI agent should only retrieve documents that the querying user has explicit permission to inspect, preventing horizontal privilege escalation across departments.
Intellectual property and copyright risk
Foundation models are pre-trained on billions of internet texts, codebases, and artistic works, frequently without explicit licensing agreements from original creators. If a generative system memorizes and reproduces copyrighted source material verbatim, the enterprise deploying the application risks copyright infringement claims. This uncertainty complicates intellectual property ownership for software, marketing copy, and synthetic media generated by AI.
Engineering teams can mitigate copyright exposure by configuring strict retrieval and post-processing filters that detect n-gram overlap between model responses and public corpora. When generating proprietary code or specialized text, companies should prefer models whose pre-training datasets are documented and commercially indemnified by the foundation vendor.
Where licensing remains ambiguous, enterprise workflows should maintain human authorship logs. Requiring developers and writers to review, modify, and sign off on machine-generated drafts creates a defensible boundary between synthetic assistance and human-directed intellectual property.
Bias and fairness issues
Because foundation models mirror the demographic biases, cultural stereotypes, and historical skews present in their training corpora, unconstrained systems reproduce discriminatory patterns. When utilized for screening resumes, assessing credit risk, or triaging customer tickets, an untuned model may systematically disadvantage specific protected cohorts despite receiving identical objective qualifications.
Addressing algorithmic bias requires measuring model behavior across distinct demographic and contextual cohorts rather than tracking aggregate performance metrics. Evaluating an entire system solely on average accuracy frequently conceals severe degradation within smaller demographic subgroups. Teams must establish held-out bias evaluation sets that test model decisions while holding qualifications constant and perturbing demographic markers.
Developing equitable AI systems requires embedding fairness measurement directly into early prototyping and deployment gates. Setting explicit parity thresholds across candidate groups ensures that models flagging disproportionate failure rates never advance to live customer environments.
Integration with existing systems
Connecting stochastic language models to rigid legacy databases, enterprise resource planning suites, and customer relationship systems introduces unexpected architectural friction. Language models produce unstructured natural language, whereas relational software requires strict data types, relational foreign keys, and low-latency round trips. Brittle integrations lead to connection timeouts, hung background worker processes, and unhandled parsing exceptions.
To integrate generative components safely, developers should treat language models as asynchronous microservices rather than synchronous library calls where latency allows. Every tool call executed by an agent must pass through an intermediary validation layer that validates function arguments, checks parameter boundaries, and handles service timeouts gracefully.
Engineering teams should also implement automated fallback paths. When a foundation model returns an unparseable response or violates API contracts, the system should catch the exception, re-prompt the model with specific schema corrections, or fall back to deterministic rule-based algorithms without crashing the parent application.
Cost at scale
While early prototyping with commercial frontier model APIs appears inexpensive at low query volumes, production inference expenses scale rapidly. An enterprise application serving tens of thousands of active users with complex multi-turn retrieval-augmented generation can generate thousands of dollars in daily API expenses. Long context windows, excessive system prompts, and unoptimized autonomous loops compound token consumption rapidly.
Controlling cloud expenses requires organizations to understand the underlying LLM infrastructure components that dictate compute pricing, context caching, and GPU memory utilization. Instead of routing every basic customer query to an expensive frontier model, systems should implement dynamic model routing architectures. Simple classification and extraction tasks can be handled by compact, fine-tuned open-source models, reserving frontier reasoning models for complex, ambiguous workflows.
System architects should also implement aggressive semantic caching layers. Storing embeddings of frequent user questions and caching deterministic completions prevents duplicate compute spending on identical queries, significantly lowering average cost per transaction.
Skills and talent gaps
Building production-grade generative software requires capabilities that differ from traditional software engineering. Teams accustomed to deterministic unit tests often struggle to design statistical evaluation rubrics, manage non-deterministic prompts, or debug subtle reasoning failures. Relying entirely on external vendors without internal competence leaves companies vulnerable to vendor lock-in.
Organizations should invest in cross-functional upskilling bridging software engineering, data science, and domain expertise. Product engineers must develop proficiency in synthetic evaluation generation, embedding selection, and automated grading architectures.
Teams should establish standardized internal benchmarking suites so developers can empirically test prompt changes and model upgrades against consistent company-specific datasets. This internal testing rigor ensures technical teams can assess third-party tools objectively rather than relying on vendor sales demonstrations.
Adoption and change management
The final barrier to generative AI success is organizational inertia and user skepticism. When leadership rolls out automated tools without clear operational objectives, employees oscillate between excessive trust and complete rejection. If an assistant produces early errors, frontline staff revert to manual processes, rendering software investments useless.
Overcoming organizational hesitation requires treating AI deployment as an organizational transformation initiative rather than an IT software push. Executive sponsors must define concrete operational objectives and articulate clearly what tasks the tool is intended to perform and where human expertise remains mandatory.
Structuring rollouts through a phased AI adoption framework enables teams to test systems within controlled pilot environments before broad enterprise deployment. Involving end users directly in designing evaluation rubrics fosters psychological safety, transparent feedback loops, and sustained operational buy-in.
How to Measure and Benchmark Generative AI Challenges
Tackling generative AI challenges requires continuous measurement rather than one-time fixes. Because foundation models evolve through upstream updates and input data distributions shift over time, systems that perform reliably at launch can silently degrade in production environments.
Building resilience requires testing models against specialized domain benchmarks measuring reasoning fidelity and factual precision. For example, testing models on Groundtruth, Eigenform’s open source dynamic benchmark, shows how domain evaluation uncovers reasoning failures that general academic benchmarks miss.
Teams evaluating foundation models can inspect verified performance across 8 leading models on the public Groundtruth benchmark documentation.
To examine how models compare under continuous testing, engineering leaders can review competitive rankings on the official model leaderboard to track reasoning consistency.
Production Telemetry and Drift Detection
Deploying generative models into production workflows requires continuous observability across token consumption, response latency, and factual reliability. Static unit tests conducted during development fail to detect changes in user behavior or gradual degradation in model performance.
Automated telemetry pipelines must track prompt distributions and response characteristics across every production endpoint. By deploying continuous monitoring frameworks, engineering teams can detect what is model drift in AI before performance degradation impairs mission-critical business workflows.
FAQs
What are the biggest challenges of generative AI?
The biggest challenges of generative AI include factual hallucinations, non-deterministic outputs, confidential data privacy risks, intellectual property ambiguities, unexpected cloud inference costs, and organizational resistance to workflow changes. Overcoming these hurdles requires structured retrieval grounding, schema-constrained decoding, strict access boundaries, multi-model routing, and systematic employee change management programs.
What are some of the enterprise-specific risks of generative AI?
Enterprise-specific risks include data leakage through third-party APIs, prompt injection vulnerabilities, copyright infringement from unvetted training data, and compounding multi-step agent failures. Organizations also risk regulatory non-compliance under emerging privacy laws, vendor lock-in from proprietary foundation models, and substantial operational disruptions caused by brittle legacy system integrations.
How do you reduce hallucination in generative AI?
You reduce hallucination by grounding model responses in authoritative retrieval documents using retrieval-augmented generation, constraining output decoding, and evaluating responses against automated rubric checks. Implementing independent verification gates that verify generated facts against retrieved source text helps verify that factual claims remain auditable before reaching production users.
What are the data privacy risks of generative AI?
Data privacy risks include employee inputs containing sensitive personal information being ingested into public training sets, conversational context leakage across multi-tenant environments, and unauthorized data retrieval by autonomous agents. Enterprises mitigate these risks by configuring private zero-retention cloud endpoints, enforcing local data redaction, and applying role-based access controls to retrieval indices.
How can organizations improve generative AI adoption?
Organizations improve generative AI adoption by establishing clear operational use cases, providing structured employee training, and designing intuitive human-in-the-loop validation workflows. Deploying software incrementally through measured pilot programs while demonstrating tangible productivity improvements builds user trust and fosters sustained organizational commitment across business departments.