TL;DR
- Generative AI implementation is the end-to-end process of moving an enterprise from a first use case to reliable, measured use across the business, not a single deployment step.
- Most of the real difficulty sits in scaling past one team, defining what success actually means, and sustaining the system once it’s live, not in getting a first pilot working.
Key Takeaways
- Enterprise implementation is harder than pilot implementation. Data governance, integration with legacy systems and cross-team coordination add complexity a single-team pilot doesn’t face.
- Scaling across business units requires repeatable infrastructure, not repeated one-off builds. Reusable evaluation, governance and integration patterns let successful pilots extend without starting from scratch each time.
- Success has to be measured against a defined baseline, not assumed. ROI and KPIs mean little without a pre-implementation baseline to compare against.
- Most implementation challenges are structural, not technical. Data readiness, integration and change management explain more failed implementations than model capability does.
Enterprise leaders recognize that generative AI implementation is an operational transformation rather than a standalone technology deployment. Proving that a foundation model can summarize text in a sandbox takes hours. Translating that capability into a reliable, enterprise-grade system embedded in daily operations requires systemic architectural changes.
Organizations that succeed treat implementation as a multi-stage engineering discipline. Specifically, that discipline connects unstructured business data and orchestrates legacy API integration. Furthermore, it enforces rigorous evaluation gates and aligns human workflows with model outputs across every participating department.
What is generative AI implementation and why it matters for enterprises
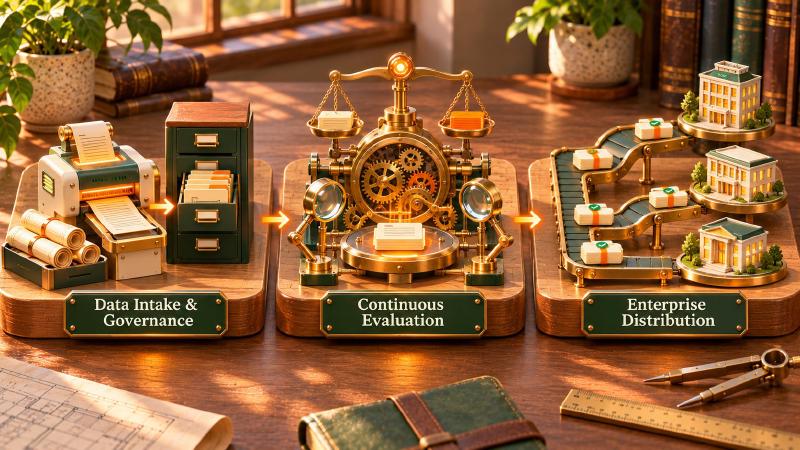
Generative AI implementation is the end-to-end process of integrating foundation models into business workflows, moving an organization from exploratory prototyping to reliable production use. Understanding how to implement generative AI requires establishing repeatable pipelines for data governance, system integration, continuous evaluation, and cross-functional change management to deliver measurable business value.
Moving from experimentation to core operations fundamentally alters technical constraints. A developer testing prompts works without SLAs, latency limits, or data boundary checks. In contrast, enterprise deployment requires high availability (such as 99.5% uptime). Systems must operate within strict latency budgets (often under 500 ms for interactive tasks) and maintain verifiable tenant isolation.
Generative AI matters for enterprises because it restructures how institutional knowledge gets applied. Rather than relying on manual file searches, organizations convert unstructured records into interactive intelligence layers. Consequently, that transformation accelerates decisions across customer operations, legal review, and product development, turning passive archives into active operational assets.
Challenges implementing generative AI solutions in the enterprise
Enterprise teams rarely fail because foundation models lack language capability. Instead, challenges implementing generative AI solutions stem from the organizational and architectural friction of large enterprises.
Data governance represents the first structural barrier. Enterprise repositories contain complex access control lists (ACLs), confidential personnel files, and non-public financial documents. When a retrieval-augmented generation (RAG) system ingests these stores, it must preserve underlying permissions. Therefore, unauthorized users must never retrieve protected records through natural language prompts.
Integration with legacy IT infrastructure poses an equally formidable obstacle. Most large companies operate a heterogeneous mix of microservices, on-premise databases, and monolithic ERP systems. Connecting non-deterministic AI outputs to rigid database schemas requires structured validation layers. These layers enforce valid JSON outputs and prevent malformed transactions.
Cross-team coordination further complicates deployment. Unlike a pilot built by an isolated data team, enterprise rollout involves engineering, security, compliance, legal counsel, and business unit leaders. If security teams lack visibility into data egress or legal teams cannot audit model outputs, deployment stalls regardless of technical readiness.
Finally, enterprise scale amplifies failure modes that remain invisible during small pilots. A 2% error rate in an internal tool testing 50 documents a week is manageable through informal review. However, that same 2% error rate on 100,000 daily customer interactions creates 2,000 operational defects every day, quickly overwhelming support teams.
Generative AI implementation strategy: how to implement generative AI
Navigating these obstacles demands a structured generative AI implementation strategy that moves deliberately from problem formulation to validated deployment. Attempting to build an all-encompassing enterprise platform before validating specific use cases consistently leads to stalled initiatives.
Selecting a specific, measurable use case
Successful teams resist building generic chatbots for the entire company. Instead, they identify tightly scoped workflows characterized by high frequency, predictable inputs, accessible source data, and clear error tolerances.
A strong initial use case targets a bounded task: triaging incoming supplier invoices, extracting key clauses from lease agreements, or drafting support responses from verified documentation. In each case, baseline cycle times and historical error rates already exist, providing an objective standard for improvement.
Assessing data and infrastructure readiness
Before writing prompts, teams must evaluate data quality and pipeline maturity. Generative systems require clean, structured, and accessible inputs. If source documents exist as scanned PDFs with poor optical character recognition (OCR) or conflicting versions, model outputs inherit those flaws.
Infrastructure readiness also encompasses compute and network constraints. Teams must decide whether to consume commercial models via managed APIs or host open-weights models (such as 8B or 70B parameter architectures) within their own virtual private cloud (VPC). API approaches minimize setup effort. In contrast, self-hosted models offer predictable inference costs and keep proprietary inputs within corporate perimeters.
Piloting narrowly before expanding
A pilot should run with a cohort of 10 to 25 domain specialists for 60 to 90 days. The objective is not merely proving technical feasibility, but understanding how human operators interact with generated outputs.
Embedding the pilot directly into operational software is the core mechanism of ai business integration, ensuring workers interact with AI outputs within familiar software interfaces rather than standalone web portals. Keeping workers inside their primary workflow maintains context and captures real feedback on output quality.
Building in evaluation and governance from the start
Evaluation cannot be deferred until after deployment. Teams must assemble a gold-standard evaluation set containing 50 to 100 representative task queries, paired with ground-truth reference answers and scored rubrics. Every model change, prompt refinement, or retrieval update must pass through this evaluation pipeline before reaching production users.
Adopting formal risk guidelines such as the NIST AI Risk Management Framework ensures governance, mapping, and risk tracking are embedded into system telemetry from day one. Integrating these checks early protects the enterprise against silent regressions as underlying models evolve.
| Dimension | Exploratory Sandbox | Narrow Departmental Pilot | Enterprise Production |
|---|---|---|---|
| User base | 1–5 developers | 10–25 domain specialists | 500+ employees or external clients |
| Data access | Static dummy samples | Curated department files with basic ACLs | Live enterprise repositories with role-based ACLs |
| Evaluation gate | Ad hoc visual inspection | 50-question gold-standard test suite | Automated continuous scoring and regression tests |
| Latency budget | Unbounded | <2.5 seconds per query | <500 ms interactive, queue-based batch |
| Fallback mechanism | Manual retry by engineer | Domain user manual fallback | Automated schema enforcement and rule-based fallback |
How to scale generative AI across business units
Once a single pilot demonstrates measurable success, the enterprise faces the challenge of scaling without multiplying technical debt. Allowing every department to invent its own AI stack creates fragmented tooling, duplicated vendor contracts, conflicting governance rules, and divergent security policies.
Establishing shared platform infrastructure
Scaling across multiple business units requires establishing a centralized platform infrastructure managed by an internal AI enablement team. This internal platform acts as a shared broker between business unit applications and underlying foundation models.
The shared platform provides standardized API gateways, centralized rate limiting, unified vector database instances, prompt registries, and automated auditing services. Individual business units define their domain logic. Meanwhile, the platform team ensures infrastructure economics, security guardrails, and compliance logging remain consistent across the enterprise.
Sequencing deployment across business units
Rollouts should follow a deliberate sequencing strategy based on organizational readiness and task risk. High-readiness, low-risk functions (such as internal employee knowledge bases or developer coding assistants) provide initial wins that build organizational confidence.
Organizations scaling across multiple departments benefit from an ai adoption framework, which establishes structured operational phases to maintain alignment between business priorities and technical capabilities. Once internal operational patterns stabilize, the enterprise can safely tackle higher-stakes external workflows, such as customer-facing conversational agents or semi-automated contract analysis.
Enforcing consistent governance and operational standards
As adoption broadens, maintaining standard compliance controls becomes vital. A centralized governance board should enforce standardized model cards, system risk assessments, and vulnerability testing across all deploying teams.
Standardization also simplifies operational auditing. If regulatory authorities require an explanation for an AI-generated decision, the organization can inspect centralized logs. These logs record the exact prompt version, retrieved context chunks, model parameters, and human approval timestamps.
Measuring success: metrics, KPIs, and generative AI ROI
Executive sponsors require rigorous financial and operational justification to sustain multi-year AI programs. Evaluating success demands a balanced framework connecting system-level technical telemetry to top-line and bottom-line business metrics.
Establishing a pre-implementation baseline
Before releasing an AI application to users, teams must establish a verified baseline of the existing workflow. If a legal team spends 4.5 hours reviewing a standard vendor contract with an average error rate of 3.2%, those figures become the baseline against which AI assistance is judged.
Without an empirical baseline, calculating productivity gains is impossible. Surveys asking employees whether an AI tool makes them feel faster introduce subjective bias. Therefore, objective measurement requires comparing actual hours logged, task completion rates, and defect counts before and after deployment.
Tracking operational metrics versus business outcomes
Evaluation metrics must distinguish between internal system performance and external business outcomes. Operational telemetry tracks technical health: context cache hit rates (e.g. maintaining >75% cache efficiency), median token latency (such as 350 ms time-to-first-token), request throughput, and retrieval precision.
Rigorous measurement requires separating model-level capability from application-level performance, applying the principles of AI model evaluation to quantify accuracy on standardized domain benchmarks before assessing business outcomes. Business metrics measure the operational impact: total cycle time reduction, cost per processed transaction, case escalation percentage, and customer satisfaction scores.
In specialized domains, general language benchmarks fail to capture nuanced reasoning errors. For instance, evaluation runs on Groundtruth, Eigenform’s open source dynamic benchmark, show that model accuracy varies substantially across document sets, demonstrating why domain-specific validation sets are required to verify production readiness.
Accounting for total cost of ownership
Proving positive generative AI ROI requires tracking the complete cost structure of the deployment. Foundation model API token charges are rarely the largest part of it: integration, evaluation, governance and ongoing maintenance add up to more than the per-token price suggests.
A comprehensive total cost of ownership (TCO) model incorporates vector storage costs, compute instances for embedding generation, data pipeline orchestration, security logging infrastructure, and maintenance engineering. Subtracting these comprehensive infrastructure costs from the verified financial value of saved labor or accelerated throughput yields a defensible generative AI ROI calculation that satisfies finance committees.
Published API list pricing quantifies how much model routing can save. As of October 2026, Anthropic’s published API pricing lists its small model at $0.10 per million input tokens and $0.50 per million output tokens for standard-length prompts, while its frontier model sits at $4 and $20 for the same units. That is a spread of roughly 40 times, so routing routine tasks to the smaller model removes close to 97% of the per-call cost.
Common challenges of implementing generative AI
Even with sound strategy and architectural planning, enterprises encounter recurring operational friction once systems run at steady-state production volume.
Managing inference economics at scale
As usage grows from hundreds of pilot interactions to millions of monthly production queries, unconstrained API consumption can cause severe budget overruns. Passing 12,000 tokens of retrieved context into a flagship commercial model for every query quickly becomes economically unsustainable.
Uncontrolled operational expenses and unpredictability are common generative ai challenges, requiring proactive rate limiting, dynamic model routing, and strict context window budgets to prevent cost overruns. High-performing engineering teams implement multi-tier routing: simple classification tasks are directed to cost-efficient smaller models at a small fraction of the per-call cost, reserving frontier models for multi-step logical reasoning.
Bridging organizational and technical skills gaps
Enterprise IT departments frequently face a talent shortage in specialized AI engineering disciplines. Foundation model integration requires expertise in probabilistic system design, embedding search, prompt evaluation, and context management.
Bridging this gap requires structured upskilling programs. Traditional software architects should pair with machine learning specialists. Concurrently, business users require training on prompt construction, critical review of AI-generated content, and standard exception handling procedures to avoid uncritical reliance on model suggestions.
Sustaining production reliability past the pilot
A model that performs reliably in March may degrade by October. Production degradation arises from multiple sources: foundation model providers silently updating proprietary model weights, internal corporate document repositories changing schema formats, or user query distributions shifting over time.
Maintaining production reliability demands continuous monitoring and automated regression testing. Automated synthetic probes running against production endpoints daily detect subtle behavioral shifts before they impact end users. When performance drops below pre-defined thresholds, traffic can automatically fail over to validated fallback models or route directly to human operators.
Generative AI use cases in business
Enterprise generative AI deployment generates the highest return when applied to complex information synthesis and document processing across core functional areas.
Customer operations and automated support
Customer support departments deploy generative models to augment human representatives and resolve routine inquiries autonomously. In a typical implementation, an incoming ticket triggers a retrieval step across policy manuals and product documentation, drafting a context-aware response for human agent review.
This hybrid approach cuts median handle time substantially while keeping humans accountable at the right checkpoints. Agents review, edit, and approve the generated draft, training the system on edge cases while ensuring erroneous statements never reach customers.
Enterprise knowledge discovery and synthesis
Large enterprises lose thousands of productive hours each year because employees cannot locate information buried across fragmented SharePoint sites, Confluence wikis, and document archives. Generative retrieval layers index these repositories, providing conversational search that synthesizes verified answers accompanied by precise citations to source files.
Synthesizing enterprise knowledge across disparate document sets is one of the most widely adopted llm use cases, turning passive institutional archives into interactive retrieval engines. Grounding answers in verified corporate documents keeps hallucination risk low while accelerating internal research.
Engineering workflows and code generation
Software engineering teams integrate generative tools into continuous integration pipelines and developer environments. Models assist developers by generating unit test suites, converting legacy codebases into modern languages, writing API documentation, and identifying potential security vulnerabilities during pull request reviews.
Because generated code undergoes automated compilation, unit testing, and human code review before merging, software development represents a high-impact use case with inherent verification safeguards that minimize operational risk.
Document intelligence and structured data extraction
Organizations handling heavy administrative volume (such as insurance carriers, banks, and supply chain logistics providers) deploy generative AI to transform unstructured documents into validated database entries. Models ingest complex PDFs, extract relevant entities (such as invoice numbers, shipping dates, and contractual liabilities), and map them directly into relational database tables.
Replacing manual data entry with automated extraction reduces processing cycle times from days to minutes while standardizing data quality across enterprise systems.
FAQs
What does generative AI implementation involve?
Generative AI implementation is the systematic process of embedding foundation models into enterprise workflows. It involves use case selection, data readiness auditing, legacy system integration, evaluation pipeline design, user training, and continuous governance. Rather than deploying standalone chat tools, successful implementations connect models directly to operational software and business data to automate and augment specific knowledge tasks.
Why is generative AI implementation harder at enterprise scale?
Enterprise implementation introduces strict governance, access control, and legacy integration requirements that single-team pilots bypass. While a pilot operates on small, static data with high human oversight, enterprise deployments must enforce complex data permissions across business units, integrate with fragile legacy APIs, maintain low latency at scale, and guarantee rigorous compliance, security, and auditability.
How do you implement generative AI in a business?
Businesses implement generative AI through a phased engineering strategy. Begin by identifying a high-frequency, narrow use case with accessible data. Audit infrastructure readiness, design automated evaluation rubrics, and launch a bounded pilot embedded in existing user workflows. Measure outcomes against pre-implementation baselines, refine prompts and retrieval architectures, and establish shared infrastructure before expanding to additional departments.
How do you scale generative AI across an organization?
Scaling generative AI requires building centralized, reusable platform infrastructure rather than duplicating one-off solutions in individual teams. Organizations establish shared API gateways, unified vector stores, standardized evaluation frameworks, and common security guardrails. Sequencing rollouts across departments based on data readiness and process risk ensures consistent quality and governance as adoption broadens across the enterprise.
How do you measure the ROI of generative AI?
Measuring generative AI ROI requires comparing post-deployment business outcomes against a documented pre-implementation baseline. Calculate total productivity gains, error reductions, or throughput improvements, and balance those savings against total cost of ownership. Total costs include model API fees, vector infrastructure, engineering time, pipeline maintenance, and human oversight to determine true net financial return.