TL;DR
- Ground truth is the set of correct answers used to test an AI, like the answer key a teacher uses to mark an exam. If the answer key has a mistake, the AI gets marked wrong even when its answer is right.
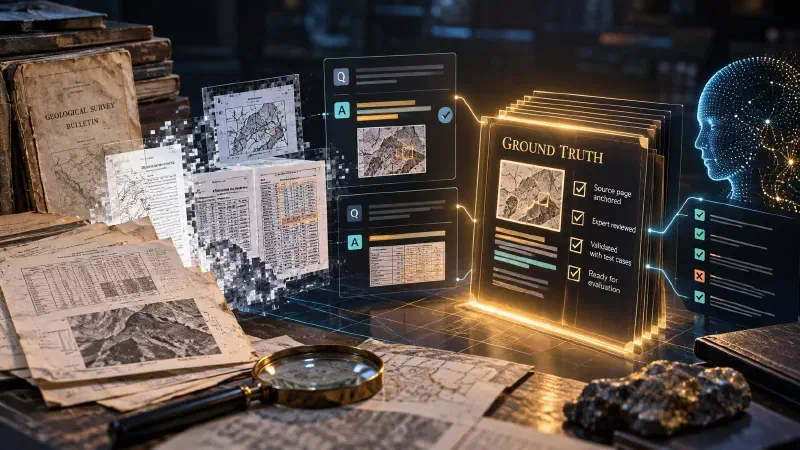
- It is built in four steps: collect the documents, turn them into text, write the correct answers, and test the grading. Most mistakes creep in early and only show up at the end.
- Our examples come from Groundtruth, Eigenform’s open-source benchmark that tests AI models on real geology reports: 150 questions, eight models.
Key Takeaways
- A bad answer key ruins every score. A wrong reference answer marks a correct model wrong, every time.
- Turning documents into text quietly adds mistakes. In one 1920s report we used, 18% of the pages were too damaged by scanning errors to rely on.
- Test the grading, don’t just re-read it. Reading the grading rules found 2 mistakes; practice answers with known scores found 15 more.
- Every correct answer should point to its source page. A script checks each link to the source; one build needed 41 fixes.
Ground truth data for AI is the reference that decides whether an answer counts as right. Every accuracy figure, leaderboard position and “the new model is better” claim is a comparison against it, so its errors pass straight into every result built on it.
We learned this building Groundtruth, Eigenform’s benchmark that asks AI models geological questions about real exploration reports. The hard part was never the scoring code. It was making sure the reference answers, and the evidence behind them, were actually true to the documents.
What Is Ground Truth Data for AI?
Ground truth data is the set of verified, correct answers that an AI model’s outputs are compared against during training or evaluation. It can be class labels, bounding boxes, transcriptions or reference answers with cited evidence. What is ground truth in machine learning, in one line? The best available record of what is actually true.
The term comes from remote sensing, where “ground truth” meant observations made on the ground to check what a satellite image seemed to show. For ground truth in AI, the meaning carried over: it is the check, not the thing being checked. While people sometimes search for the single word, as in “groundtruth machine learning”, generic machine learning uses two words; our open-source benchmark, Groundtruth, uses the single word specifically as its product name. A reference dataset is also only as good as the process that produced it. In Groundtruth, each reference answer is tied to an exact passage in the source reports, and a geology expert vetted every question and rubric before any model was scored.
Why Is Ground Truth Data Important for AI Models?
Understanding why ground truth is important comes down to a simple reality: ground truth decides what counts as right, so it caps the trustworthiness of every evaluation score. Every leaderboard rank, benchmark metric and claim that a new model outperforms an older one inherits the accuracy of the reference dataset.
When reference answers contain errors, faulty benchmarks mark correct models wrong and reward broken logic. This directly distorts model selection. In our evaluation across eight models and 1,200 graded answers, only 2 of 7 gaps between neighbouring models were statistically significant; noisy references risk masking these narrow margins entirely. Similarly, in ground truth for generative AI evaluation, reading grading rules found only 2 defects while testing with known-score answers exposed 15 more. Without verified ground truth, engineering teams risk selecting inferior models based on phantom score advantages.
How Is Ground Truth Data for AI Built?
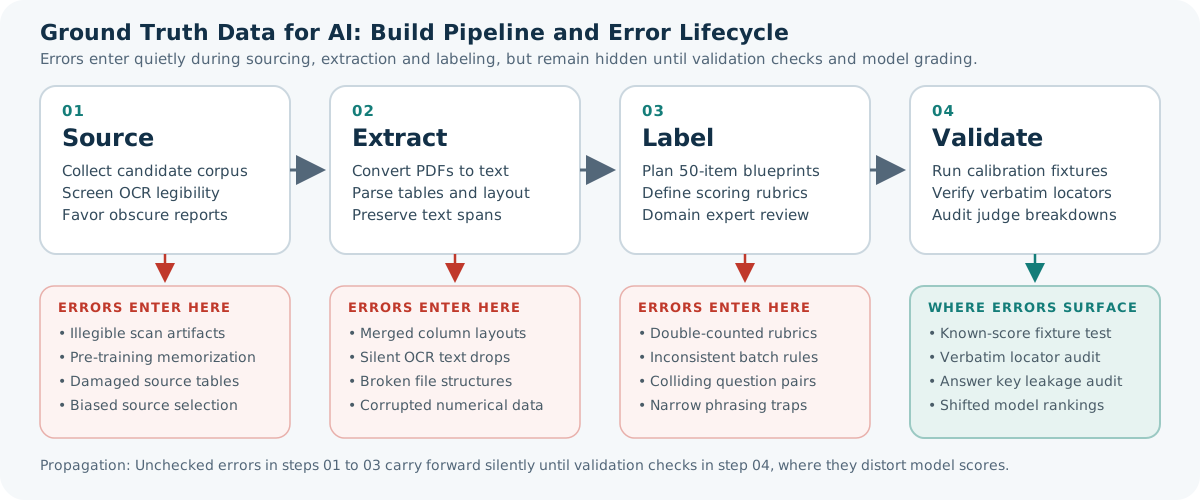
Building a ground truth dataset follows four sequential stages: sourcing candidate documents, extracting clean text, labeling reference answers with rubrics, and validating the evaluation pipeline.
| Step | What it decides | Typical failure |
|---|---|---|
| Sourcing | Which documents or examples the reference can draw on | Material the model already memorised; illegible sources |
| Extraction | What text or data the reference is written against | OCR damage, merged columns, broken files |
| Labeling | What the correct answer is and how it is graded | Inconsistent judgment calls, rewarding the same point twice |
| Validation | Whether the reference and its grading behave as intended | Checks that only re-read, instead of testing |
Sourcing
Sourcing decides what can be asked. For our USGS document set we downloaded 190 candidate reports, just over eight million words, and ranked them by measured legibility before choosing any. We also favour obscure sources on purpose. A benchmark built from material a model saw in training measures recall, not reasoning.
Extraction
Extraction decides what the reference is written against, because both the rubric’s evidence and the candidate’s answers come from extracted text, not from the original PDF. It is where the quietest errors enter, from extraction traps that break evidence anchors to corrupted text layers in a ground truth dataset built from scanned documents. Two-column pages merge into nonsense under one extraction mode and tables collapse under the other. OCR damage sits inside the text layer, where re-reading cannot see it. Preparing one corpus even broke 207 JSON files across 46 reports without any OCR involved.
Labeling
Labeling decides the correct answer and how partial answers earn credit. In a benchmark of open questions, a label is a reference answer plus a rubric: required points, a hard gate that zeroes an answer missing the core fact, and a list of claims that must not be credited. We derive grading criteria from the underlying geological principle, not from the wording of the source sentence, so that a correct answer shows reasoning rather than paraphrase.
Consistency is the other half of labeling. When people reviewed questions batch by batch, inconsistent judgment calls between batches produced incompatible rubric structures. We now generate all 50 questions of a set from one blueprint with one approval step before any drafting. Planning up front matters: on one build, 9 of the last 22 questions collided with earlier ones before we did.
Validation
Validation checks that the reference and its grading behave as intended, and it has to test rather than re-read. We run calibration fixtures with known expected scores through the production judge before any real model is graded. Across 200 such answers on two projects, 14 and 16 scored higher than they should have, because the rubric rewarded the same idea twice.
Scripts check the rest. Every evidence locator must be a verbatim substring of the extracted text, and the judge must return a structured breakdown that software can verify. A breakdown that fails the check is rejected and retried up to three times; after that, the question stays unscored instead of getting an invented number. The full authoring and validation procedure is recorded in AUTHORING.md in the Groundtruth repository.
What Are the Biggest Challenges in Establishing Ground Truth Data?
An error in ground truth data for AI does not stay in one place. It passes into every score computed against it, for every model, and it looks exactly like a model failure.
| Error | How it propagates | How we catch it |
|---|---|---|
| Damaged source text | A correct answer disagrees with a corrupted reference value | Page-level damage scores; quarantined pages; a second occurrence required for load-bearing figures |
| Wrong evidence anchor | Graders credit or penalise against the wrong passage | Script-verified verbatim anchors, span and retrievability audits |
| Double-counted rubric points | Weak answers score too high; rankings shift | Fixture answers with known scores run through the production judge |
| Leaked reference | Agents read the answer instead of reasoning | Reference files moved outside the candidate’s reach; transcript audits |
| Too few items | Noise looks like a real difference between models | Confidence intervals and a minimum detectable gap |
Two of these deserve a closer look.
Leakage is the error people least expect. A candidate agent with file access can open anything the benchmark’s account can read, running straight into answer key leakage when ours accessed rubrics directly. Hiding only the authoring skill still leaked grading text on 8 of 50 questions.
Sample size is the error that looks like precision. With 50 questions per set, the smallest gap we can detect between two models is 0.27 to 0.45 points. Across eight models and 1,200 graded answers, only 2 of 7 gaps between neighbouring models were statistically significant. Good ground truth with too few items still cannot separate close models.
How Does Ground Truth Differ in Machine Learning, Deep Learning and Generative AI?
The idea is the same everywhere: a trusted reference. What changes is the kind of reference, how much of it is needed, and how it is checked.
Ground Truth in Machine Learning: Labels for Training and Testing
In classic supervised learning, ground truth machine learning data usually means labeled examples: a class for each row, a value to predict, a category for each document. The same kind of labels serves two roles. Training labels teach the model; test labels measure it. Keeping the two separate is what makes the measurement honest, and noisy training labels are often tolerated where noisy test labels are not.
Ground Truth in Deep Learning: Scale, Dense Labels and Noise
Ground truth deep learning datasets are usually far larger and denser: a mask for every pixel in segmentation, a box for every object in detection, a transcript for every second of audio. At that scale, labels come from many annotators or from models, so in ground truth deep learning tasks, agreement between annotators and systematic review of samples replace checking every item by hand.
Ground Truth for Generative AI Evaluation
Language models add a third context. There is rarely one correct wording, so machine learning ground truth becomes a reference answer plus a rubric, and the grader is often another model. That is where source anchoring and judge validation, described above, carry most of the weight. Our benchmark takes its name from that idea: Groundtruth is ground truth for reasoning over documents, where every correct answer has to trace back to the page that supports it.
| Context | Typical ground truth | Main risk | Main check |
|---|---|---|---|
| Classic machine learning | Class labels, target values | Label noise, leakage between train and test | Held-out test set, spot audits |
| Deep learning | Masks, boxes, transcripts at scale | Inconsistent annotators | Inter-annotator agreement, sampled review |
| Generative AI evaluation | Reference answers, rubrics, evidence anchors | Rubric defects, grader bias, corrupted sources | Fixture answers, verified anchors, validated judges |
What Are the Best Practices for Ground Truth Data in Machine Learning?
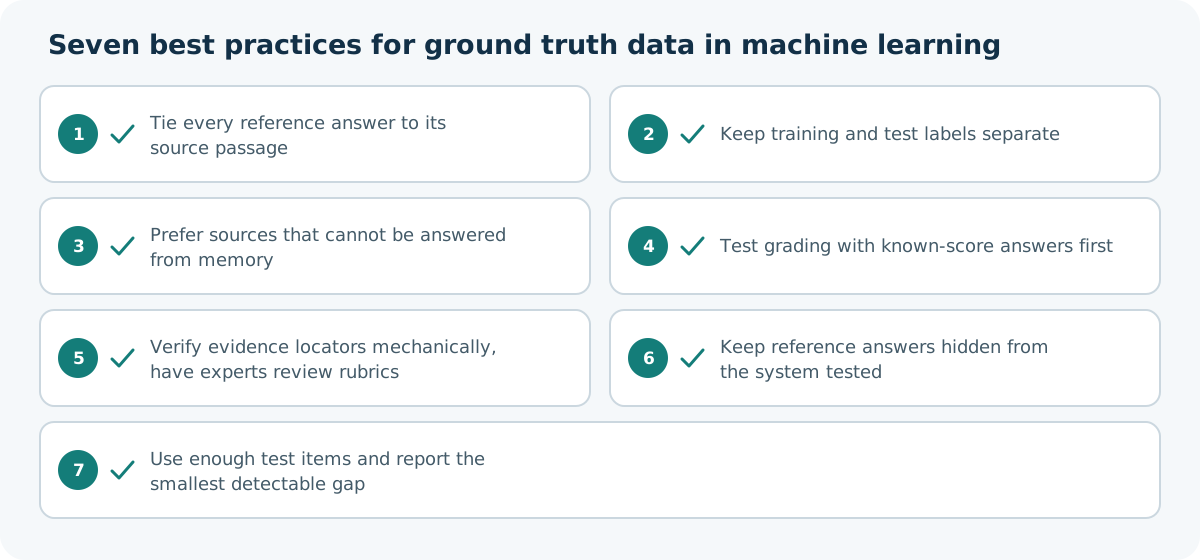
Rigorous machine learning evaluation requires treating the reference dataset as a verified measurement system rather than an informal collection of unchecked text. Every reliable ground truth benchmark depends on disciplined data isolation, mechanical verification of source anchors, and statistical validation of score significance. When building and maintaining reference datasets, rigorous teams apply seven core practices:
- Tie every reference answer to its exact source passage: verify text spans mechanically so graders assess candidates against verified source passages rather than hallucinations.
- Keep training and test labels separate: enforce strict data separation so evaluations measure true generalization rather than memorized ground truth labels.
- Prefer sources that cannot be answered from memory: select domain materials outside standard pre-training sets so benchmark tasks measure reasoning rather than mere web recall.
- Test grading with known-score answers before grading real output: run calibration fixtures through the production judge to expose double-counting defects before evaluating models.
- Verify evidence locators mechanically and have experts review rubrics: combine automated substring validation with domain specialist oversight to ensure rubrics reflect sound principles.
- Keep reference answers hidden from the system being tested: isolate answer keys and grading prompts from candidate agents to prevent subtle leakage.
- Use enough test items and report the smallest detectable gap: calculate confidence intervals so score differences reflect genuine capabilities rather than noise.
What Are the Limitations of Ground Truth Data?
Even well-built ground truth has limits. It describes one set of documents or examples, so a model that scores well on it has shown competence on that material, not in general. Across our three document sets the top tier on the Groundtruth leaderboard held, but the order inside the lower half changed from one set to the next.
A reference also ages. For historical sources we treat the document as the authority for what it claims, and questions test the reasoning as the report gives it rather than asking a model to correct a 1920s author.
How Do You Maintain a Ground Truth Benchmark?
Maintaining an evaluation benchmark requires continuous auditing because reference answers, source materials and models inevitably evolve over time. Static benchmarks degrade as documents age and models encounter contaminated evaluation sets:
- Handling source aging: Historical documents treat the original report as the authority for what it claims, testing reasoning against stated facts rather than modern revisions.
- Refreshing document sets: Periodically rotating candidate reports and re-running grading checks ensures models cannot overfit to familiar evaluation corpora. We developed this practice while implementing dynamic benchmarking across fresh industry sources.
- Re-checking locators and rubrics: Any update to OCR engines, text extraction tooling or authoring scripts requires re-verifying verbatim evidence anchors and rubrics against AUTHORING.md in the Groundtruth repository.
- Evaluating across multiple sets: Across our three document sets, top-tier models maintained their lead, but rankings inside the lower half shifted between corpora. Maintaining multiple parallel document sets prevents idiosyncratic source quirks from skewing long-term model comparisons.
Frequently Asked Questions
What does ground truth mean in AI?
Ground truth in AI refers to the verified correct answer that a model’s output is compared against. It can be a label, a bounding box, a transcription or a reference answer with cited evidence. The term comes from remote sensing, where observations on the ground were used to check what satellite images seemed to show.
How is ground truth data created?
Ground truth data for AI is created in four steps. Sourcing picks the material, extraction turns it into usable text or data, labeling defines the correct answers and how they are graded, and validation tests the result. Validation should run known test answers through the real grader rather than rely on another read-through.
Why does ground truth quality matter for evaluation?
Every evaluation score is a comparison against the ground truth, so its errors pass into every result. A wrong reference answer marks correct models wrong, and a rubric that rewards the same point twice lets weak answers score too high. Because evaluations depend on this reference, flawed reference data limits what any evaluation can show.
What is the difference between ground truth and labeled data?
When comparing ground truth vs labeled data, labeled data is any data with labels attached, including labels that are noisy, automatic or unchecked. Ground truth is labeled data that has been verified well enough to serve as the reference for training or measurement. All ground truth is labeled data, but only checked, trusted labels count as ground truth.
Why is ground truth data important?
Accurate ground truth is important because it defines the benchmark ceiling for evaluation trustworthiness. Model accuracy scores, rankings and comparison claims directly inherit the errors in reference answers. A flawed ground truth dataset marks capable models wrong, rewards flawed outputs, and distorts engineering decisions. Without rigorously verified references, teams cannot distinguish genuine capability improvements from evaluation noise.
What are the biggest challenges in establishing ground truth?
The biggest challenges in establishing ground truth are extraction errors, rubric double-counting, answer key leakage, and insufficient sample sizes. Document extraction frequently corrupts layout and table data without warning. Evaluator rubrics can inadvertently award points twice for identical concepts, while autonomous agents may access reference files during runs. Finally, small test sets produce statistical noise that obscures real differences between models.
What are the best practices for ground truth in ML?
Sound ground truth machine learning practices include tying every reference answer to a verbatim source locator, strictly isolating training labels from test sets, and selecting obscure sources that measure reasoning rather than recall. Teams should test rubrics with known-score calibration fixtures before grading real answers, hide answer keys from testing environments, and maintain sufficient sample sizes to detect meaningful score margins.
How do you maintain a ground truth benchmark over time?
Maintaining an evaluation benchmark over time involves treating historical documents as the authority for their era, rotating fresh document sets to prevent model overfitting, and re-checking evidence locators whenever extraction tools or scripts change. Because ranking orders in the lower half of leaderboards can shift across different document collections, benchmark maintainers should score models across multiple diverse document sets rather than relying on one.