TL;DR
- Construct: Ground every task in specific source material and test the scoring rubric against known answers before grading any model.
- Run: Hold the test harness fixed across models and require an accountable LLM judge with structured, validated outputs.
- Interpret: Read every result against statistical resolution rather than raw scores, drawing on lessons from Groundtruth, Eigenform’s open source dynamic benchmark.
Key Takeaways
- Benchmark construction choices are benchmark results. Question design and gating decide what the benchmark can even measure.
- Statistical resolution determines what gaps are detectable. On ours, the smallest detectable gap ranged from 0.27 to 0.45 points depending on the task set.
- Custom benchmarks need machine-gated authoring to stay consistent. Manual authoring drifts across waves.
- Comparing models requires holding the harness fixed. Otherwise the harness, not the model, explains the gap. We found this running eight models through one shared harness.
Search “how to benchmark AI models” and most guides stop at the same place. Pick some tasks, write a scoring rubric, run your model, read the score. That gets you a number. It does not tell you whether the number means anything when teams benchmark AI models for high-stakes workflows.
This is the framework we use for the Groundtruth benchmark, which we built and run for geological reasoning.
Results across eight models are published on the Groundtruth leaderboard. It is written to generalise past geology: the numbers below are ours, and the stages are the same regardless of domain.
What Does It Mean to Benchmark an AI Model?
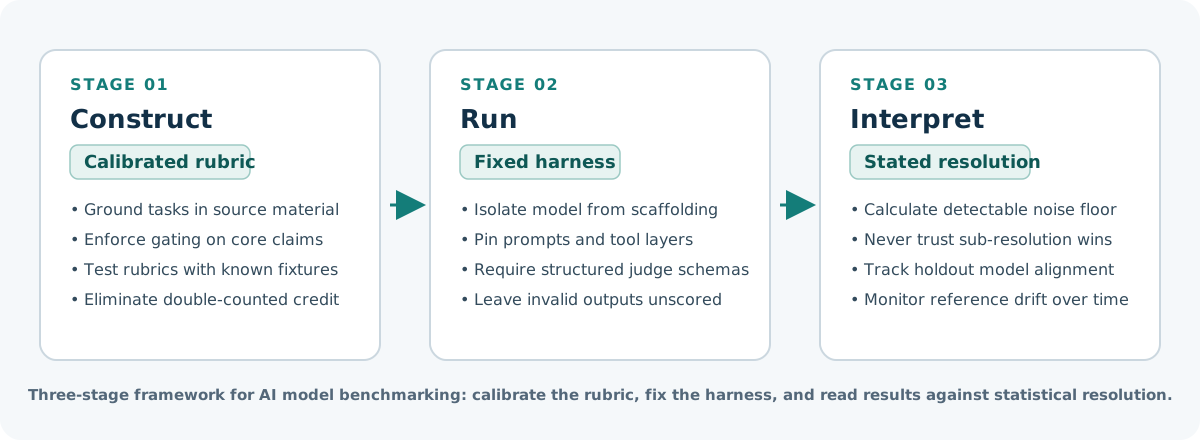
Benchmarking an AI model is the controlled measurement of a model against a fixed task set, rubric, and scoring method, so that differences between models can be trusted. Understanding how to benchmark AI models comes down to three separable stages: constructing grounded tasks, isolating the model during runs, and reading scores against statistical resolution.
The part most guides skip is the middle and the end. A rubric can look complete and still double-count credit or pass the wrong reasoning, and none of that shows up by reading the rubric. It shows up when you run known answers through it and see what comes back.
What Are the Main Types of AI Benchmarking?
In AI model benchmarking, five evaluation approaches differ by how tasks are sourced, whether scaffolding is included, and how responses are graded:
| Benchmark Type | What It Measures | Main Weakness |
|---|---|---|
| Static public benchmarks | General capability on standardized test sets | Prone to data contamination and domain mismatch |
| Custom domain benchmarks | Performance on proprietary tasks and documents | Requires domain authoring and rubric calibration |
| Dynamic benchmarks | Reasoning on regenerated or refreshed questions | Higher authoring and verification overhead |
| Agent and harness benchmarks | Model plus prompts, tools, and scaffolding | Confounds model quality with harness design |
| Human vs. LLM-as-a-judge | Open-ended quality via experts or automated rubrics | Human grading is slow; unvalidated judges drift |
Teams benchmarking an agent harness hold scaffolding fixed to isolate model weights.
To limit memorization, dynamic benchmarking refreshes questions from source material. The rest of this article focuses on building a custom LLM benchmark.
Are AI Benchmarks Accurate?
AI benchmarks are accurate when their tasks match the target workflow, their rubrics are calibrated, and their sample size supports the claimed score gap. Public leaderboard scores can overstate production performance when standardized tasks diverge from proprietary enterprise data.
Training data contamination also skews reported capability. Sainz et al. (2023) show that benchmark leakage into pre-training corpora inflates model scores on standard NLP evaluations and compromises comparisons against uncontaminated baselines.
Measuring that leakage is itself non-trivial: Singh et al. (2024) surveyed contamination across 13 benchmarks and found that n-gram overlap affects models unevenly across scales. In practice, a score is only as trustworthy as its rubric, judge, and sample size, which our framework addresses through calibration, accountable judging, and stated resolution.
Step 1: Constructing the Benchmark
Before writing a single question, decide what a good outcome looks like. Describe it in the words of someone who does the work, not as a generic accuracy target. Deciding how to benchmark AI models also settles whether you need a custom LLM benchmark at all. A public benchmark is enough when general capability is what you are measuring: a model’s coding ability, its factual recall, or its reasoning on textbook problems. It stops being enough once you need to know how a model performs on your own documents, your own edge cases, or a task shape no public benchmark tests.
A generic geology benchmark score told us nothing about whether a model could reason correctly over one company’s own exploration archive. That gap is why Groundtruth generates a fresh benchmark from a user’s own documents instead of reusing a fixed public one. The same logic is why hardware and inference speed get their own benchmarks, such as MLPerf, rather than a general leaderboard that blurs the thing you actually need to measure.
How Do You Design Tasks That Resist Memorization and Vague Answers?
A benchmark task is only useful if a model cannot score well by cheating past the actual question. The first shortcut is answering from memorised general knowledge instead of reasoning over the material in front of it. Obscure, source-specific material forces a model to read rather than recall.
The second shortcut is sounding right without committing to a claim. A fluent, well-hedged answer that never states the thing being asked for can still read as good to a lenient grader. Both get closed by grounding every task in specific source material and requiring one concrete claim per question. Our custom LLM benchmark pipeline shows the whole process. It includes the machine checks that catch a lopsided task set before a human ever reviews it.
What Makes a Benchmark Rubric Produce a Clean Signal?
Two people, or two runs of the same judge, should reach close to the same score from the same rubric and the same answer. The piece of rubric structure that does the most work here is a gate. One component tests the single claim the question exists to test, and missing it zeroes the answer regardless of the rest.
Without a gate, a long, confident answer that covers everything adjacent to the question collects partial credit everywhere. It lands at a respectable score while missing the actual point. Gated rubrics ensure that AI model benchmarking measures domain reasoning rather than fluent writing.
Why Should You Test the Rubric Before Testing Any Model?
Write fabricated answers for each question yourself, one per point on the scale, and attach the score you expect each to get. Then run them through your actual judge before it grades a real model. We call these calibration fixtures.
Running a full set turned up a defect pattern we would not have found by rereading the rubrics. Across two 50-question benchmarks, 14 and 16 fixtures out of 200 scored higher than their author predicted. The cause was the same each time: a component awarded credit for something the gate already required, so every answer that passed the gate collected that component automatically.
On one of those benchmarks, the author’s own careful review found 2 defects, versus 15 caught by the mechanical fixture run.
Step 2: Running the Benchmark
Comparing models fairly when you benchmark AI models requires holding the evaluation harness fixed so that score differences come from the model alone. Once you run agents rather than single model calls, an AI model benchmarking setup has to account for more than the model. The tools available, the system prompt, and the retrieval layer can change the score as much as the model itself. That is the territory of AI agent evaluation.
How Do You Compare AI Models Without the Harness Getting in the Way?
If two rows in a comparison differ in both model and harness, the gap between them has two possible causes and no way to separate them afterward. Hold the harness fixed and vary only the model, or pin the model and vary only the harness. That is the only way to know which one produced a given result. We built a second leaderboard track specifically to isolate this across eight models.
How Do You Pick an Accountable LLM Judge?
If a language model assigns your scores, it is part of your measurement instrument and needs the same scrutiny as the agent being tested. In any LLM-as-a-judge setup, require the judge to return a structured, machine-checkable result rather than free text, and validate it against the rubric before accepting it.
Our own validator checks eleven rules before it accepts a score. When the judge cannot produce a valid result after a few attempts, leave the question unscored rather than guessing.
What AI Benchmarking Metrics Should You Track?
Core evaluation metrics pair capability scores with statistical error bounds and operational checks. In our LLM evaluation framework, task score and statistical resolution are the primary metrics, while variance, judge agreement, and operational overhead are supporting metrics:
| Metric | What It Tells You | When to Use It |
|---|---|---|
| Task score / accuracy | Rubric score, gated score, or pass rate | Primary metric for comparing capability on a task set |
| Statistical resolution | Smallest gap distinguishable from noise (0.27 to 0.45 points on our 50-question sets) | Primary metric for deciding if a score gap is real |
| Run and judge variance | Stability across repeated runs and judge prompts | Supporting check to verify rubric consistency |
| Judge agreement | Consistency with human grading (such as Cohen’s kappa) | Supporting check when calibrating an automated judge |
| Operational metrics | Latency, cost per question, and unscored or refusal rate | Supporting check for deployment and validator health |
A raw accuracy figure is incomplete without the minimum detectable gap of the question set. Disciplined AI model benchmarking pairs every task score with its resolution floor and tracks unscored rates so invalid judge outputs never distort rankings.
Step 3: Interpreting Results
A benchmark score is not exact. To evaluate AI model accuracy against benchmarks and baselines, read every result against a resolution. That is the smallest gap the sample size and grading noise can distinguish from chance, and it depends on how many questions back the score. Measuring statistical significance in AI benchmarking keeps teams from mistaking random run variance for a real model improvement.
On our three task sets, that resolution ranged from 0.27 points on the easiest-to-resolve set up to 0.45 on the hardest, using the same benchmark and the same judge. A 0.3-point improvement in model performance is a real finding on one and pure noise on the other. Model rankings, like our comparison of six models on real exploration archives, are exactly the kind of result this applies to.
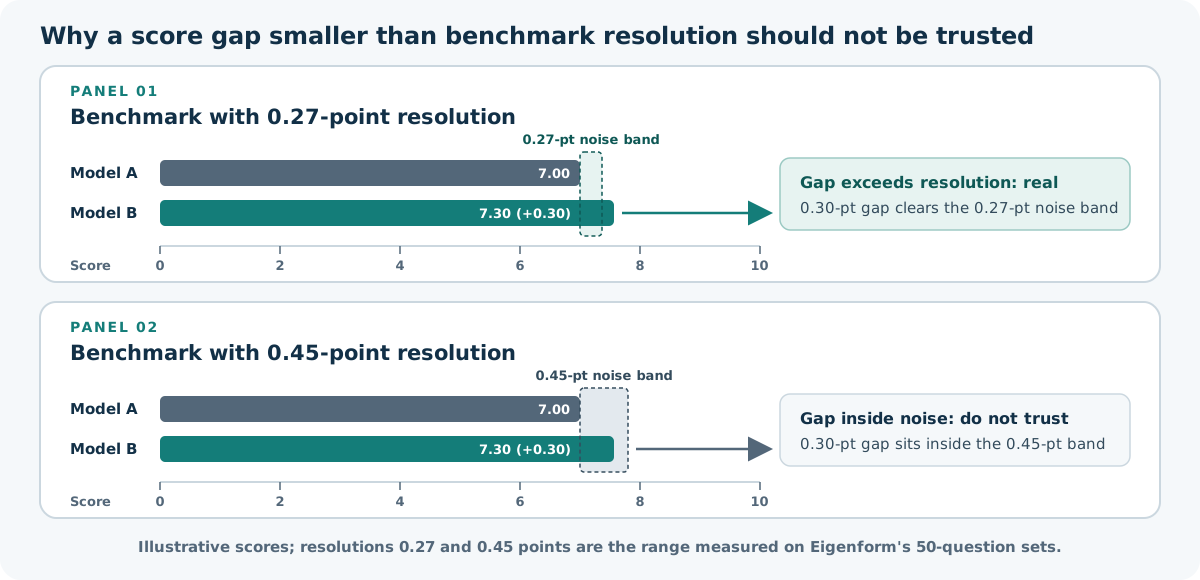
Publish that number alongside your results, or calculate it before trusting anyone else’s. In disciplined AI model benchmarking, a score is incomplete without its error margin. The other half of reliability is maintenance. A benchmark whose rubrics were shaped by watching a handful of models answer them can end up fitted to those models specifically. Hold some models out of that process, then check they land where their general capability predicts. That is direct evidence the rubric grades unfamiliar models the same way as familiar ones. Re-running a stable reference system periodically catches the same problem from the other direction: it tells you whether a score moved because a model changed or because the benchmark quietly drifted.
What AI Model Evaluation Tools and Platforms Can You Use?
Modern evaluation platforms span open-source benchmark harnesses, application-level testing libraries, and custom domain generators. Teams running broad LLM evaluation typically pair standardized harnesses with workflow-specific graders:
| Tool | Maintainer | Type | Best For |
|---|---|---|---|
| lm-evaluation-harness | EleutherAI | Open-source harness | Reproducible few-shot academic benchmark runs |
| Stanford HELM | Stanford CRFM | Research framework | Multi-metric foundation model comparisons (maintenance mode since June 2026) |
| OpenAI Evals | OpenAI | Open-source framework | Custom evaluation suites and model-graded checks |
| Inspect | Meridian Research Labs (UK AISI project) | Evaluation framework | Safety, agent, and tool-use capability evaluations |
| promptfoo | Promptfoo | Application-level CLI | Local prompt regression testing and red teaming |
| DeepEval | Confident AI | Application-level framework | Pytest-style LLM unit tests and agent trajectory checks |
| Ragas | Vibrant Labs | Application-level toolkit | Evaluating retrieval quality and faithfulness in RAG apps |
| LangSmith | LangChain | Observability platform | Tracing agent runs and dataset-driven evaluations |
| Groundtruth repository | Eigenform | Custom benchmark system | Source-grounded dynamic benchmarks from domain archives |
Choose a public harness for broad comparability across models, or build a custom LLM benchmark with a system like Groundtruth when testing fit for your own task.
What Are the Most Common Mistakes in AI Model Benchmarking?
When teams benchmark AI models, five recurring mistakes undermine their results:
- Skipping rubric calibration. Reading a rubric and trusting it is not the same as running fabricated answers through it. The gap between the two is where most scoring defects hide.
- Comparing models without holding the harness fixed. A score difference with two things varying at once cannot be attributed to either one.
- Trusting a gap smaller than the benchmark’s own resolution. A 0.3-point win means nothing if your sample size cannot reliably detect gaps that small.
- Using an LLM judge with no output contract. An unstructured judge response that cannot be validated is a guess wearing a number.
- Never re-running a stable reference. Without one, a score change cannot be told apart from the benchmark itself drifting.
How to Benchmark AI Models: Best Practices for Comprehensive Model Benchmarking
Reliable evaluation depends on controlling task construction, execution, and interpretation as one connected workflow. Before making production model decisions, apply this six-point checklist:
- Define what you are measuring first. Specify a strong outcome in practitioner terms before writing questions.
- Ground every question in a source and one concrete claim. Source-specific tasks prevent models from passing on memorised recall or vague hedging.
- Calibrate the rubric before running any model. Run fabricated answers as calibration fixtures through the judge to catch double-counted credit.
- Hold the harness fixed and vary one thing at a time. Pin prompts, tools, and retrieval when comparing models.
- Validate judge output and leave failures unscored. Enforce a machine-checked schema so malformed responses never enter the score.
- Report results with resolution and re-run a stable reference. Publish the smallest detectable gap and periodically re-test a reference system to catch drift.
Frequently Asked Questions
How do you benchmark an AI model?
To decide how to benchmark AI models reliably, build a task set grounded in specific source material with a scoring rubric that includes a pass-fail gate. Test that rubric against fabricated calibration fixtures before grading a real model. Run each model with the test harness held fixed, validate all judge outputs mechanically, and read every score difference against the benchmark’s statistical resolution.
What makes a benchmark reliable?
A reliable benchmark combines source-grounded tasks that resist memorisation and vague hedging with a rubric calibrated against known-score fixtures before any model is tested. It also requires an accountable judge constrained by a machine-checked output schema, a fixed execution harness across compared models, and a stated statistical resolution so noise is not mistaken for a real capability gap.
How is a custom LLM benchmark built?
You build a domain-specific evaluation suite by generating questions and gated rubrics directly from your own source documents rather than reusing a public test set. Automated checks verify structural rules, an even difficulty spread, and source evidence grounding before a human reviewer approves the blueprint and runs calibration fixtures through the judge to catch double-counted credit.
What is statistical significance in AI benchmarking?
Statistical significance in AI benchmarking is whether an observed score gap is larger than what sample size and grading noise could produce by chance. On our 50-question sets, that minimum detectable gap ranged from 0.27 to 0.45 points depending on the task set, meaning any smaller score difference between models is indistinguishable from random variation.
Are AI benchmarks accurate in practice?
Benchmark scores are accurate only when their tasks reflect your target use case and their scoring methodology is controlled. Public leaderboard scores can overstate production capability when evaluation items leak into training data, as documented by Sainz et al. (2023) and Singh et al. (2024), or when tasks miss domain workflows. Reliable accuracy requires calibrated rubrics, an accountable judge, and stated statistical resolution.
What are the types of AI benchmarking?
Evaluation approaches include static public benchmarks for broad model comparisons, custom domain benchmarks built around private workflows, and dynamic benchmarks that regenerate tasks to limit contamination. Teams also run agent and harness benchmarks that evaluate models together with their tools and prompts, and choose between human expert grading and automated LLM-as-a-judge scoring.
What metrics are used to benchmark AI models?
Key AI benchmarking metrics start with task score (rubric score, gated score, or pass rate) paired with statistical resolution, which defines the smallest gap distinguishable from noise. Supporting metrics include run-to-run and cross-judge variance, agreement between automated judges and human reviewers, and operational measures such as latency, cost per question, and the unscored or refusal rate.
What tools can you use to evaluate and benchmark LLMs?
Common AI model evaluation tools include open-source harnesses such as EleutherAI’s lm-evaluation-harness, Stanford HELM, OpenAI Evals, and UK AISI Inspect for standardized model comparisons. For application-level regression testing and tracing, teams use promptfoo, DeepEval, Ragas, and LangSmith. When evaluating domain-specific reasoning over proprietary documents, systems like Eigenform’s Groundtruth generate source-grounded custom benchmarks.