TL;DR
- Testing generative AI means covering failure modes traditional software testing wasn’t built for (hallucinated output, non-deterministic responses, and unsafe or off-brand content) on top of the usual functional checks.
- Reliable testing combines automated evaluation, adversarial probing and human review, because no single method catches every risk on its own.
Key Takeaways
- Generative AI introduces risks traditional software testing doesn’t cover. Hallucination, inconsistency and unsafe output need testing approaches beyond standard functional QA.
- Non-determinism changes what “passing a test” means. The same input can produce different outputs across runs, so testing has to account for variance, not just a single pass/fail check.
- No single testing method catches every failure mode. Automated evaluation, adversarial testing and human review each surface different classes of problems.
- Testing has to continue past launch, not stop at release. Generative AI applications can degrade or drift in behavior as prompts, models or usage patterns change.
- Tooling helps scale testing but doesn’t replace judgment. Automated evaluation tools speed up coverage, but interpreting edge cases still needs a human in the loop.
How to test generative AI applications is a different problem from testing ordinary software, which gives the same output for the same input. It can answer differently on every run, state a falsehood fluently, or be talked out of its instructions.
Groundtruth, Eigenform’s open source dynamic benchmark, grades AI models’ open-ended answers (written in their own words, like an essay rather than multiple choice) with another model as the judge, and most evidence below comes from what it caught.
What Are the Main Generative AI Risks in Applications?
Testing generative AI applications means checking the model’s output, not only the code around it: whether it is accurate, consistent across runs, safe and on-brand, and whether it resists manipulation. Functional testing, which checks that each feature does what its specification says, was not built for any of these.
The NIST Generative AI Profile, a 2024 guide from NIST, the US government’s standards agency, lists 12 risks that generative AI creates or worsens. Four risks apply to almost any generative AI application.
Hallucination and factual inaccuracy
A hallucination is fluent, confident output that is false: an invented citation or a wrong figure. NIST calls it confabulation.
We tested our map-processing MCP server (a program that gives AI agents tools to call) with real agents. Some apps passed the agent only the text of each result. Without the structured data, some agents invented plausible legend labels rather than report the labels as missing. Catching hallucination therefore needs a verified reference for each claim.
Non-determinism and output variance
A generative model samples its output one token (a word or word fragment) at a time, so one prompt can produce different outputs. Lowering the temperature setting, which controls that randomness, reduces variation without removing it. The judge we use is not perfectly deterministic even at temperature 0.
So one passing run proves little: run each test several times and report the spread. Score gaps also depend on which questions were sampled: on our 50-question sets, benchmark statistical significance tests put the smallest detectable gap at 0.27 to 0.45 points out of 10.
Unsafe, biased or off-brand content
Output can be harmful, unfair to a group, or wrong for the business, such as a promise the company cannot keep. None is a code bug, so the test needs a written policy defining the failure. Bias tests send one request with different names or languages and compare outputs.
Prompt injection and adversarial input
Prompt injection is input that turns a model against its instructions. OWASP’s Top 10 for LLM applications ranks it first. It also separates direct injection, typed by a user, from indirect injection, hidden in a page, file or tool result the model reads.
Indirect injection is the case test plans miss. Our open-source MCP server passes text from public databases, such as fault names, to the model. Its agent guide, part of our MCP server security design, therefore tells agents never to follow instructions found in that data.
How to Test Generative AI?
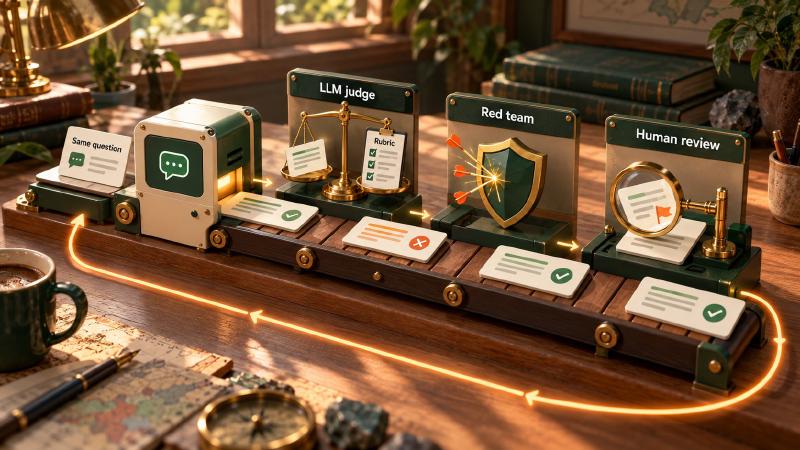
The short answer to how to test generative AI: define what a good output is for your task, then check it three ways: automated evaluation against a rubric, adversarial or red-team testing, and human review for what automation misses. Run the tests on every change, not once before launch.
In practice:
- Define the task and the cost of each failure. A wrong figure in a financial summary needs a stricter threshold than a clumsy phrase.
- Build a test set from your own data. A benchmark built from your own documents asks the questions your application will face.
- Write a rubric stating what a correct answer must contain and which plausible claims earn nothing.
- Match a grader to each check: code for format, an LLM judge for open answers, people for samples.
- Test the grader on answers with known scores before it grades anything real.
- Re-run after every change and report the spread across runs.
Expect imperfect output and catch it. A prompt run 100 times will not give 100 perfect outputs, so an error-correcting AI harness passes each agent’s work to a second agent with a checklist of common mistakes.
Different Generative AI Testing Methods
Each method catches a different class of failure and has its own blind spot.
| Method | Catches | Misses |
|---|---|---|
| Rule-based checks | Broken formats, banned terms, wrong exact answers | Anything needing judgment |
| LLM-as-a-judge | Wrong or incomplete open answers, at scale | Its own biases |
| Red-team testing | Jailbreaks, prompt injection, unsafe output | Everyday quality problems |
| Human review | Tone, nuance, subtle errors, harness faults | Scale and consistency |
| Regression testing | Behavior broken by a change | Cases the test set never had |
Automated evaluation: LLM-as-a-judge and rule-based checks
Rule-based checks are code: valid JSON, length limits, banned terms, and classic evaluation metrics such as exact match where one answer is correct. They are cheap and deterministic but cannot judge whether a paragraph is right.
For open-ended answers, the usual grader is a second model, an approach called LLM-as-a-judge: it reads the answer, a rubric and often a reference answer, and returns a score.
In the MT-Bench study of LLM judges, strong judges matched human preferences over 80% of the time, as often as two humans agree. The same study also found position, verbosity and self-enhancement bias.
So we test the judge too. Groundtruth’s judge is one fixed model at temperature 0, and a validator checks eleven rules on its JSON output before a score counts; after three failed attempts, the question stays unscored rather than guessed.
The whole pipeline, from building the benchmark to validating scores, is MIT-licensed. Each rubric also has a gate worth 2 to 4 of the 10 points that zeroes any answer missing the tested claim, so fluent padding earns nothing.
Adversarial and red-team testing
Red-team testing tries to make the application fail on purpose: jailbreaks, injected instructions, harmful requests, out-of-scope inputs. One red-teaming study released 38,961 attacks, a useful starting set. Your application still needs attacks written for its own tools and users.
Agents can also attack the test. In our AI agent testing, even with the authoring skill hidden, an agent with file access reached the grading rubrics on 13 of 50 questions. We also tested renaming the rubric folder before settling on moving the files out of the repository for every run, which closed the leak.
Human review and expert evaluation
People remain the reference for what no rubric captures, such as whether an answer would mislead an expert. They also catch harness faults: in one of our runs, a mismatched field had the judge grade the wrong question, and the output still looked valid.
Every run also lists the answers the judge flagged as uncertain, for a person to review.
Regression testing across prompt and model versions
Any change can break what used to work: a reworded prompt, a new model version or retrieval index. Regression testing re-runs a frozen test set after each change and compares it with the last accepted run.
The model can change without you. In a study of two hosted models, one model’s accuracy at identifying prime numbers fell from 84% to 51% between its March and June 2023 versions.
Record the model version behind every result, and treat a provider update as a change: it is a common source of model drift in AI.
The grader needs regression tests too. On our WAMEX benchmark, eight answers with known scores are re-scored at the start of each grading run and after every 25 responses. If a gate decision changes, grading stops until the AI evaluation rubric is recalibrated. On another benchmark, a test answer written to score 0 got 10 out of 10, because its gate accepted the right conclusion reached by the wrong route.
Challenges in Testing Generative AI Applications
Four challenges make it harder to decide how to test generative AI. Any AI evaluation framework has to solve them, but generative applications meet all four at once.
No single ground truth for open-ended output
A summary has many acceptable versions, so comparing output with one reference text, as plain model accuracy does, marks good answers wrong. Grade against requirements instead: what the answer must contain, what it must not claim, and which source supports each point.
The references must be right too. When we built ground truth data for AI from old PDF reports, a script checking every evidence anchor word for word found 41 corrections on one build.
Cost and speed of human review at scale
Our eight-model comparison on the Groundtruth leaderboard rests on 1,200 graded answers, and each model update can mean grading again. Nobody re-reads that by hand, so the judge grades everything and people review flagged answers and sampled transcripts.
Evaluating subjective qualities like tone or helpfulness
Split tone and helpfulness into observable components (“states the refund policy”, “uses no jargon”) that a judge or person can check. To check whether a new prompt beats the old, compare answers in pairs. Judges tend to favor the answer shown first, so in pairwise LLM evaluation we ask twice with the order swapped and average the verdicts.
Keeping tests current as prompts and models change
Test sets age: public questions can leak into training data, and real use drifts from the cases you wrote. Our authoring flow for a custom LLM benchmark generates questions, reference answers and rubrics from documents, so a stale set can be rebuilt.
Metrics age too. When we benchmarked a self-improving coding agent, pass@1 (tasks solved on the first try) fell while real success rose, apparently because the agents learned that a failed first attempt returned a useful error message.
Generative AI Testing Tools and What They Handle
Most LLM application testing tools cover one or more of four jobs.
| Tool type | Handles | You still supply |
|---|---|---|
| Automated grading pipelines | Running a judge over test sets, aggregating scores | Tasks, reference answers, rubric, judge validation |
| Prompt regression suites | Re-running fixed cases after each change | A realistic test set and a noise threshold |
| Adversarial test-case generators | Jailbreak and injection variants at volume | Attacks specific to your tools and users |
| Tracing and monitoring | Logging and scoring production traffic | What to sample, and who reviews it |
Before adopting a tool, check that it accepts your own test set and rubric, records which judge produced each score, and reports spread, not only an average. Tools scale the checking, not the judgment: a person still decides the edge cases a judge flags as uncertain.
FAQs
How do you test generative AI applications?
Define what good output looks like, then test three ways: automated evaluation with rule-based checks and an LLM judge, adversarial testing such as prompt injection attacks, and human review of samples. Run each test several times, because output varies, and re-run the set after every change.
What are the main risks of generative AI applications?
Four risks dominate: hallucination (confident but false output), non-determinism (different answers to the same input), unsafe, biased or off-brand content, and prompt injection, where text the model reads overrides its instructions. The Generative AI Profile from NIST, the US standards agency, lists 12 risks in total.
What testing methods work best for generative AI?
A combination. Rule-based checks catch format failures cheaply, and an LLM judge grades open answers at scale once tested on answers with known scores. Red-team testing finds attacks, human review catches what automation misses, and regression testing confirms that a change broke nothing.
Why is testing generative AI harder than testing traditional software?
Traditional software returns the same output for the same input, so a test compares it with one expected result. Generative AI can answer differently each run, has many acceptable answers, and fails in ways that look correct. Teams deciding how to test generative AI therefore rely on rubrics, repeated runs and graders that are themselves tested.
What tools are used to test generative AI applications?
Four kinds: automated grading pipelines that run test sets through an LLM judge, prompt regression suites that re-run fixed cases after each change, adversarial generators that produce attack variants, and tracing tools that log and score production traffic. Your own test data and rubric still decide the result.