TL;DR: LLM-as-a-judge
- One model scores another model’s output against a rubric. It provides a scalable, cost-effective way to grade thousands of answers instead of a few dozen.
- The method is only as trustworthy as three things behind it: the rubric design, the bias controls, and a validation run on answers with known scores.
- Scoring one answer and comparing two answers are different jobs, and using the wrong one is a common mistake.
Key Takeaways
- Single and pairwise judging answer different questions. A single score tells you how good an answer is; a pairwise verdict only tells you which of two wins, and can’t become a leaderboard score on its own.
- Rubric design decides what the judge can detect. A vague rubric lets a confident, wordy answer score well. A gate, one requirement that zeroes the score if missed, closes that gap.
- Position, self-preference and verbosity bias are well documented. Judges favour the answer shown first, outputs from their own model family, and longer answers, unless controlled.
- Validate the judge on fixtures before it grades real output. Answers with known scores catch double-counted credit that a normal-looking judge response would hide.
Grading a model’s answer used to mean a person reading it. That works for a few dozen answers, not for the thousands a benchmark produces, and not at the speed teams now ship model updates. Engineering teams now turn to automated LLM evaluators to replace manual grading. LLM-as-a-judge provides a practical way to scale evaluation. One model scores another’s output at a fraction of human cost and time.
What Is LLM-as-a-Judge?
LLM-as-a-judge is the practice of using a language model to score or compare another model’s output against a rubric or reference answer, in place of a human reviewer. Deploying automated LLM evaluators is faster and cheaper than maintaining a human panel, but the approach introduces distinct failure modes from position bias to inventing an ungrounded score.
No team can put hundreds of benchmark questions in front of human graders for every model release. A judge model can, but its score is only worth trusting when its evaluation mechanics are verified.
We run one ourselves. Groundtruth, our dynamic benchmark for geological reasoning, grades every answer with openai/gpt-5.5 as judge. Most of what follows comes from what broke while running that judge in production, and what we built to catch it.
Why Use LLMs as Judges Instead of Humans or Classic Metrics?
Teams use LLMs as judges because manual human review cannot scale across thousands of candidate outputs per release cycle, while classic automated metrics fail on open-ended reasoning. Deterministic string metrics such as exact match, BLEU, and ROUGE evaluate surface n-gram overlap rather than semantic correctness. They penalize valid technical answers that express accurate conclusions in alternative vocabulary, and reward fluent text that matches phrasing while hallucinating the core mechanism.
An automated LLM judge delivers rapid, consistent evaluations across deep test suites at a fraction of human cost. However, adopting model-based evaluation involves an explicit operational trade-off: exchanging human grading latency for the discipline of controlling judge-specific biases. Without systematic bias mitigation and mechanical validation checks, an uncalibrated judge introduces distortions rather than objective measurement.
What Are the Main LLM-as-a-Judge Use Cases?
Automated LLM-as-a-judge use cases span five core workloads:
| Use Case | Mode | Example |
|---|---|---|
| Benchmark scoring | Single | Groundtruth benchmark |
| Model comparisons | Pairwise | Base versus fine-tuned models |
| Agent evaluation | Both | AI agent evaluation |
| Data filtering | Single | Pre-training reasoning checks |
| Policy checks | Single | Safety and compliance auditing |
Use single scoring when you need a number for each answer, and pairwise comparison when the question is whether one version beat another. Agent evaluation often needs both.
Benchmark and Leaderboard Scoring
Pointwise rubrics score static suites to track rankings over time.
Model Comparisons
Pairwise prompts test whether candidate checkpoints outperform baselines on identical queries.
Agent and Application Evaluation
Evaluators trace tool invocations and execution paths across agent trajectories.
Synthetic Data Filtering
Automated gates screen reasoning chains to remove hallucinations before training.
Content Quality and Policy Checks
Classification rubrics flag unsafe or non-compliant outputs before production release.
Teams combine these workloads in how to benchmark AI models to measure performance across releases.
Single vs. Pairwise Judging: Which Should You Use?
A judge can answer two different questions, and they require different setups. We referenced this same split from Google’s agent evaluation metrics templates when designing our own.
How Does Single (Absolute) Scoring Work?
Pointwise scoring shows the judge one answer, the rubric, and usually a reference answer, grading against fixed components in a single call. This produces an absolute score to track over time, compare across a leaderboard, or set a pass/fail threshold against. It is also the mode where a gate applies directly: the judge either finds the core claim in this answer or it does not.
How Does Pairwise Comparison Work?
Pairwise comparison presents two answers to determine which is superior, returning a relative verdict rather than a numerical score. Done properly, it requires two judge calls per question: evaluating both orders helps detect and reduce position bias, and a flipped verdict is treated as no preference. That second call exists to mitigate position bias, one of the primary failure modes in LLM as a judge evaluation.
Pairwise comparison is the right tool to decide which answer is better, but cannot feed a leaderboard alone because it produces no absolute score to aggregate.
Single vs Pairwise at a Glance
| Single (pointwise) scoring | Pairwise comparison | |
|---|---|---|
| What the judge sees | One answer, the rubric, usually a reference answer | Two answers to the same question |
| What it returns | A score against fixed components, such as 0 to 10 | A verdict: “A is better”, “A is much better” |
| Judge calls per question | One per answer | Two, one in each answer order |
| Answers the question | “How good is this answer?” | “Which of these two is better?” |
| Can feed a leaderboard | Yes, scores aggregate across questions | Not on its own; there is no absolute score to add up |
| Main bias to control | Verbosity, handled by a gate in the rubric | Position, handled by swapping the order |
In practice the two work together. We score every answer pointwise for the leaderboard, and use pairwise comparison when the question is whether a fine-tuned model beat its own base model.
How Do You Design and Calibrate an LLM-as-a-Judge Rubric?
The rubric a judge grades against decides what the judge can find, before the judge ever runs. An uncalibrated LLM-as-a-judge rubric that rewards a fluent, comprehensive-sounding answer will pass one, whether or not it commits to the claim being tested.
Why Does a Gate Stop Fluent Answers Collecting Partial Credit?
The fix that does the most work in our dynamic benchmarking rubrics is a gate. One component tests the single claim or mechanism the question exists to check, and missing it zeroes the entire answer, however good the rest is. Without a gate, a long answer covering adjacent topics collects partial credit everywhere, landing at a respectable score while missing the point entirely.
How Do Calibration Fixtures Catch Double-Counted Credit?
A rubric that looks correct on a read-through can still double-count credit, and rereading it will not show the defect. Running fabricated answers with predicted scores (calibration fixtures) through the actual judge will.
Across two 50-question benchmarks we built this way, 14 and 16 fixtures out of 200 scored higher than predicted. In each case, a component awarded credit for something the gate already required, giving passing answers unearned credit. How to Benchmark AI Models puts these numbers in the wider construction process.
Calibration does not run itself. In our harness, fixture checking is a deliberate manual pass that the scoring run never performs automatically. Designing an LLM-as-a-judge rubric without calibration fixtures means passing a scoring guide no one has actually tested.
What Biases Affect LLM-as-a-Judge?
The foundational LLM-as-a-judge study is Zheng et al.’s “Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena”. The authors found that a strong judge like GPT-4 reaches over 80% agreement with human preferences, matching agreement between human graders. The paper also measured position bias, verbosity bias, and self-enhancement bias as the failure modes behind the remaining gap. Understanding LLM-as-a-judge bias is essential before trusting automated scores.
Position Bias
Position bias is the tendency to favour whichever answer appears first, independent of its content. The direct defence against position bias is to judge the same pair twice, once in each order, and treat a flipped verdict as no preference. That is why pairwise comparison costs two calls, not one.
Self-Preference Bias
Self-preference bias shows up when a judge favours outputs from its own model family. This creates an immediate conflict of interest when a judge evaluates candidates sharing its lineage, such as a GPT-family judge scoring GPT-family candidates. The honest response is to disclose it in the methodology rather than leave readers to notice it themselves.
Verbosity Bias
Verbosity bias rewards length and confidence over correctness. A gated rubric helps reduce this risk: components score specific things decided in advance, so a long answer that avoids the tested claim gets nothing extra for its length.
How Reliable Is LLM-as-a-Judge?
An LLM judge can be reliable for a defined evaluation task when its rubric, inputs, and outputs are systematically validated; without strict controls, scores risk becoming unreliable or misleading. Asking how reliable is LLM-as-a-judge misses the operational reality: a judge model is only as dependable as the rubric, bias mitigations, and input validation wrapped around it.
The Zheng study’s agreement result for GPT-4 applies to its tested conversational prompts, not to all frontier judges or specialized tasks. In technical evaluation, scores risk becoming inconsistent if rubrics leak partial credit or prompts suffer formatting drift. In our benchmark authoring, calibration fixtures uncovered rubric defects in 14 and 16 of 200 cases that human reviewers missed during read-throughs. Verifying rubrics on fixtures, swapping presentation orders, and auditing input transcripts can substantially improve reliability across an evaluation pipeline.
How Can You Improve LLM-as-a-Judge Judgements?
Improving the accuracy and stability of an automated judge requires systematically addressing known biases. Applying six engineering levers helps improve evaluation quality:
- Judge pairs in both orders: Evaluating pairs in both presentation orders helps detect and reduce position bias, treating a flipped verdict as no preference.
- Use a gated, single-claim rubric: Anchoring criteria with a gated rubric helps reduce verbosity bias and limits partial credit leaks.
- Provide an authoritative reference answer: Grounding prompts with a verified reference answer helps reduce the risk of hallucinated scoring criteria.
- Disclose or avoid shared model lineage: Documenting or avoiding shared model lineage helps reduce the risk of self-preference distortions.
- Require a structured output contract: Enforcing a structured output contract helps catch malformed outputs and reduces ungrounded scores.
- Calibrate on fixtures and spot-check transcripts: Auditing calibration fixtures helps expose rubric defects, while spot-checking transcripts verifies input integrity.
How to Build an LLM Judge: A Reliable Evaluation Pipeline
Understanding how to build an LLM judge requires connecting rubric design, schema validation, and bias controls across seven stages:
- Decide the evaluation objective: Determine whether the task requires a single score against a rubric or pairwise comparison to decide which candidate answer is superior.
- Author a gated rubric: Write criteria centered on a mandatory gated rubric testing the core claim, where missing that gate zeroes the score so fluent answers cannot collect partial credit.
- Define a structured output contract: Bind the judge to machine-checked JSON schemas, following an LLM judge that cannot invent a score to enforce validation rules and reject malformed responses.
- Calibrate against known fixtures: Test fabricated answers with predicted scores across the score spectrum to catch double-counted credit, following testing the rubric before you test the model.
- Implement bias mitigations: Evaluate pairs in both orders where a flipped verdict is recorded as no preference, and document shared lineage to control systemic biases.
- Spot-check raw execution transcripts: Check prompt logs to verify the question text passed to the judge matches the rubric rather than grading the wrong question from corrupted harness inputs.
- Apply the validated judge to real evaluation outputs: Score candidate outputs with schema validation, applying two checks instead of one to record unparseable responses as unscored after retries fail rather than guessing.
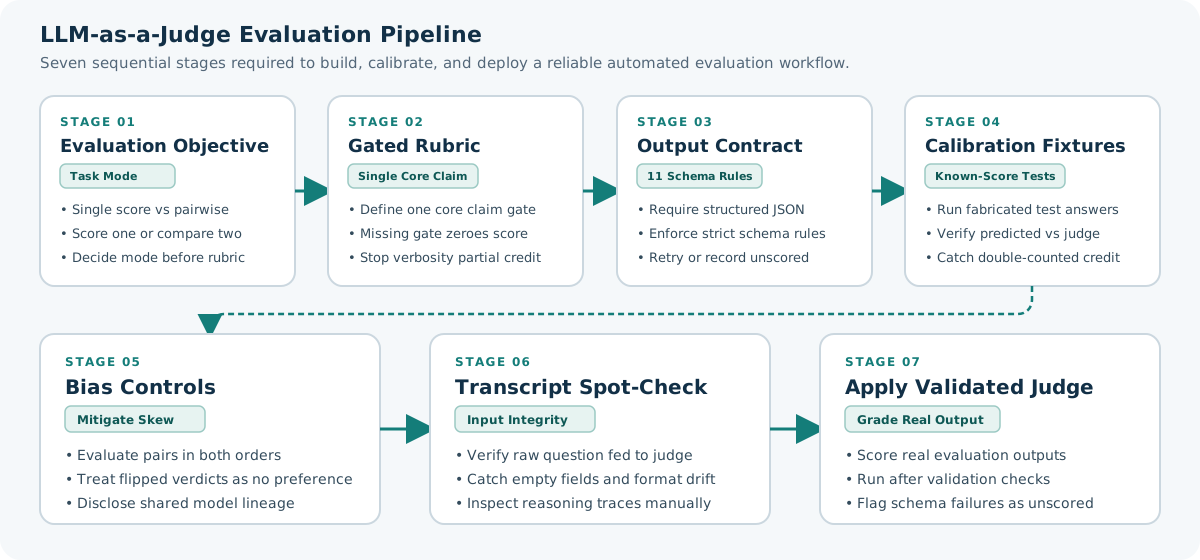
Executing these stages in order helps prevent scoring bugs from corrupting evaluation results.
What Are the Best Practices for Validating an LLM Judge Before Deployment?
None of the structural fixes above catch every way a judge can go wrong, because some failures are not about the judge’s reasoning at all. Applying established LLM-as-a-judge best practices requires verifying what the evaluator was actually asked to grade.
When Does the Judge Grade the Wrong Question?
In one benchmark we ran, the harness pulled the question text for the judge from the answer file rather than from the rubric. When an answer file carried an empty or mismatched question field, the judge graded against the wrong question, or an empty one. The harness logging only printed a warning and kept running. The output looked valid because the judge answered the question it received; a contract validator checking output shape cannot catch it.
Why Do You Need Two Checks, Not One?
That is the practical case for two separate checks. A structured output contract catches malformed responses. Ours enforces eleven rules, re-grading up to three times before recording a question as unscored rather than guessing. Fixture calibration, run before real grading, catches structurally defective rubrics.
Neither check catches a judge given the wrong input entirely. That is why spot-checking real transcripts, not just the judge’s output, stays a manual step even after both automated checks pass.
LLM Judge vs Human Evaluation: Which Is Better?
When comparing an LLM judge against human evaluation, the agreement findings for GPT-4 in the Zheng study apply specifically to its tested general conversational prompts. That benchmark result does not establish comparable agreement on specialized or domain-specific evaluation tasks. Automated judges also fail to detect corrupted or mismatched harness inputs, so human comparison and transcript spot-checking remain essential for auditing scoring accuracy.
When Should You Not Use an LLM Judge?
An LLM judge is unsuitable for deterministic tasks with exact answers, high-stakes decisions requiring human sign-off, and specialized frontiers exceeding model capabilities. They are also impractical for tiny sample sizes or evaluations with unmitigated lineage conflicts. In these cases, programmatic checks, human review, or simpler evaluations provide higher fidelity at lower cost.
The table summarizes the situations and what to use instead.
| Situation | Use an LLM judge? | Alternative |
|---|---|---|
| Objective tasks with exact answers | No | Exact-match checks, unit tests or code execution |
| High-stakes compliance and safety | No | Human experts in the decision loop |
| Specialized domain frontiers | No | Domain-expert review |
| Small evaluation sample sizes | No | Manual human review |
| Unmitigated lineage conflicts | No, unless mitigated or disclosed | A judge from a different model family, or human review |
Frequently Asked Questions
What does LLM-as-a-judge mean?
LLM-as-a-judge is the practice of using a language model to score or compare AI-generated outputs against a rubric or reference answer, replacing manual human reviewers for evaluation at scale. It allows engineering teams to grade thousands of complex model responses consistently and quickly across continuous release cycles, provided the judge operates under explicit bias controls and structural validation.
Is LLM-as-a-judge reliable?
An LLM judge can be reliable when constrained by calibrated rubrics, strict output schemas, and systematic bias mitigations. The agreement finding cited above applies to the general conversational prompts tested in that study, not automatically to specialized tasks, and unmitigated biases or prompt delivery errors risk producing inconsistent evaluations. Applying disciplined rubric, input, and output controls can substantially improve evaluation reliability.
What is the difference between single and pairwise judging?
Single pointwise scoring evaluates one model output against a rubric to produce absolute numerical scores suitable for tracking over time and populating leaderboards. In contrast, pairwise comparison presents two candidate answers to determine which response is superior. Pairwise evaluation requires bidirectional runs to detect and reduce position bias, but it cannot produce aggregate leaderboard scores on its own.
How do you reduce bias in an LLM judge?
Run every pairwise comparison in both answer orders to help detect and reduce position bias, treating a flipped verdict as no preference. Disclose shared lineage between judge and candidate models rather than ignoring the conflict, as we do for our own judge in AI Agent Evaluation: Frameworks, Metrics, Benchmarks, and Best Practices. Use a gated rubric so verbosity and confidence cannot substitute for the core claim being tested.
What are the main use cases for LLM-as-a-judge?
The primary LLM-as-a-judge use cases span five workloads. Teams grade benchmark leaderboards, conduct pairwise comparisons between model variants, and evaluate multi-step agent trajectories. Evaluators also filter synthetic training datasets and enforce safety policies on live outputs. Teams deploy pointwise scoring for absolute tracking and pairwise comparisons for head-to-head model selection.
Why use LLMs as judges instead of humans?
Teams use LLMs as judges because manual human review cannot scale across thousands of outputs generated per release cycle, while classic metrics such as BLEU or ROUGE fail on complex semantic reasoning. Automated model judges provide fast, repeatable scoring at sustainable cost, provided teams manage the trade-off by strictly controlling judge biases and input validation.
How do you build an LLM judge?
To build a reliable LLM judge, decide whether the evaluation objective requires single scoring or pairwise comparison, write a gated rubric centered on the core claim, and enforce a structured JSON contract. Calibrate the rubric against known test fixtures, apply bidirectional bias controls, and spot-check raw input transcripts before scoring real evaluation outputs.
When is an LLM judge not suitable?
An LLM judge is unsuitable when simpler or more rigorous methods exist. Skip model judges for deterministic tasks with exact answers, high-stakes decisions requiring human sign-off, and specialized frontiers exceeding model capabilities. They are also impractical for tiny sample sizes or evaluations with unmitigated lineage conflicts. In these cases, programmatic checks, human review, or simpler evaluations provide higher fidelity at lower cost.
What is the difference between LLM-as-a-judge and human evaluation?
While the Zheng study measured GPT-4’s agreement with human preferences on its tested general conversational prompts, that does not establish agreement across specialized tasks. Automated judges evaluate outputs faster and at lower cost, but they cannot catch corrupted prompts or external harness failures. Human evaluation and transcript spot-checking remain essential for auditing test inputs, verifying rubric alignment, and catching defects that model evaluators miss.