TL;DR
- LLM infrastructure combines compute, storage, networking, and serving systems to support the training and deployment of large language models.
- Compute infrastructure includes GPU clusters and distributed training frameworks that handle resource-intensive model training.
- Serving infrastructure manages live requests, ensuring models deliver responses efficiently and reliably in production.
- Scalability and cost planning should begin early, as pilot workloads rarely reflect actual production demands.
- Infrastructure costs are driven primarily by accelerator usage during training and inference volume during deployment, rather than software licensing.
Key Takeaways
- The stack spans training and inference. Training infrastructure optimises for large-scale distributed compute; inference infrastructure optimises for latency and cost per request.
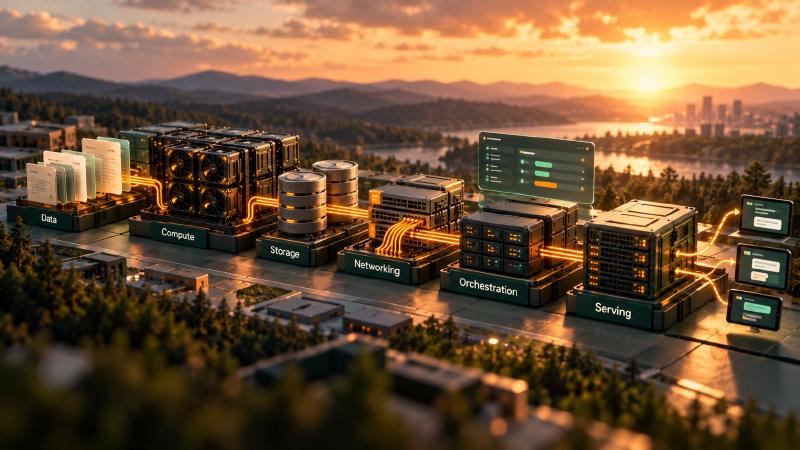
- The same components recur. Compute, storage, networking, orchestration and a serving layer appear in nearly every stack.
- Scaling is a cost and reliability problem. Autoscaling, caching and hardware utilisation shape real cost, not just raw compute added.
- Compute and inference volume dominate cost. Accelerator time and ongoing requests outweigh software licensing over time.
LLM infrastructure provides the foundation needed to move a language model from development into real-world applications. A trained model alone cannot process requests or deliver responses without the supporting systems. It requires accelerators, memory, storage, network bandwidth, and software that manages resources, maintains performance, and ensures reliability.
The infrastructure requirements vary depending on whether models are trained from scratch, accessed through external providers, or deployed on local compute systems. Each approach introduces different considerations around cost, scalability, performance, and data handling. This article explores the key components of LLM infrastructure, the trade-offs involved, and the practical factors that influence deployment decisions.
What Is LLM Infrastructure?
LLM infrastructure is the stack of compute, storage, networking and serving systems that makes training and running large language models possible. The LLM infrastructure stack spans GPU clusters and distributed training frameworks through to the serving layer that handles live requests.
It supports two different jobs. Training builds or adapts a model, and runs for days or weeks as one large coordinated computation. Inference answers requests with a finished model, and runs continuously, shaped by user traffic.
| Training infrastructure | Inference infrastructure | |
|---|---|---|
| Optimizes for | Throughput across a large cluster | Latency and cost per request |
| Workload shape | A few very large, long jobs | Many small, concurrent requests |
| Hardware focus | Accelerator count, interconnect, checkpoint storage | Accelerator memory and bandwidth, batching |
| Cost of failure | Lost progress since the last checkpoint | Failed or slow requests for users |
| Scales with | Model and data size | Request volume and context length |
Key Components of LLM Infrastructure
Four layers carry most of the load, with a fifth, scheduling and orchestration, allocating jobs and replicas across hardware. Cluster schedulers handle the first stage for training jobs, and container platforms often handle the second for serving replicas.
Compute (GPUs / accelerators)
Accelerators do the numerical work, and their memory decides what fits. Weights take roughly parameter count times bytes per parameter, so a 13-billion-parameter model needs about 26 GB at 16-bit precision. Training needs several times more, since gradients and optimizer state are stored alongside the weights; the ZeRO paper puts it at about 16 bytes per parameter for Adam in mixed precision.
Memory bandwidth matters as much as capacity for inference: generating each token requires reading the weights, so bandwidth sets a ceiling on speed. On a local machine with 24 GB of GPU memory at 432 GB/s, a 4-bit model of about 3.5 GB cannot generate much faster than around 100 tokens per second per stream, whatever the arithmetic throughput.
Storage and data pipelines
Training reads a large tokenised corpus at a rate that keeps accelerators busy, so storage throughput and the data pipeline can bottleneck an expensive cluster. Training also writes checkpoints, large snapshots saved often enough to limit lost work. On the inference side, storage holds model artefacts and any retrieval indexes that feed context to the model.
Networking and distributed training support
When a model or batch is split across devices, they exchange activations and gradients constantly. Interconnect bandwidth and latency, within a server and between servers, can limit training speed more than raw compute. Inference needs the same links when one model is split across several accelerators.
Serving and inference layer
The serving layer receives requests, batches them, runs the model and streams responses back, while managing memory for each request’s cached context. It determines latency and cost per request, and it is covered in detail under serving ML models. LLM inference infrastructure is this layer plus the compute under it, and it usually grows faster than training infrastructure once a product has users.
How Does LLM Infrastructure Work? LLM Training Infrastructure and Inference
The two flows share hardware and tooling but behave differently.
The training flow
Data moves through a pipeline of collection, filtering and tokenisation into a distributed training job across a GPU cluster. The job runs for weeks at large scale, writes checkpoints at intervals and evaluates progress on held-out data. LLM training infrastructure exists to keep that job running through hardware failures, which at cluster scale are routine. When the job learns language from raw text, it is LLM pre-training; when it adapts an existing model, it is fine-tuning, which is far lighter on the cluster.
The inference flow
A request reaches a gateway, passes to the serving layer, and runs on an accelerator in two phases. Prefill processes the whole prompt at once and is limited by compute. Decode generates tokens one at a time and is limited by memory bandwidth.
Each request’s cached context takes accelerator memory in proportion to its length, so context size drives both speed and capacity. That makes the input an infrastructure variable: everything in the context window is sent again with each later request, so keeping large datasets out of an agent’s context window is a cost decision as much as a quality one.
How the two share infrastructure
Both draw on the same accelerators, storage and scheduler, and many organisations run them in one cluster. Sharing raises utilisation but creates contention, since a large training job can starve serving. Many setups keep separate pools, or give serving priority and run training on spare capacity.
How to Build LLM Infrastructure for Production: LLM Infrastructure Requirements
LLM infrastructure requirements are easier to set from the workload backwards than from the hardware forward.
Defining requirements: latency, throughput, uptime
Start from the use case. LLM use cases differ sharply: an interactive assistant needs a fast first token and steady streaming, while overnight document processing needs throughput and tolerates delay.
Write targets for time to first token, tokens per second, requests per second and uptime, and set a quality floor in terms of evaluation metrics in machine learning so that cheaper options are tested against it, not assumed acceptable.
Choosing compute and deployment model: cloud, on-prem, hybrid
Cloud capacity scales quickly and suits uneven demand, at a higher price per hour of steady use. Reserved capacity lowers that price in exchange for commitment. On-prem hardware gives control over data and a lower marginal cost at high, steady utilisation, and puts procurement, power and maintenance on you. Hybrid setups keep sensitive or constant work local and send spikes to the cloud. Local deployment also moves the trust boundary inward, which matters most for software that touches files, such as a local MCP server that reads your files.
Setting up monitoring and observability from the start
Track time to first token, tokens per second, latency percentiles, queue depth, accelerator memory and utilisation, error rate and cost per request. Infrastructure signals do not show quality, so also run a fixed evaluation on a schedule, as in an AI evaluation framework.
Watch input distributions too: serving is where model drift in AI is usually noticed first.
Planning for failover and reliability
Run more than one replica across failure domains, with health checks that remove a bad instance. Decide what degrades gracefully: a smaller model can answer when the large one is saturated, and retries with backoff absorb brief faults. For training, frequent checkpoints and automatic restart limit what a failed node costs.
How to Scale LLM Infrastructure
Scaling serving means adding replicas behind a load balancer, but several levers come first:
- Batching. Grouping requests so each pass through the model serves many, which raises throughput at a small latency cost.
- Caching. Reusing computation for repeated prompt prefixes, and storing answers to identical requests where acceptable.
- Autoscaling. Adding and removing replicas on queue depth or concurrency, allowing for the time a large model takes to load.
The bottlenecks to expect are accelerator availability, memory for cached context, network bandwidth between devices and storage throughput during training. Scaling one dimension exposes the next.
Change one variable at a time, whether batch size, precision or the serving framework, and re-run the same fixed test after each change: the basic loop of AI model evaluation.
A test can only detect differences larger than its noise floor, so before reading a before-and-after result as real, measure the resolution of the benchmark. On one 50-question set scored out of 10, the smallest detectable gap was between 0.27 and 0.45 points.
How Much Does LLM Infrastructure Cost?
LLM infrastructure cost is better understood by driver than by price, since prices shift quickly. The main drivers are:
- Accelerator time. Training and inference both consume it, and utilisation decides how much of what you pay for is useful.
- Inference volume. Training is large but bounded; inference recurs with every request and, for a product with users, usually becomes the higher cost over time.
- Tokens per request. Longer prompts and outputs cost more compute and memory, and context resent with every call multiplies the effect.
- Storage, networking and operations. Checkpoints, data transfer and staff time are smaller but not negligible.
Cloud on-demand, reserved capacity and on-prem trade flexibility against unit cost. On-demand costs most per hour and commits you to nothing; reserved lowers the hour at the price of commitment; on-prem has the lowest marginal cost only if utilization stays high.
Models also differ in price for similar quality.
In our geology benchmark, three statistically tied top models differed by about 1.7 times in cost per question, so once accuracy ties, deciding which AI model is best for your geology becomes a cost question. Measure quality first, then buy the cheapest option that clears it.
FAQs
What infrastructure is needed to run an LLM in production?
Running an LLM in production requires compute resources such as GPUs, sufficient accelerator memory, model storage, networking, and an inference serving layer. Production systems also need request scheduling, monitoring, autoscaling, and failover mechanisms to maintain performance and availability under changing workloads.
Can LLM training and inference run on the same infrastructure?
Yes, LLM training and inference can share accelerators, storage, networking, and scheduling systems. However, training jobs can compete with live requests for compute and memory, affecting response times. Separate resource pools or serving-priority scheduling can help maintain reliable inference performance.
How do you choose between cloud, on-premises, and hybrid LLM infrastructure?
Cloud infrastructure suits workloads with variable demand and a need for rapid scaling, while on-premises infrastructure offers greater control over data and can reduce marginal costs at consistently high utilization. Hybrid infrastructure combines both, keeping sensitive or predictable workloads local while using cloud capacity to handle demand spikes.
How do you measure LLM infrastructure performance?
Measure time to first token, tokens generated per second, request throughput, latency percentiles, accelerator utilization, memory usage, error rates, and cost per request. These metrics reveal performance bottlenecks and resource inefficiencies. Model quality should also be evaluated separately to ensure infrastructure optimizations do not compromise response quality.
How can you reduce LLM inference costs without sacrificing quality?
Reduce inference costs by improving batching and accelerator utilization, caching repeated prompt computations, limiting unnecessary context, and selecting an efficient model that meets quality requirements. Benchmark changes against a fixed evaluation set and compare cost per request to confirm that savings do not come at the expense of output quality.