TL;DR LLM-as-a-judge tools use one AI model to grade the answers of another, which lets teams check thousands of answers without reading each one by hand. The open source tools on GitHub differ in what they grade: a single answer against a checklist, two answers side by side, or the documents an AI looked up before answering. A judge can still be biased, for example by favouring whichever answer it reads first, so its scores need checking against human judgments before you trust them.
Introduction
The best open-source LLM-as-a-judge tool depends on what you want to evaluate. Some frameworks score individual responses against a rubric, while others compare two outputs or measure specific parts of a RAG application. This guide compares five GitHub repositories and explains how to choose, calibrate and validate an LLM judge. For a deeper look at LLM-as-a-judge scoring, start with the evaluation criteria, not just the score.
Which Open-Source GitHub Tools Use LLMs as Judges?
1. Groundtruth Dynamic Benchmarking (Eigenform): Rubric-Based Pointwise and Pairwise Scoring
Description
Groundtruth is an open-source benchmark and evaluation harness for testing LLMs on domain-specific geological reasoning. It evaluates candidate answers against source-grounded questions and scoring rubrics.
Why it works
- Generates benchmark questions and rubrics from geological source material.
- Uses an independent judge to score answers from 0–10.
- Applies source-anchored criteria instead of relying on general impressions.
- Supports pointwise scoring, where each answer is graded independently.
- Supports pairwise comparison between two answer files.
- Repeats pairwise comparisons with A/B order swapped to check for position bias.
- Records the judge and candidate model identifiers.
- Separates model evaluation from harness evaluation.
Its two evaluation tracks serve different purposes:
- Model track: Compares models using the same benchmark and evaluation criteria.
- Harness track: Compares retrieval, tools and agent scaffolding while keeping the model fixed.
Is it up to date?
The repository includes a working evaluation pipeline, benchmark configurations and submission instructions. Its README documents the fixed independent judge and the two scoring modes. The project is open-source under MIT for code and prompts. The sample Yudnamutana corpus has separate CC BY 4.0 AU licensing.
Best for
- Evaluating models on specialist-domain reasoning.
- Scoring answers against evidence-based rubrics.
- Comparing two candidate model or harness outputs.
- Testing whether an AI system uses source material correctly.
Additional notes
Pairwise comparison does not replace pointwise scoring. Groundtruth first grades both answer files independently, then adds an order-swapped comparison. Its public leaderboard submissions are self-reported and are not independently re-run.
Groundtruth is a useful example of why judge design matters. Its approach makes the scoring criteria, judge identity and evidence requirements visible. You can also read about position bias in pairwise LLM evaluation to understand why reversing candidate order is an important reliability check.
2. DeepEval: G-Eval and LLM-Based Metrics
Description
DeepEval is an open-source LLM evaluation framework. It provides metrics for testing model outputs, RAG applications and AI agents.
Why it works
- Includes G-Eval for criteria-based LLM judging.
- Supports custom evaluation criteria.
- Evaluates outputs against expected answers and other test-case inputs.
- Provides metrics for correctness, relevance, faithfulness and other application qualities.
- Integrates evaluation into automated testing workflows.
- Supports custom metrics for application-specific requirements.
G-Eval is particularly relevant to LLM-as-a-judge workflows. It uses an evaluation prompt and defined criteria to assess an output. The framework can generate evaluation steps and use them to produce a score.
Is it up to date?
DeepEval is an actively developed project with ongoing documentation and repository updates. Check the current release and supported model integrations before choosing a version for production.
Best for
- Evaluating LLM application outputs.
- Building automated evaluation tests.
- Creating custom scoring criteria.
- Testing RAG and agent workflows.
Additional notes
G-Eval is a judge-based metric, not a guarantee of unbiased evaluation. Results depend on the judge model, criteria, prompt and test cases. Validate its scores against human judgments before using them as a quality gate.
3. Ragas: LLM-Based RAG Metrics
Description
Ragas is an evaluation framework focused on RAG systems and LLM applications. It provides metrics for assessing generated answers and the retrieved context used to produce them.
Why it works
- Evaluates answer relevance and faithfulness.
- Measures context precision and context recall.
- Supports reference-based and reference-free evaluation approaches, depending on the metric.
- Uses LLM-based judging for metrics that require semantic assessment.
- Supports custom metrics and evaluation workflows.
- Helps identify whether poor answers result from retrieval or generation.
For example, a RAG system may return a fluent answer that is not supported by its retrieved documents. A faithfulness metric can assess whether the response is grounded in the supplied context.
Is it up to date?
Ragas continues to develop its evaluation framework and documentation. Its available metrics and integrations can change between versions, so check the current repository and documentation before implementation.
Best for
- Evaluating retrieval-augmented generation systems.
- Measuring answer faithfulness and relevance.
- Testing retrieval quality.
- Identifying weaknesses in RAG pipelines.
Additional notes
Ragas is not a general replacement for every LLM-as-a-judge framework. Its strongest fit is evaluating RAG-related behaviour. Teams comparing general-purpose model responses may need a different evaluation setup.
4. promptfoo: Model-Graded Assertions and Evaluation Workflows
Description
promptfoo is an open-source framework for testing and comparing LLM applications. Its model-graded assertions use an LLM to evaluate outputs against defined criteria.
Why it works
- Supports
llm-rubricfor custom rubric-based grading. - Supports
g-evalfor criteria-based model evaluation. - Provides factuality and closed-question-answering graders.
- Allows teams to define expected output requirements.
- Compares prompts and model outputs through evaluation workflows.
- Integrates model-graded checks into repeatable testing.
For example, a team can define a rubric that checks whether a generated answer addresses a question, follows a required format and avoids unsupported claims. promptfoo can then use a configured grader to assess the result.
Is it up to date?
The repository has active development and regularly updated documentation. Check the current version and grader configuration before using it in a production evaluation pipeline.
Best for
- Comparing prompts and model outputs.
- Testing model responses against custom criteria.
- Adding LLM-based checks to evaluation pipelines.
- Evaluating structured output and response quality.
Additional notes
This article focuses on promptfoo’s model-graded evaluation capabilities. Its wider red-teaming and security-testing features are outside the scope of this comparison.
Do not assume that a model-graded assertion provides the same functionality as a dedicated pointwise and pairwise scoring system. Check the specific grader and evaluation configuration.
5. OpenAI Evals: Custom and Model-Graded Evaluations
Description
OpenAI Evals is an evaluation framework for testing language models and systems built with LLMs. It includes an existing registry of evaluations and supports creating custom evaluation workflows.
Why it works
- Provides an evaluation framework for model and application testing.
- Includes a registry of existing evaluations.
- Supports private evaluations using a team’s own data.
- Provides examples and documentation for building evaluations.
- Supports model-graded evaluation configurations.
- Can evaluate prompt chains and tool-using systems through its completion-function approach.
Is it up to date?
The GitHub README remains available and points users to the OpenAI Dashboard for configuring and running evaluations. It also contains an important contribution caveat: the project is not currently accepting evaluations with custom code, although model-graded YAML evaluations can still be submitted.
Best for
- Building evaluations for specific model use cases.
- Testing model behaviour against custom datasets.
- Evaluating prompt-based and tool-using systems.
- Exploring model-graded evaluation configurations.
Additional notes
OpenAI Evals is a broader evaluation framework, not a dedicated pairwise LLM judge. Check the current documentation for the supported evaluation format and contribution requirements before building around it.
LLM-as-a-Judge GitHub Tools Compared
| Tool | Judge method | Scoring mode | Bias controls | Language |
|---|---|---|---|---|
| Groundtruth | Independent judge against source-anchored rubrics | Pointwise 0–10 and pairwise | A/B order swapping; judge identity recorded | Python |
| DeepEval | G-Eval and custom LLM metrics | Criteria-based scoring | Depends on metric and evaluation setup | Python |
| Ragas | LLM-based RAG metrics | Metric-specific scores | Metric-specific; requires validation | Python |
| promptfoo | Model-graded assertions and G-Eval | Rubric-based grading and assertions | Depends on grader and prompt configuration | TypeScript |
| OpenAI Evals | Model-graded and custom evaluations | Eval-specific scoring | Depends on evaluation design | Python |
These tools do not all implement the same judging method. Groundtruth explicitly supports pointwise scoring and order-swapped pairwise comparison. The other frameworks provide LLM-based metrics or model-graded assertions, but should not automatically be treated as native pairwise-ranking systems.
Pointwise vs Pairwise LLM-as-a-Judge Evaluation
Pointwise Scoring: Grade One Answer Against a Rubric
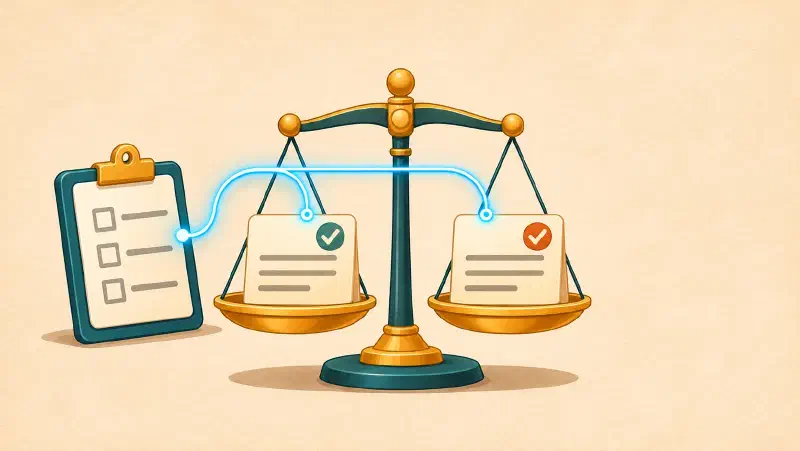
Pointwise evaluation grades one response at a time.
The judge receives an answer and a set of evaluation criteria. It then assigns a score based on how well the answer meets those criteria.
For example, imagine an AI assistant answering:
Which geological formations are associated with the mineral deposit?
A pointwise rubric might evaluate:
- Whether the correct formations are identified.
- Whether the answer uses evidence from the supplied source.
- Whether important geological relationships are explained.
- Whether unsupported claims are avoided.
The judge could assign a score from 0–10 based on the rubric.
When to use it
- Measuring an answer against a fixed quality standard.
- Tracking model performance across repeated benchmark runs.
- Evaluating factual accuracy and completeness.
- Checking whether an answer meets specific requirements.
Pointwise scoring is useful when you need an individual performance score rather than a preference between two answers.
Pairwise Comparison: Choose Between Two Answers
Pairwise evaluation compares two candidate responses to the same question.
The judge receives Answer A and Answer B, along with the evaluation criteria. It decides which answer performs better, or whether the two are equivalent.
For example:
| Evaluation | Answer A | Answer B |
|---|---|---|
| Accuracy | Identifies two relevant formations | Identifies three, including one unsupported formation |
| Evidence | Uses source evidence | Includes one unsupported claim |
| Completeness | Covers the main relationship | Covers more detail but includes an error |
A judge may prefer Answer A because it is more accurate, even though Answer B is longer.
When to use it
- Comparing a new model with a baseline.
- Testing whether a fine-tune improves output quality.
- Comparing two prompts or agent configurations.
- Evaluating two versions of a response.
Pairwise evaluation gives a relative preference. It does not tell you whether either answer meets an absolute quality standard.
Order Swapping: Check Whether Position Changes the Verdict
Position bias occurs when a judge favours an answer because it appears first or second, rather than because of its quality.
A simple mitigation is to run the comparison twice:
- First run: Answer A appears before Answer B.
- Second run: Answer B appears before Answer A.
- Compare the two verdicts.
- Record whether the preference remains consistent.
For example:
| Run | First answer | Second answer | Judge preference |
|---|---|---|---|
| 1 | Answer A | Answer B | A |
| 2 | Answer B | Answer A | A |
The judge selected Answer A in both runs. This is a more consistent result than a preference that changes when the order is reversed.
If the judge selects A in the first run and B in the second, the result should be treated cautiously. It may indicate position sensitivity.
Research on position bias in LLM-as-a-judge evaluations shows that answer order can affect pairwise judgments. Order swapping helps expose this problem, but it does not eliminate every source of bias.
Common Biases and Reliability Problems in LLM Judges
Position Bias and Presentation Order
A judge may favour the first or second response based on its position in the prompt.
This is particularly relevant to pairwise comparisons. Reversing answer order and comparing the results can reveal inconsistent preferences.
However, order swapping is a diagnostic and mitigation technique, not proof that the judge is unbiased.
Verbosity, Style and Self-Preference
LLM judges may respond to features that are not the main evaluation target.
Examples include:
- Preferring a longer answer because it appears more complete.
- Rewarding polished writing even when the evidence is weak.
- Penalising concise answers that satisfy the rubric.
- Favouring outputs that resemble the judge’s own preferred response style.
Self-preference is another concern when the judge and candidate models are related or share similar behaviour.
These effects depend on the task, model and evaluation prompt. Do not assume that every judge has the same bias or that longer answers always receive higher scores.
Rubric Quality and Judge Calibration
A vague rubric produces inconsistent results.
For example, a criterion such as “provide a good explanation” does not tell the judge what a good explanation contains.
A stronger rubric defines:
- Required facts or concepts.
- Evidence that supports each criterion.
- What qualifies for full or partial credit.
- Common mistakes that should lose marks.
- Conditions that should result in a failing score.
Calibration examples can help. Run the judge against sample answers with known expected outcomes. Review whether its scores match the intended criteria.
Reproducibility and Judge Identity
A score is difficult to reproduce if the evaluation setup is not recorded.
Keep track of:
- Judge model and version.
- Candidate model and version.
- Evaluation prompt.
- Rubric and dataset version.
- Temperature and other inference settings.
- Evaluation date.
- Raw judge outputs and final scores.
Changing the judge model between benchmark runs can make comparisons unreliable. A score of 8 from one judge is not automatically equivalent to an 8 from another.
How to Choose and Validate an LLM Judge
Match the Judge to the Evaluation Task
Start with the question you need to answer.
| Evaluation requirement | Suitable approach |
|---|---|
| Score one answer against fixed criteria | Pointwise rubric scoring |
| Compare two model outputs | Pairwise evaluation |
| Evaluate retrieval and generated answers | RAG-specific metrics such as Ragas |
| Test custom response requirements | Model-graded assertions such as promptfoo |
| Evaluate specialist reasoning against evidence | Source-grounded rubrics such as Groundtruth |
Do not select a framework just because it offers the largest number of metrics. Choose one that supports the actual evaluation task.
Validate Against Human or Trusted Reference Judgments
Before relying on an LLM judge, create a small validation set.
Include:
- Clearly correct answers.
- Partially correct answers.
- Incorrect answers.
- Answers with unsupported claims.
- Answers that are concise but complete.
- Answers that are detailed but contain errors.
Have qualified reviewers score the same examples using the rubric. Compare their judgments with the LLM judge’s results.
Review disagreements instead of hiding them in an average score. A judge that consistently misses an important domain-specific error needs a better rubric or a different evaluation setup.
Keep the Evaluation Auditable
A useful evaluation should be repeatable and inspectable.
Keep the prompts, rubrics, model identifiers, raw responses and final scores together. Record the cost and number of judge calls as well.
Use this implementation checklist:
- Define the evaluation task and expected outcome.
- Select pointwise, pairwise or metric-based evaluation.
- Write explicit scoring criteria.
- Include source evidence or reference answers where needed.
- Select and record the judge model.
- Test against human-reviewed examples.
- Run order-swapped comparisons where pairwise judging is used.
- Review disagreements and unexpected scores.
- Record prompts, versions, outputs and evaluation costs.
- Revalidate after changing the judge, rubric or candidate model.
Conclusion
LLM-as-a-judge tools make it easier to evaluate generated answers at scale, but the framework alone does not guarantee reliable results.
Use DeepEval for application-level metrics, Ragas for RAG evaluation, promptfoo for model-graded assertions and OpenAI Evals for custom evaluation workflows. Consider Groundtruth when you need source-grounded pointwise and pairwise evaluation for specialist-domain reasoning.
The important part is making the evaluation criteria visible. A useful judge needs a clear rubric, a consistent identity, bias checks and validation against trusted judgments. Without those controls, an automated score can look precise while measuring the wrong thing.
FAQs
What are the best open-source GitHub tools for LLM-as-a-judge evaluation, and how do pointwise scoring, pairwise comparison and bias mitigation differ?
Groundtruth, DeepEval, Ragas, promptfoo and OpenAI Evals offer different forms of LLM-based evaluation. Pointwise scoring grades one answer against criteria, while pairwise comparison ranks two answers. Bias mitigation includes techniques such as order swapping, rubric calibration and human validation.
What is LLM-as-a-judge evaluation?
LLM-as-a-judge evaluation uses a language model to score or compare generated outputs against a prompt, rubric, reference answer or defined criteria.
What is the difference between pointwise and pairwise LLM judging?
Pointwise judging assigns an individual score to one answer. Pairwise judging compares two answers and selects the stronger response or a tie.
Why does order swapping matter in pairwise LLM evaluation?
A judge may favour an answer because it appears first or second. Reversing the order helps identify whether the preference changes with presentation position.
Can LLM judges be trusted to evaluate other LLMs?
They can support evaluation at scale, but their results need validation. Use clear rubrics, consistent judge models, human-reviewed examples and bias checks before relying on their scores.
How does Groundtruth handle pairwise evaluation?
Groundtruth first scores each answer against its source-anchored rubric. It then compares two answer files and repeats the comparison with A/B order swapped. See the Groundtruth GitHub repository.