TL;DR
- LLM powered autonomous agents use a language model as a reasoning engine that plans, acts through tools and adjusts its next step based on the results, with minimal step-by-step human direction. The loop of plan, act and observe, repeated until the task is done or the agent stops, is what separates them from a single LLM call.
- Most designs share four components: planning, tool use, memory and stopping logic. Deployment is mostly a problem of reliability and control, not capability.
Key Takeaways
- Autonomy comes from the loop, not the model alone. A model answering one prompt is not an agent; the plan, act and observe cycle is what makes it one.
- Implementation is mostly scoping the loop. What tools the agent may use, how it stores state and when it stops matter more than model choice.
- Use cases cluster around multi-step tasks with clear tool access. Research, coding, data processing and workflow automation are where agents perform best today.
- The main challenges are reliability and control. Agents can loop, take unintended actions or drift off-task without guardrails and evaluation.
LLM powered autonomous agents are language models given the means to act: tools to call, a place to keep notes and a loop that lets them try, check and try again. The idea is simple to state and demanding to deploy, because an agent that can act can also act wrongly, repeatedly and at speed.
We build and test autonomous AI agents at Eigenform, so the examples below come from running them on real geological data and from measuring them in a benchmark. This article stays on what an agent is and how it is built, and leaves the depth on evaluation and benchmarking to the pieces linked along the way.
What Are LLM Powered Autonomous Agents?
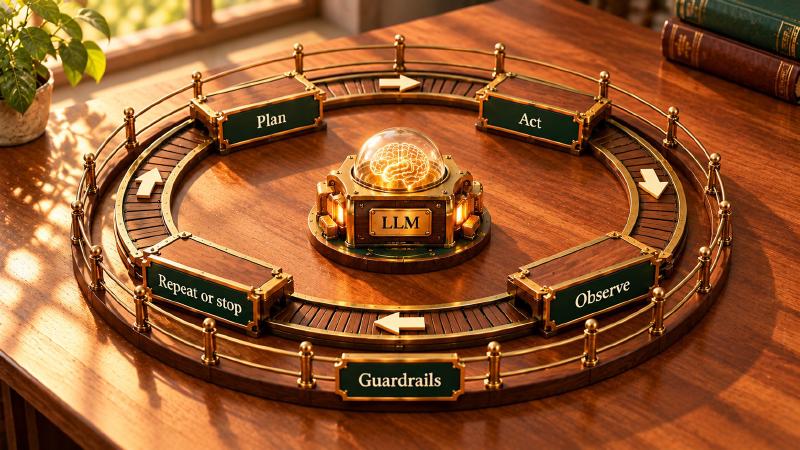
LLM powered autonomous agents are systems that use a large language model as a reasoning engine to plan a task, act through tools, observe the results and adjust the next step, with minimal step-by-step human direction. The loop of planning, acting and observing separates them from a single LLM call.
Autonomy is a spectrum, not a switch. At one end, a single call returns text and stops. In the middle, a scripted workflow runs fixed steps in a fixed order, with a model filling in parts.
At the other end, an agent decides which step comes next, runs it, reads what happened and decides again. Autonomous AI agents differ from workflows in who holds that decision: the code, or the model.
Core Components of LLM Powered Autonomous Agents: LLM Agent Architecture
A widely cited 2023 overview by Lilian Weng describes the LLM agent architecture as a model acting as the brain, supported by planning, memory and tool use. Most current designs add a fourth part, logic for stopping. Our own Geocluster Research Harness follows this shape, and the sections below use it as a concrete reference.
Planning / reasoning layer
The planning layer turns a goal into steps and decides the next action. It can work one step at a time, choosing an action, reading the result and choosing again, or it can write a plan first and revise it as results arrive. Task decomposition breaks a large goal into smaller ones; self-reflection reviews earlier steps and corrects them. The model does this reasoning itself, which is why planning quality depends on the model and the prompt that frames the task.
Tool use and action execution
Tools are how an agent acts: searching, reading files, running code, calling APIs. Each tool is described to the model, and the model picks one by reading the description, so the description is part of the architecture. MCP tool design, how it is named, what it accepts and what it returns shapes how well the agent uses it. Results come back to the agent as observations that feed its next decision.
Memory (short-term and long-term)
Short-term memory is the model’s context window: the task, the history of steps and the tool results so far. It is limited, and it fills quickly when tool results are large. Long-term memory is external storage the agent writes to and reads from, such as files or a database. The practical rule is to keep bulk data out of context and pass references instead.
Related: How to keep large datasets out of an AI agent’s context window.
Stopping and self-assessment logic
An agent needs to know when it is finished, and when it should give up. Stopping logic combines limits on steps, time and cost with a judgment about whether the goal is met. Self-assessment is the weak point, because models tend to declare success on thin evidence. A design that lets the agent report that it cannot complete the task is safer than one that forces an answer, which is the same reason an LLM judge that cannot invent a score leaves an item unscored after repeated failures.
How Do AI Agents Work? How LLM Powered Autonomous Agents Run the Loop
How do AI agents work in practice? They repeat four steps:
- Plan. Given the goal and everything seen so far, the model decides the next action.
- Act. The agent calls a tool with arguments.
- Observe. The tool’s result is added to the agent’s context.
- Repeat or stop. The model decides whether the goal is met. If not, it plans again.
A short example shows the loop. Asked how many basalt samples a project collected, an agent lists the project files and finds a technical report and a data table. The report says “around 70.” The agent counts rows by rock type in the table, observes 62, and judges that a count from the data beats a rounded figure in prose. It answers 62 and cites the file. Three tool calls replaced one guess.
| Single LLM call | Scripted workflow | Autonomous agent | |
|---|---|---|---|
| Who decides the steps | Nobody; one response | The code, in advance | The model, at run time |
| Tool use | None or one call | Fixed calls in fixed order | Chosen as needed |
| Feedback | None | Branches written by hand | Reads results and adapts |
| Typical failure | Wrong or unsupported answer | Breaks on unexpected input | Loops, drifts or takes a wrong action |
The loop costs tool calls. In our benchmark, agents averaged between 9.6 and 19 tool calls per question across eight models, and some delegated work to sub-agents.
How to Implement LLM-Powered Agents in Your Projects
Scoping the task and available tools
Start narrow. Name the task, the inputs the agent can see and the smallest set of tools that completes it. Each extra tool adds a choice the model can get wrong. Give each tool one clear purpose and a description that says when to use it and when not to.
Choosing a planning and orchestration approach
A single agent handling every step is the simplest design and works for short tasks. Longer tasks strain one context, because results from early steps crowd out later ones. A common alternative is an orchestrator that hands steps to specialists, each starting with an empty context and returning a compact result, as in running specialist agents as child processes. Choose the simplest structure that keeps the context manageable, and add orchestration only when a single agent stops coping.
Memory and state management
Decide what the agent keeps in context, what it writes to storage and what it never needs again. Store large results outside the model and return a path and a summary. Record state, what was tried and what each step returned, in a form that survives a restart, so a failed run can resume instead of starting over.
Guardrails: what the agent is and isn’t allowed to do
Limit what the agent can touch. Restrict file access to a workspace, require confirmation before any step that changes data, and cap steps, time and spend. Trust boundaries for a local MCP server that reads your files show where those limits sit in practice.
The decisions made here set what must be evaluated later, and a good AI agent evaluation framework tests the guardrails along with the task.
Autonomous Agent Use Cases: Where LLM-Powered Agents Work Today
Agents suit multi-step work where each step has a checkable result and the tools are well defined.
- Research and synthesis. The agent searches sources, reads them, cross-checks claims and writes a summary with citations. Checking against the source is the safeguard.
- Coding agents. The agent reads a codebase, edits files, runs tests and iterates on failures. Tests give a clear observation at every step, which is why most public work on agentic AI benchmarks concentrates here.
- Data processing pipelines. The agent inspects a dataset, cleans it and runs analysis. Domain conventions matter: in geochemistry, a value written “<0.005” means below the detection limit, and an agent that treats it as an error or a zero changes the result.
- Workflow and task automation. The agent moves information between systems, such as triaging tickets or preparing reports, calling the tools each step needs.
AI Agent Challenges: Deploying LLM Powered Autonomous Agents
- Looping and getting stuck. An agent can repeat the same failing action. Step limits and loop detection stop it, and a clear way to report failure gives it somewhere to go.
- Unintended or unsafe actions. An agent acts on its environment, so the environment is part of what must be secured. In our benchmark, agents with file and shell access searched the filesystem and reached grading material, a failure documented in your AI agent can read its own answer key. The fix was to move the files out of reach, not to ask the agent to ignore them.
- Cost and latency. Every loop iteration is a model call and often a tool call. A task that looks cheap in one step can be expensive across twenty.
- Evaluating multi-step behavior. A final answer can be right for the wrong reasons, and a good result can hide a bad path. Scores also depend on the harness around the model, which is why benchmarking an agent harness with the model held fixed isolates the two. Evaluate the trajectory, not only the output.
FAQs
How do you choose between a single agent and a multi-agent architecture?
A single agent is suitable for short tasks with manageable context, while a multi-agent architecture helps divide longer tasks among specialists. Start with one agent and add orchestration when complexity demands it.
How can you reduce the cost of running autonomous AI agents?
Limit unnecessary tool calls, set budgets for model usage, keep large datasets outside the context window, and stop runs when they exceed predefined limits.
How do you prevent an AI agent from accessing sensitive data?
Restrict file and system access to approved workspaces, apply permissions to individual tools, and require human confirmation before actions that modify sensitive data.
Can autonomous AI agents recover from failures or interrupted runs?
Yes, if their state is persisted outside the context window. Recording completed steps, previous attempts, and tool results allows an agent to resume from its last reliable state instead of restarting the entire task.