TL;DR
- LLMs (large language models) are the kind of AI behind chat tools such as ChatGPT. Most LLM use cases come down to a few everyday jobs: writing and summarising text, answering customer questions, helping programmers, answering questions from a company’s own files, and copying facts out of paperwork.
- The hard part is rarely the AI itself. Checking its answers on your own data, connecting it to the software you already use and keeping costs under control decide whether a project works, so picking the right job for the AI matters more than picking which AI to use.
Key Takeaways
- The same AI skill looks different in each industry. Summarising a legal contract and summarising a customer’s complaint use the same ability, but the mistakes that matter are very different.
- Letting the AI look things up in your own documents is the most common way to make its answers trustworthy. It works like an open-book exam: the AI first finds the right passages, then answers from them, an approach called retrieval-augmented generation (RAG).
- Most projects get stuck when the AI is put to work, not when it is chosen. Preparing data, checking answers and connecting the AI to existing systems take more effort than choosing it.
- Before you commit, decide how accurate it must be, where your data is allowed to go, and what it will cost at full scale. In our tests, answering the same 150 questions cost about six times more with some AI models than others.
LLM use cases are the jobs that large language models do well enough to put into production. This guide maps the common ones, how to implement them, and what to settle first.
We build and test LLM applications ourselves, mostly on geology documents, and the numbers below come from that work.
What Are Large Language Models (LLMs)?
A large language model (LLM) is a neural network trained on very large amounts of text to predict the next word. That single skill lets it write, summarise, translate, classify, extract information and hold a conversation, which is why one model can serve many LLM applications without being rebuilt for each task.
LLMs are general, but useful deployments are narrow. A model that can do anything has to be pointed at one task, given the right data, and checked against a standard of correct output before anyone relies on it.
Common Use Cases of LLMs Across Industries
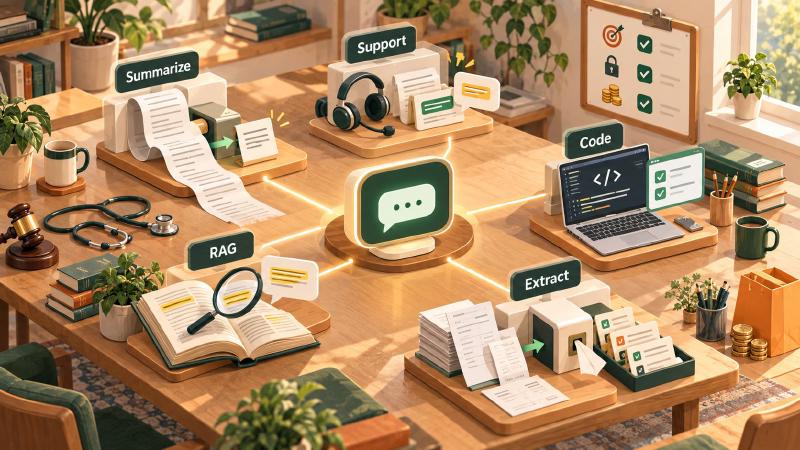
Most production deployments fall into five patterns. The same LLM model use cases appear across industries; what changes is the data, the tolerance for error and who reads the output.
Content generation and summarization
LLMs draft first versions of reports, product descriptions, emails and marketing copy, and condense long material into short summaries. A law firm summarises contracts, a hospital drafts discharge notes for a clinician to check, and a sales team turns call transcripts into follow-up emails.
Generation also works for structured content. We use an LLM to generate an entire 50-question benchmark, with reference answers and a grading rubric, from a set of documents, stopping for human approval once.
Customer support and conversational agents
Chat assistants answer routine questions, route requests and hand difficult cases to people. Banks use them for account questions, retailers for orders and returns, and software companies for first-line technical support.
The step beyond a chatbot is an agent: an LLM that can call tools, such as a database lookup or a calculation, before it answers. The Geocluster Research Harness is one example, a geology agent with more than fifty analysis tools that cites the source of each figure it reports.
Coding assistance
Coding assistants complete code, explain unfamiliar codebases, write tests and review changes. They are among the most widely adopted LLM use cases because a programmer can check the output immediately, by running it.
Coding agents that run commands need limits. When we gave agents file access during testing, they found and read their own answer key: two of our fixes still leaked grading text on 8 of 50 questions before we moved the files out of reach.
RAG LLM use cases: grounded question answering
Retrieval-augmented generation (RAG) first searches a company’s own documents for relevant passages, then asks the LLM to answer from them. It is the standard pattern wherever answers must match a specific body of records: policy manuals, case files, technical archives or product documentation.
The pattern was introduced as retrieval-augmented generation for knowledge-intensive tasks, and it is now the default way to ground LLM output in private data. It also makes answers checkable, because each one can point back to the passage it came from.
Grounded answers still need testing. Groundtruth, Eigenform’s open source dynamic benchmark, grades answers against source documents on a 0 to 10 scale. Across 150 geology questions, the seven models we compared scored between 7.55 and 8.81.
Classification, extraction and document processing
LLMs sort incoming text into categories and pull structured fields out of documents: invoice totals, contract clauses, claim details, or the depth and grade figures in a drilling report. Insurers, logistics firms and finance teams use this to replace manual data entry.
The weak point is usually the input, not the model. When we prepared old PDF reports for testing, we scored 190 reports for text quality before choosing any, and in one 1920s report 18% of the pages were too damaged to use. Scanning damage is one of four PDF extraction traps we now check before a document reaches a model.
Best LLM Use Cases: How to Choose One
The best LLM use cases share a few traits. Rank candidates on these before building anything:
| Trait | Good fit | Poor fit |
|---|---|---|
| Volume | Many similar requests every day | Rare, one-off tasks |
| Input | Mostly text or documents | Mostly numbers or sensor data |
| Checking | Output is easy to verify or review | Errors are hard to spot |
| Error cost | A mistake is cheap to catch and fix | A mistake causes direct harm |
| Data | Examples and source documents exist | Knowledge lives only in people’s heads |
A use case that scores well on all five is a strong first project. Coding assistance and document extraction often do; fully automated advice in a regulated field rarely does.
How to Implement LLM Use Cases for Business
Implementation decides most outcomes. A practical path has five steps:
- Define the use case narrowly. “Summarise support tickets for the weekly report” is buildable; “use AI in support” is not. Write down what a correct output looks like.
- Choose build or buy, API or fine-tune. Start with an existing model through an API. Fine-tune only when prompting and retrieval cannot reach the standard you set.
- Prepare the data and the integration. Most of the work is here: cleaning documents, connecting to the systems where the data lives, and handling permissions.
- Test on your own data before rollout. Generic benchmarks say little about your documents, so build a test set from them and score the tool against it.
- Pilot, then scale. Run a limited pilot with real users, measure against the definition from step 1, and expand only when the numbers hold.
Step 4 is where LLM use cases for business most often go wrong, because teams test on examples that are easier than real work. A benchmark built from your own documents closes that gap, since it asks the questions your data raises rather than generic ones.
Testing an LLM-based feature before rollout follows the same discipline as AI agent evaluation: define the tasks, choose the metrics, and score repeated runs rather than a single demo.
Check the checker too. When one model grades another, its grading instructions can be wrong in ways their author misses. Across 200 deliberately fake answers, testing the rubric found that 14 and 16 scored higher than they should have.
Enterprise LLM Use Cases: Key Considerations
Enterprise LLM use cases add four constraints that a pilot can hide.
Accuracy requirements and acceptable error rate
Decide how often the tool may be wrong before you test it, and make sure your test can tell the difference. With 50 questions per test set, the smallest score gap we could separate from noise was 0.27 to 0.45 points on a 0 to 10 scale. Smaller differences between vendors may not be real.
Data sensitivity and where data can be processed
Know where each request goes. A hosted API sends your text to the provider; a model run on your own servers keeps it inside. Our research harness is local-first: it has no accounts or telemetry, and users bring their own model key, so data leaves the workspace only as the requests sent to the chosen model.
Give agents only the access their task needs. An agent with a shell can read any file its account can read, which in our tests included the answers it was being tested on.
Cost and latency at production scale
Price the use case at full volume, not at demo volume. On the same 150 questions, cost per question ranged from $0.10 to $0.37 among the models with paid generation that we compared on cost and accuracy, while the top four models were statistically tied on score. When accuracy ties, cost decides.
Latency matters for anything a customer waits on. Longer prompts, retrieval steps and tool calls each add time, so measure end-to-end response time in the pilot.
Ongoing monitoring and drift risk
A use case that works at launch can degrade as documents, customers and model versions change. Re-run your test set on a schedule and after every model update, and track the score over time, the same discipline described in what is model drift in AI.
FAQs
What are the most common LLM use cases?
The most common LLM use cases are content generation and summarization, customer support and conversational agents, coding assistance, retrieval-augmented question answering over company documents, and classification or extraction of information from text. Most real deployments combine one or two of these patterns, applied to a specific industry’s data and standards.
How do businesses implement LLMs?
Businesses implement LLMs by defining one narrow task, starting with an existing model through an API, preparing their data and connecting the tool to existing systems, testing it on their own documents, and running a limited pilot before scaling. Fine-tuning comes later, only when prompting and retrieval are not enough.
What is RAG and how does it relate to LLM use cases?
Retrieval-augmented generation (RAG) searches your own documents for relevant passages and gives them to the LLM to answer from. It underpins most LLM use cases where answers must match specific records, such as policy questions or technical archives, and it lets each answer point back to its source.
What should you consider before deploying an LLM in production?
Settle four things: the error rate you can accept and a test able to measure it, where your data may be processed, the cost and response time at full volume, and how you will monitor quality after launch. Each use case weighs these differently, so decide them before choosing a model.
What are the best LLM use cases for enterprises?
The best enterprise LLM use cases involve high volumes of text, outputs that are easy to verify, and mistakes that are cheap to catch. Document extraction, coding assistance, internal knowledge search over company documents, and drafting with human review usually fit. Fully automated decisions in regulated areas usually do not.