TL;DR
- ML model serving exposes trained models through APIs for application use.
- Deployment places the model in an environment, while serving handles production requests reliably.
- Real-time and batch serving support different workloads, while model preparation improves performance.
- Monitoring, autoscaling, batching, and latency management ensure reliability at scale.
Key Takeaways
- Methods split into real-time and batch. Real-time serving optimizes latency per request; batch serving optimizes throughput over large volumes.
- Preparation shapes serving performance. Format conversion, quantization and packaging decide latency and memory use before any request arrives.
- Frameworks differ in what they optimize. Some favour raw throughput, others ease of integration or multi-framework support, so the right choice follows the workload.
- Reliability needs active tracking. Latency, error rate and resource use must be monitored and tested continuously, not only at launch.
Serving ML models is the step between a trained model and a working product. A model file on disk answers nothing; something has to receive requests, run the model and return the result fast enough, often enough and cheaply enough to be useful.
We do not run a serving platform at Eigenform. Our evidence comes from three places: a local tool server that agents call, benchmarking models served by providers where cost and latency vary, and local compute hardware for running models offline.
This article describes how serving works and where it goes wrong, with decision points and no framework-specific tutorial.
What Is ML Model Serving?
ML model serving is the layer that exposes a trained model so applications can call it, usually through an API. It receives requests, prepares inputs, runs inference and returns predictions, and it manages batching, latency and scaling so the model keeps answering reliably in production.
Training produces a file of learned parameters. Serving turns that file into a service with an address, a request format, a latency target and a capacity limit. Applications then depend on it the way they depend on a database, which is why its reliability matters as much as the model’s accuracy.
How Does ML Model Serving Work?
Serving ML models follows one request path, and each request passes through five stages:
- Client request. An application sends input to the serving endpoint, typically over HTTP or gRPC.
- Request handling. A gateway authenticates the request, validates it and often places it in a queue. The server may group several requests into a batch.
- Preprocessing and inference. Inputs are converted to the form the model expects, and the model runs on a CPU, GPU or other accelerator.
- Postprocessing. Raw model output is converted to the response format, such as labels, scores or text.
- Response. The result returns to the client, and the request is logged.
Latency enters at every stage. Network distance and serialization add to it, queues add waiting time, batching trades a short wait for better throughput, and model compute is usually the largest share. A cold start, when a new instance must load the model before answering, can dominate the first requests after a scale-up.
Payload size is easy to overlook.
In the local tool server behind our research harness, large results are written to disk, and the caller receives a path and a summary. Small responses are faster to serialize, send and read.
ML Model Serving vs Deployment: What Is the Difference?
Model serving vs deployment is a common point of confusion because the two are tightly linked. Deployment is the act of placing a model version into an environment. Serving is the runtime that handles requests against it.
| Deployment | Serving | |
|---|---|---|
| What it is | Placing a model version into an environment | Handling live requests against that model |
| When it happens | At release, once per version | Continuously, while the model is live |
| Main concern | Correct artifact, configuration, environment | Latency, throughput, availability, cost |
| Failure looks like | Wrong version or broken release | Slow, failing or overloaded responses |
In practice, the two overlap. Many tools deploy a model and start serving it in one step, and rollout strategies such as canary releases straddle both: deployment decides which version exists, and serving decides how much traffic it receives. A useful test is the time frame. If it happens once per release, it is deployment. If it happens on every request, it is serving.
Common ML Model Serving Methods
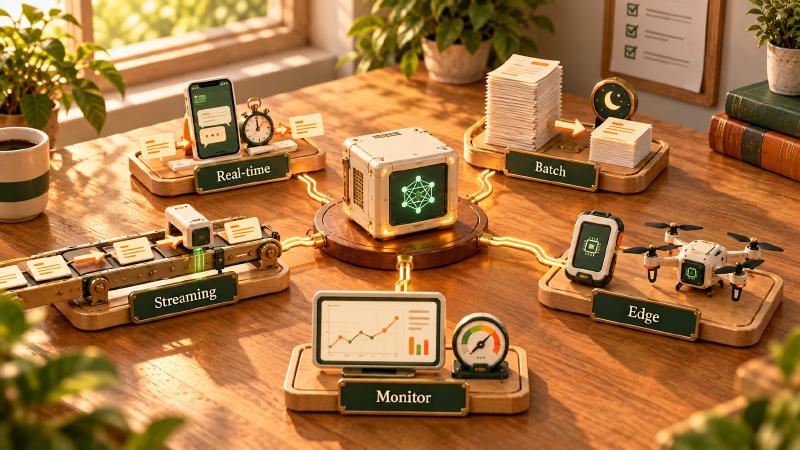
Serving ML models falls into four methods, which differ in how long a caller can wait and how much data arrives at once.
Real-time (online) serving
The caller sends a request and waits for the response, so latency is the main constraint. Teams track tail latency, such as the 95th or 99th percentile, because slow outliers are what users notice. Real-time serving needs capacity ready at all times, which makes it the most expensive method per prediction.
Batch serving
A scheduled job runs a model over a large dataset and stores the results for later use. Latency does not matter; throughput and cost do. Batch serving suits predictions that can be computed ahead of time, such as nightly scoring, and it allows full use of hardware.
Streaming inference
Streaming applies a model to a continuous flow of events as they arrive, often with state across a time window. The term is also used for streaming a model’s output as it is generated, as language models do token by token. The two are different: one is about inputs arriving continuously, the other about outputs leaving early.
Edge and on-device serving
The model runs on the device where data is produced, such as a phone or a field laptop. This removes the network, works offline and keeps data local, at the cost of tight memory and compute limits.
How to Prepare and Serve ML Models in Production
Searches for “how to serve ML model in production” usually mean four decisions, in this order.
1. Model packaging and format conversion
Package the model with everything it needs: weights, preprocessing code, dependencies and configuration, usually in a container image. Convert to a format the serving runtime reads efficiently, which may be a framework-native format or an interchange format such as ONNX.
The preprocessing must match training exactly. A mismatch between how data was prepared in training and in serving, known as training-serving skew, produces silent errors that no latency dashboard shows.
2. Optimization: quantization and compilation
Quantization stores parameters at lower precision, which cuts memory and often speeds up inference. The arithmetic is simple: memory for weights is roughly parameter count times bytes per parameter. A 7-billion-parameter model needs about 14 GB at 16-bit precision and about 3.5 GB at 4-bit, before runtime memory such as the cache a language model keeps for each request.
On local compute with 24 GB of GPU memory, like our prototype local AI compute, a 13-billion-parameter model at 16-bit (about 26 GB) does not fit, and at 4-bit (about 6.5 GB) it does. Compilation and graph optimization add further speed. After any of these changes, re-test accuracy on a held-out set, because lower precision can degrade quality unevenly.
3. Setting up the serving endpoint and request handling
Define the request and response schema, input validation, authentication, timeouts and rate limits. Set a maximum batch size and a maximum wait for batching, since these two numbers trade latency against throughput. Add health checks so a load balancer can remove a failing instance, and give every request an identifier so a slow or wrong response can be traced.
4. Versioning and rollback
Store each model version as an immutable, named artifact, and record which version served which request. Release new versions gradually, through a canary or shadow deployment, and keep the previous version available. Decide in advance what triggers a rollback, such as an error rate or a quality metric crossing a set threshold, so the decision is not made under pressure.
Common ML Model Serving Frameworks
A serving framework is the software that runs the model and handles requests. This overview is vendor-neutral and describes what such frameworks typically handle:
- Request batching. Grouping requests, either in fixed windows or continuously as sequences finish, to keep accelerators busy.
- Autoscaling. Adding and removing instances with load, sometimes down to zero when idle.
- Multi-model hosting. Serving several models, or several versions of one model, from the same infrastructure.
- Hardware acceleration. Running efficiently on GPUs and other accelerators.
- Interfaces and observability. Exposing standard APIs and emitting metrics, logs and health signals.
Frameworks differ in what they optimize for:
| Type | Optimizes for | Examples |
|---|---|---|
| Language-model engines | Throughput and memory use for text generation | vLLM |
| Multi-framework servers | Hosting models from different frameworks on one server | NVIDIA Triton Inference Server |
| Kubernetes-native platforms | Standardized deployment, autoscaling and scale-to-zero | KServe |
| Python-native libraries | Composing several models and custom logic | Ray Serve |
The examples are illustrative, and the field changes quickly, so check current capabilities before choosing. Match the framework to the workload: teams serving ML models for a single, heavily used language model and teams running a mixed fleet of small models need different tools.
Best Practices for Serving ML Models at Scale
Serving ML models at scale mostly means treating the service as software that can fail, with measurement at every step.
- Monitor the right signals. Track latency percentiles, error rate, throughput, queue depth and accelerator use, plus cost per request. Cost matters because models of similar measured quality can differ several-fold in price. The best AI model for your geology will cost more.
- Load test before scaling up. Use realistic payload sizes and request mixes, and find the point where latency degrades. A test with tiny inputs hides the limits that real traffic hits.
- Autoscale on the right signal. CPU use is a poor trigger for accelerator-bound work. Concurrency or queue depth usually reflects load more directly. Allow for cold-start time when setting scale-up thresholds.
- Version and roll back safely. Keep every version reproducible, release gradually and rehearse the rollback.
- Test continuously, not only at launch. Run a fixed evaluation set against the live service on a schedule, using an AI evaluation framework so results stay comparable over time. Treat a change as real only when it exceeds the test’s resolution: on our 50-question sets, the smallest gap we can detect is 0.27 to 0.45 points out of 10, as measuring the resolution of a 50-question benchmark explains.
- Watch inputs as well as outputs. Serving monitoring is where drift is usually first noticed, as input distributions shift or accuracy slips. Model drift in AI covers the types and how to detect them.
FAQs
What is ML model serving?
ML model serving is the layer that exposes a trained model so applications can call it, usually through an API. It receives requests, runs inference and returns predictions, while managing batching, latency and scaling. It is what keeps a model answering reliably once it is live in production.
What is the difference between model serving and model deployment?
Deployment places a model version into an environment, usually once per release. Serving is the ongoing runtime that handles requests against that model, with concerns such as latency, throughput and availability. In practice, the two overlap, since many tools deploy a model and begin serving it in one step.
How do you serve an ML model in production?
Package the model with its preprocessing and dependencies, convert it to an efficient format, and optimize it, for example by quantization. Then expose it through an endpoint with validation, timeouts and health checks, version every release, and add monitoring and a rollback plan before real traffic arrives.
What are common ML model serving frameworks?
Common options include vLLM for language models, NVIDIA Triton Inference Server for multi-framework hosting, KServe for Kubernetes-native serving, and Ray Serve for Python-based composition. They differ in what they optimize, such as throughput, framework support or autoscaling, so the right choice depends on the workload.
How do you serve ML models at scale?
Load test with realistic traffic, autoscale on concurrency or queue depth, and monitor latency percentiles, error rate and cost per request. Release versions gradually with a tested rollback, and keep evaluating the live service against a fixed test set so quality problems surface early.