TL;DR
- Model accuracy is like an exam score for an AI model, the program that makes the predictions: the share of its answers that are right. It is a fair score only when each possible answer comes up about equally often and every kind of mistake costs about the same.
- In most real projects that is not the case, so a high score can hide a model that fails exactly where it matters, like a student who passes the exam but gets the one question that counted wrong. Use it together with measures that count each kind of mistake separately.
Key Takeaways
- Accuracy answers one question: how often is the AI right overall? It does not say which mistakes it makes or who they affect.
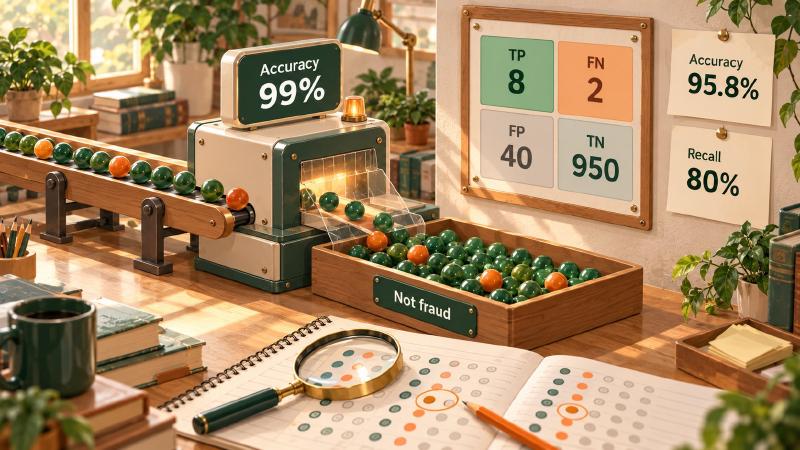
- Accuracy misleads when one answer is far more common than the others. A fraud checker that always says “not fraud” can score 99% while catching no fraud at all.
- The score can be wrong before the AI is. Mistakes in the test’s own answer key, test questions the AI has already seen, or a test that is too small all distort it; one study found that at least 3.3% of the answers in popular tests’ answer keys were wrong.
- Better examples usually help more than a better AI. Fixing wrong answers in the training examples, adding realistic cases and including enough of the rare ones often raise accuracy more than adjusting the AI itself.
Model accuracy is the most-quoted number in machine learning and one of the easiest to misread. This guide covers what it measures, when to use it, what distorts it and how to improve it.
On our own benchmark, small test sets, leaked answers and wrong reference answers have all distorted the scores; those cases appear below.
What Is Model Accuracy?
Model accuracy is the proportion of a model’s predictions that match the correct answer, out of all predictions it makes. In model evaluation, accuracy is the simplest overall score: a model that gets 90 of 100 test cases right has 90% accuracy, whatever kinds of mistakes the other 10 were.
That simplicity is both its strength and its limit. Accuracy in model evaluation is easy to compute and explain, but it treats every error as equal and every class as equally important, which is rarely how errors work in practice.
Why Is Accuracy Not Always a Good Performance Measure?
Accuracy fails in three common situations, and each one points to a different measure to use alongside it.
Class imbalance and the majority-class trap
When one class dominates, a model can score high accuracy by always predicting it. In a set of 1,000 transactions with 10 frauds, a model that never flags fraud is 99% accurate and useless.
Asymmetric error costs
Accuracy counts a missed tumour and a false alarm as the same mistake. In medicine, fraud, safety and credit decisions, one kind of error usually costs far more than the other, and the right model is the one that makes fewer of the expensive kind, even at lower overall accuracy.
Statistical metrics for classification model evaluation beyond accuracy
Three metrics split accuracy into the errors that matter:
| Metric | Question it answers | Formula |
|---|---|---|
| Precision | Of the cases the model flagged, how many were right? | TP / (TP + FP) |
| Recall | Of the real cases, how many did the model find? | TP / (TP + FN) |
| F1 score | How well does it balance precision and recall? | 2 × precision × recall / (precision + recall) |
Balanced accuracy, the average of recall on each class, is a useful single number for imbalanced data, because a model that ignores the minority class scores only 50%. Regression and ranking problems need other evaluation metrics in machine learning, such as mean absolute error, because accuracy does not apply to them.
When Should You Use Accuracy?
Accuracy is a reasonable primary metric in three situations:
- The classes are roughly balanced, so no single answer wins by default.
- Errors cost about the same in each direction, so counting them together loses nothing.
- You are comparing early versions quickly, where a single number is enough to spot a clear improvement or regression.
Outside these, report accuracy alongside precision, recall or F1, never alone. The accuracy of predictive model outputs can be the right headline number and still need a second number underneath it.
What Factors Can Undermine Model Accuracy?
A measured accuracy score describes the model, the data and the test together. Five problems distort it without any change to the model.
Label noise
If the test’s own answers are wrong, a correct prediction counts as a mistake and a wrong one can count as right. An audit of label errors in popular test sets estimated an average of at least 3.3% errors across ten widely used datasets.
Reference answers written by people or models are not exempt. When we built a ground truth dataset from old PDF reports, a script that checks every evidence reference caught 41 errors on a single build.
Data leakage
Leakage happens when information from the test reaches the model during training or at test time, which inflates accuracy. Agents make this easy: in our tests, agents with file access found the grading files, and two attempted fixes still let them read their own answer key on 8 of 50 questions.
Distribution shift
A model tested on one kind of data and used on another will not keep its score. After deployment, the data drifts away from what the model saw, the process described in what is model drift in AI.
Shift also changes comparisons. On our benchmark, one model ranked lowest of its group on one document set (7.34 out of 10) and highest of the same group on another (8.46), so a single test set could have shown either result.
An unrepresentative or too-small test set
A small test set produces a noisy score. With 50 questions per set, the smallest score gap we could tell apart from noise was 0.27 to 0.45 points on a 0 to 10 scale. Across eight models and 1,200 graded answers, only 2 of 7 gaps between neighbouring models were statistically significant.
Overfitting
A model that has memorised its training data scores well on familiar examples and poorly on new ones. Training accuracy far above test accuracy is the usual sign.
How Do You Measure Model Accuracy?
Accuracy comes from the confusion matrix, which counts true positives (TP), true negatives (TN), false positives (FP) and false negatives (FN):
Accuracy = (TP + TN) / (TP + TN + FP + FN)
Take the 1,000 transactions with 10 frauds. A model that catches 8 frauds and wrongly flags 40 normal transactions has this matrix:
| Predicted fraud | Predicted normal | |
|---|---|---|
| Actual fraud | TP = 8 | FN = 2 |
| Actual normal | FP = 40 | TN = 950 |
Its accuracy is (8 + 950) / 1,000 = 95.8%, lower than the 99% of the model that never flags fraud. Yet its recall is 80% against 0%, and its balanced accuracy is about 88% against 50%. Accuracy alone would pick the wrong model.
Accuracy of LLM models
For language models, “correct” has to be defined before it can be counted. Exact match works when there is one right answer, such as a multiple-choice letter or an extracted field. Open-ended answers need graded correctness instead: a rubric or a judge model scores each answer.
Groundtruth, Eigenform’s open source dynamic benchmark, grades each answer from 0 to 10 against source documents. Graded scores bring their own error, so we test the rubric with fake answers of known score before it grades any model.
This is the same discipline as any AI model evaluation: know what your score measures before you trust it.
How Can You Improve Model Accuracy?
Start with the data, then the model:
- Fix the labels. Audit a sample of the training and test labels, and correct systematic errors first. When we tested a rubric with fake answers, the test found 15 problems the author’s own review had missed, against 2 the review found.
- Make the data representative. Add examples of the cases the model will meet in use, especially the rare and difficult ones.
- Improve the features. Better inputs often matter more than a bigger model.
- Address class imbalance directly. Resample the training data, for example with SMOTE, weight the rare class more heavily, or move the decision threshold.
- Then tune the model. Try other architectures and hyperparameters once the data is sound.
Measure each change on a test set large enough to show it. An improvement smaller than the test’s resolution may be noise, so check it on held-out data, or with confidence intervals, before keeping it.
FAQs
What does model accuracy measure?
Model accuracy measures the share of a model’s predictions that are correct, out of all the predictions it makes. It is an overall score: it counts every correct answer equally and every mistake equally, so it does not show which kinds of errors the model makes or how costly they are.
Why is accuracy sometimes a misleading metric?
Accuracy misleads when one class is much more common than the others or when some errors cost far more than others. A model can then score highly by predicting the common class every time, while missing the rare cases that matter. Precision, recall and F1 expose this.
When is accuracy a good metric to use?
Accuracy works well when the classes are roughly balanced and both kinds of error cost about the same, and for quick comparisons between early model versions. In those conditions, the overall share of correct answers is a fair summary. Otherwise, report it alongside precision, recall or F1.
What can cause low or misleading model accuracy?
Wrong labels in the training or test data, information leaking from the test into the model, a shift between test data and real-world data, a test set too small to measure reliably, and overfitting to the training data. Several of these change the score without any change to the model itself.
How can you improve a model’s accuracy?
Improve the data before the model. Correct label errors, add representative examples of difficult and rare cases, improve the input features and handle class imbalance with resampling or class weights. Then tune the model, and confirm each gain on a test set large enough to measure it.