TL;DR
- When an AI grades two answers side by side and picks a winner, it tends to favour whichever one it happens to read first, regardless of which one is actually better. A single head-to-head verdict mixes answer quality with plain answer order.
- The fix: ask the same AI grader twice, swapping which answer goes first the second time, then convert both verdicts to one number and average them. An AI that just picks whatever’s shown first ends up with both answers tied, instead of one wrongly winning.
- We use this method in Groundtruth, our own benchmark for geological reasoning, for questions like “did this new version actually improve on the old one.” It doesn’t produce a single score you could rank on a leaderboard; that comes from a separate, simpler method that grades each answer on its own.
Key Takeaways
- A head-to-head verdict alone can’t separate quality from order. Swapping which answer is shown first, then averaging both verdicts, is the only way to know how much of a “winner” came from content rather than position.
- A judge that always picks whatever it sees first produces a tie, not a wrong winner. Averaging a run where it prefers first position with a swapped run where it also prefers first position cancels the effect out cleanly.
- This method answers “did this change help,” not “how good is this.” A head-to-head verdict is relative and can’t become a 0 to 10 score, so it can’t build a leaderboard column on its own.
- An unparseable verdict is recorded as unknown, not guessed. If either the normal or swapped run fails to produce a readable result, both responses are kept for inspection instead of trusting whichever one worked.
A single pairwise verdict mixes answer quality with answer order, so a judge’s pick can say more about position than about the answers. This post shows how we control position bias in pairwise LLM evaluation: ask the judge twice, swap the order, and average the two verdicts into one result.
What Is Pairwise LLM Evaluation and Position Bias?
Position bias is a judge’s tendency to favour an answer because of where it appears, not because it is better. Pairwise LLM evaluation gives an LLM-as-a-judge, one AI model grading another’s answers, two answers to the same prompt and asks which one is better. It is a natural fit for comparing a fine-tuned model with the base model it started from, and it is how Groundtruth Dynamic Benchmarking, our own benchmark for geological reasoning, was first used.
It carries a known weakness: LLM judge position bias. Given two answers of similar quality, a judge leans towards the one presented in a particular position, usually the first. If you ask once, you cannot tell how much of a verdict came from the answers and how much came from their order.
How Does Swapping the Order Control Position Bias?
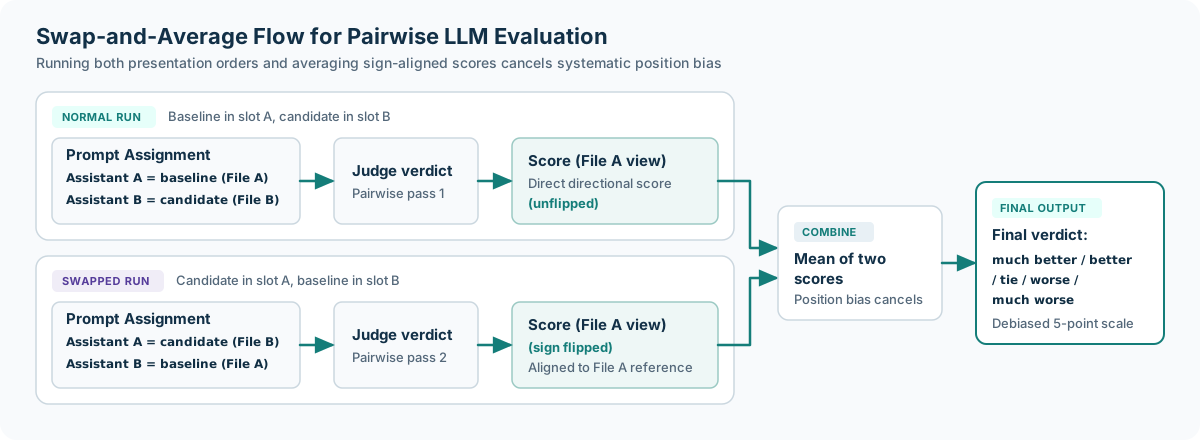
For every question, the harness sends the judge the same prompt twice. It’s the same swapped-order approach documented in Google’s agent evaluation metrics templates, which we used as a reference when designing our own.
- Normal run. The baseline answer (File A) is shown as Assistant A, and the candidate answer (File B) as Assistant B.
- Swapped run. The candidate answer is shown as Assistant A, and the baseline as Assistant B.
In both runs the judge writes a short evaluation and ends with one of five tokens: [[A>>B]], [[A>B]], [[A=B]], [[B>A]] or [[B>>A]].
How Do You Turn Two Verdicts Into One Number?
The two verdicts cannot be averaged as written, because “A” means a different file in each run. So each is converted to a number from the point of view of File A:
| Verdict token | Value in normal run | Value in swapped run |
|---|---|---|
A>>B | +2 | -2 |
A>B | +1 | -1 |
A=B | 0 | 0 |
B>A | -1 | +1 |
B>>A | -2 | +2 |
The final score is the mean of the two values, and it maps back to a verdict:
| Mean | Final verdict |
|---|---|
| 1.5 or more | File A much better |
| 0.5 to under 1.5 | File A better |
| above -0.5 and below 0.5 | Tie |
| above -1.5 and up to -0.5 | File B better |
| -1.5 or less | File B much better |
What Do Worked Examples of Swapped Verdicts Look Like?
| Normal run | Swapped run | Values | Mean | Final verdict |
|---|---|---|---|---|
A>B | B>A | +1, +1 | 1.0 | File A better |
A>>B | B>>A | +2, +2 | 2.0 | File A much better |
A>B | A>B | +1, -1 | 0.0 | Tie |
A>>B | A>B | +2, -1 | 0.5 | File A better |
B>A | A>>B | -1, -2 | -1.5 | File B much better |
The first two rows are consistent judgements: the judge preferred the same file whichever position it appeared in, so the verdict stands, once moderately and once strongly. The third row is position bias in its purest form: the judge preferred whatever it saw first, both times, and the two preferences cancel into a tie. The fourth row is a mixed case: the judge favoured File A strongly in one order and weakly preferred File B in the other, and the average keeps a weak preference for File A. The fifth row is another consistent judgement, this time for File B: a moderate preference in the normal run and a strong one in the swapped run average out to a clear win for File B.
If either run fails to produce a readable verdict token, the harness records the verdict as unknown and keeps both judge responses for inspection, instead of trusting the run that did parse.
How Do You Analyze Pairwise Evaluation Results?
Tally the final verdicts across questions, then report wins, ties and losses as rates, not one headline number. These are general practices for reading the output, not Eigenform findings.
Tally the verdicts
Count how many questions favour each file. The table is an illustrative example, not real data.
| Final verdict | Questions (example) |
|---|---|
| File B much better | 4 |
| File B better | 8 |
| Tie | 6 |
| File A better | 2 |
Read ties and the position bias share
A tie can mean equal quality or a judge driven by position, so check the two raw verdicts behind each tie. Also measure the share of questions where the two verdicts disagree; it shows how much order affected the judge.
Treat small gaps with caution
With few questions, a lead may be noise. Check the minimum detectable gap first.
Inspect unknown verdicts
Review the unknowns logged by an LLM judge that cannot invent a score and read saved responses for surprises. Where results differ from pointwise scores, see pairwise vs pointwise evaluation below, or how to benchmark AI models.
What Does Swapping the Order Cost?
Two judge calls per question instead of one. Groundtruth’s scoring mode, set as a flag, lets you choose what to pay for when comparing two answer files: the pairwise verdict alone at two calls per question, the pointwise 0 to 10 score for both files at two calls, or both together at four.
What Can a Pairwise Verdict Not Tell You?
A verdict is relative. “File B much better” on a question says nothing about whether either answer was any good, and swapping in a different baseline can change every verdict. You cannot rank more than two models from pairwise LLM comparison without running every pair, and you cannot turn them into a 0 to 10 score. That is why the Groundtruth leaderboard is built only from pointwise scores, where each answer is graded against its rubric on its own.
Why Can Pairwise and Pointwise Verdicts Disagree?
Pairwise and pointwise scores can also disagree for a structural reason. Groundtruth’s pairwise prompt asks the judge to compare both answers against the reference answer and the underlying principle, while the pointwise prompt applies the full gate and component scheme. An answer that loses a head-to-head comparison on overall quality can still pass a gate the other answer failed.
We run pairwise when the question is “did this change help”, and pointwise when the question is “how good is this”. The comparison code, compare_answers() in main.py, is in the Groundtruth Dynamic Benchmarking repository.
Frequently Asked Questions
How do you detect position bias in an LLM judge?
Run each comparison twice, once normally and once with the answers swapped, then compare the two verdicts. A judge that picks the same position both times is driven by order, not content. A judge whose verdicts flip with the order is reacting to position. Measure how often this happens across questions using the analysis steps above.
Does swapping the answer order eliminate position bias?
No. Swapping cancels a consistent order preference into a tie, but it does not fix other judge biases such as verbosity or self-preference, so a swapped tie does not prove the judge is otherwise fair. For those, see the LLM judge bias overview in our LLM-as-a-judge guide.
Is two swapped judge calls enough to trust a verdict?
Two calls cancel a consistent order effect, but one set of verdicts on a few questions is still noisy. Base conclusions on results across many questions, and check whether the gap exceeds what the benchmark’s resolution can detect. Swapping removes a consistent order preference, not noise from a small question set.
What does a tie mean in pairwise LLM evaluation?
A tie can mean the two answers are equally good, or that the judge preferred whichever position it saw first in both runs and the preferences cancelled. Check the two underlying verdicts behind each tie before treating it as equal quality. A high share of ties alongside disagreeing raw verdicts points to position, not parity.
How many comparisons do you need to rank several models?
Every pair has to be run, which means n(n-1)/2 comparisons for n models. Each comparison costs two judge calls, so four models need six comparisons and twelve calls. Cost grows quickly as models are added, which is why leaderboards use pointwise scores instead. Plan the comparison count before choosing how many models to include.