TL;DR
- In the Geocluster Research Harness, an orchestrator agent hands each analysis step to a specialist that runs as a separate command-line process with an empty context. The specialist does its work and returns one compact JSON result.
- Getting that to work reliably took several details. Credentials stay out of the logged command, and dataset columns attach to the task automatically. Timeouts come from the process state rather than output text, and the HTTP connection resets after long waits.
- Results are size-capped, with the full version saved to disk, and the cost of every child run is added to the task’s total.
Key Takeaways
- Two different tools handle two different handoffs.
activate_specialistswitches the system prompt within the same conversation and process;dispatch_specialiststarts a real child process, and only the orchestrator can call it. - A dispatch is a genuine CLI child process with its own environment. Credentials go to a mode-600
secrets.json, not into the command string. That string is logged and visible in the chat transcript. - Timeouts are detected from process state, not from matching text. An earlier version watched for the string “Command timed out” in the output. That string also appears, and produces a false timeout, when a script inside the child times out while the child itself finishes normally.
- Results are capped at 8,000 characters with the full version saved to disk, and every dispatch’s cost rolls into the task’s total. The orchestrator keeps a running history of the last 20 dispatches, so context stays small without losing the record of what already ran.
This post explains the multi-agent orchestration behind the Geocluster Research Harness. It covers why each specialist runs as its own child process, and what it took to make that reliable.
Why one conversation is not enough
A geological analysis runs in steps: load, check quality, clean, transform, cluster, plot, verify. Run all of it in one agent conversation and the context fills with column statistics, previews and script logs long before the analysis is done.
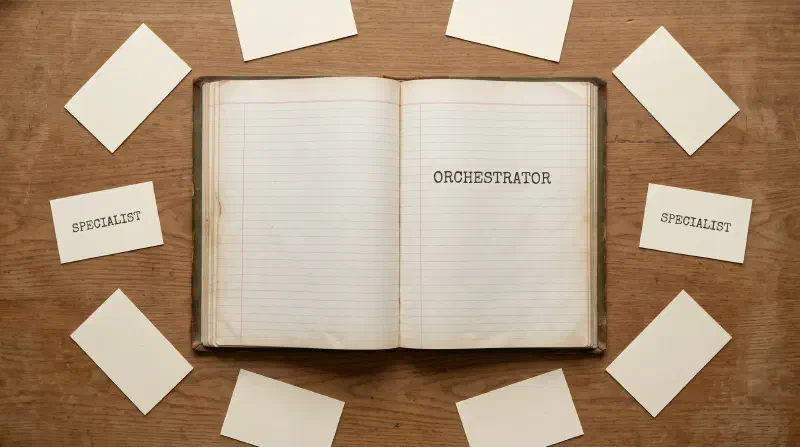
The Geocluster Research Harness runs on multi-agent orchestration. In the harness’s layered agent design, the agent the user talks to delegates to an orchestrator. The orchestrator hands each step to a specialist for data operations, transforms, analytics or visualisation. This post is about the mechanism underneath: running each specialist as a child process.
Two ways to hand over work
The harness uses two tools for delegation, and they work differently.
activate_specialist switches the system prompt within the current conversation. The user-facing agent calls it to hand over to the orchestrator, and the orchestrator calls it again to hand back with a summary. No new process starts and the agent makes no extra model request; the next turn simply uses a different prompt. The orchestrator stays in the same conversation on purpose, because tracking hypotheses across steps means seeing what the user asked and everything each specialist returned.
dispatch_specialist starts a new process. It is the only way to run a specialist, and only the orchestrator has it.
What a dispatch runs
The agent is a fork of the Cline coding agent, which ships a command-line version. A dispatch runs that CLI as a child process:
CLINE_SPECIALIST=dataops \
CLINE_DATA_DIR=<extension storage folder> \
CLINE_PARENT_MODEL_ID=<model the user selected> \
CLINE_PARENT_PROVIDER=<provider the user selected> \
cline '<task for the specialist>' --json -yCLINE_SPECIALISTtells the child which specialist prompt and tool set to load.- The two
CLINE_PARENT_*values make the child use the same model and provider the user picked. --jsonprints every message as one JSON line on standard output, which the parent reads.-yauto-approves actions, since nobody is watching the child to click Approve.
The child starts with nothing but its task. It connects to the same local tool server as the parent, an MCP server built on the lessons in MCP tool design. It does its work and must finish by returning a structured result. That result holds a status, a small results object, evidence for or against the current hypothesis, recommendations and errors.
Making multi-agent orchestration reliable
Running specialists as separate processes solves the context problem, but it raises new ones. Each of the fixes below came from something that broke.
Credentials without a logged command
The user types their API key into the editor, which stores it in VS Code’s secret storage. A child process cannot read that storage.
Before every dispatch, the parent copies the key for the active provider into a secrets.json file inside the extension’s storage folder. It sets the file permissions to owner-only (mode 600), and only writes when the value has changed. The child reads its secrets from that folder.
The key never goes into the command string. The extension log records that string and the chat transcript shows it, so anything placed in it should be assumed public.
Giving the specialist the columns up front
Many dispatches concern one table, and a specialist that must first discover the column names spends a turn doing it. When the orchestrator passes a dataset_path, the parent reads the first 4 KB of the file. It skips the file if it contains null bytes (a sign of binary data), and detects whether it is comma, tab or semicolon delimited. Then it appends the column list and an estimated row count to the task:
Dataset columns (auto-detected from /workspace/default/data/meridian_ridge_geochem.csv):
Columns (12): SAMPLE_ID, EASTING, NORTHING, DEPTH_M, LITHOLOGY, Au_ppm, Cu_ppm, Pb_ppm, Zn_ppm, As_ppm, Fe_pct, SiO2_pct
Estimated rows: ~240
The path must resolve inside the working folder; the parent refuses and logs anything outside it. This matters most for the data-operations specialist, whose geochemistry data cleaning tools start from exactly those column names.
Timeouts from process state, not from text
Each dispatch has 600 seconds. An earlier version decided a dispatch had timed out by looking for the text “Command timed out” in the child’s output. That text also appears when a script inside the child times out while the child itself finishes normally, which produced false timeouts.
The dispatch now relies on a flag from the process runner that says whether the child completed or was killed. A killed child becomes an error result with a message suggesting the objective be split into smaller tasks. The orchestrator’s instructions reinforce the limit: at most one or two plots per visualisation dispatch.
Reset the connection after a long wait
A dispatch can keep the parent waiting for up to ten minutes. In that time the provider may close the keep-alive socket the parent holds, and the next request then fails with a socket error. The parent resets its HTTP client after every dispatch, including when the dispatch throws.
Recovering a structured result
Models do not always return exactly what they were asked for. The parent reads the child’s output stream from the end, looking for the final completion message. It then tries to recover a structured result, either by parsing it directly as JSON or by extracting JSON embedded in prose. When a child never produced a completion message at all, the orchestrator receives an error carrying the readable tail of the output. It can then decide whether to retry or report the failure.
The parent returns error results to the orchestrator as tool errors instead of ordinary results. That gives the model a structural signal that the step failed, which is harder to talk past than a sentence in the middle of a JSON object.
Cap the result, keep the rest on disk
Specialists are told to keep results under about 2,000 characters and to write data to files, reporting only paths. As a backstop, the parent caps results at 8,000 characters. It saves anything larger in full to a temporary file and replaces the oversized entries with a note of their length. A notice with the file path tells the orchestrator where the rest is.
The orchestrator also gets a running history of dispatches in its prompt: the last 20 with their objective, status and duration, and a one-line count of anything older. When the conversation is compacted, the record of what has already run survives.
Cost and status in the chat
While a child runs, the chat shows a card with the specialist’s name and a running status. The parent reads token counts and cost from the child’s own request messages in the JSON stream and collects which tools the child called. When the child finishes, the card updates with status, duration, tokens and cost. That cost joins the task’s total alongside the parent’s own requests, so the figure at the top of the task reflects the whole analysis.
When a specialist needs a package
Sometimes a specialist needs a Python package that is not installed. The instructions forbid specialists from installing anything themselves. Instead, they call request_capability with the package name, reason and a fallback. The handler then requires their completion to relay that request as a structured “capability gap” result, and rejects any other completion until they do.
The orchestrator then dispatches the extended agent, the one layer meant to install packages. Its instructions are to install with version constraints and confirm the package imports before reporting success. The orchestrator dispatches the original specialist again with "resume": true in its context, in a fresh process, and it continues from where it stopped.
What this buys
Each step gets a clean context sized to its task. Failures stay contained in one process. The orchestrator reasons over short structured results instead of raw output. And every step leaves a visible trace of what ran, what it cost and what it returned. Those are the same properties that keep a pipeline from turning into a slop cannon: small tasks, checked results, and failures that show.
The dispatch handler is agent/src/core/task/tools/handlers/DispatchSpecialistHandler.ts in the Geocluster Research Harness repository.