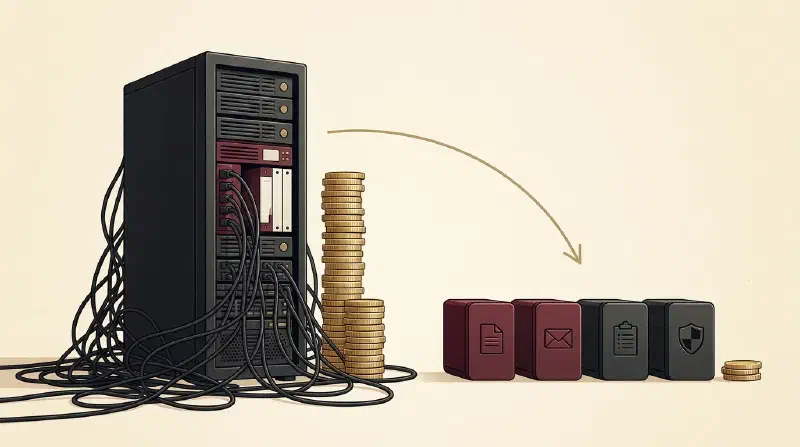
TL;DR: Small language models are compact AI programs trained to do one job fast and cheaply, and more businesses and public agencies are moving simple, repetitive tasks to them. Gartner predicts they will see at least three times more use than general-purpose models by 2027, and Airbnb and Docusign cut per-request AI costs by 95% to 99% in two published cases. Large general-purpose models still win when request volume is low, rules change weekly, or the work is open-ended.
Many companies start by sending every AI task to a large, general-purpose “frontier” model, the most capable kind available. That works for prototypes. It gets slow and expensive when one workflow runs thousands of times per minute.
Small language models (SLMs) are gaining ground in analyst forecasts and company reports. Gartner predicts that by 2027, organizations will use small, task-specific models at least three times more than general-purpose ones. Airbnb and Docusign report cost cuts of 95% to 99% per request on narrow tasks. US agencies such as the Department of Veterans Affairs run most of their AI processes on open-weight models. That is why more businesses and public agencies are turning to SLMs for high-volume jobs, a move that fits wider AI business integration plans.
What Are Small Language Models?
Small language models (SLMs) are compact AI models with fewer parameters, the internal numeric weights a model adjusts during training. Instead of answering open-ended questions on every topic, they run narrow, repeatable tasks quickly and cheaply on modest hardware after fine-tuning or model distillation.
A June 2025 NVIDIA agentic AI paper argues that SLMs fit software agents well. Most automated workflows repeat a short list of specialized steps. In daily business operations, SLMs suit four kinds of narrow work:
- Screening user content against a fixed policy rulebook.
- Extracting fields like dates, prices, and party names from standard forms or contracts.
- Classifying incoming emails, tickets, or government records into routing queues.
- Summarizing routine documents that follow a predictable template.
Why Businesses Move Routine Work to Small Language Models
Teams adopt small language models for two practical reasons. Narrow tasks do not need general reasoning, and large models cost too much at high volume.
Market Forecasts and Agentic Workloads
In April 2025, Gartner predicted a shift in usage. By 2027, organizations will run small, task-specific AI models at least three times more than general-purpose large language models, measured by usage volume. Gartner ties this to the variety of business workflows and the need for higher accuracy.
Gartner analyst Sumit Agarwal said smaller models fine-tuned on domain data respond faster and use less computing power. That lowers ongoing operating and maintenance costs.
NVIDIA researchers Belcak et al. make a similar argument for multi-step AI agents. An agent calls a language model many times to finish one job. Using SLMs for repetitive sub-tasks lowers the cost per run. Their paper is a position paper, not a production benchmark, so pair its argument with real deployment numbers.
Lower Inference Cost and Faster Response Time
Two metrics drive the move away from frontier APIs on routine work. Latency is the delay between sending a request to a model and getting its answer, measured in milliseconds (ms). Requests per minute (RPM) counts how many calls a system handles every 60 seconds.
When a product checks every user action in real time, a 900 ms wait slows the experience. Airbnb’s classifier, described below, had a 200 ms budget. A compact model on your own graphics processing unit (GPU) can meet that budget. At sustained high traffic it also lowers LLM infrastructure costs.
Fine-Tuning vs LLM Distillation: Two Ways to Specialize a Model
An off-the-shelf small model rarely matches a frontier model on a company’s custom rules. Teams specialize it through direct fine-tuning or LLM distillation.
How Fine-Tuning Works on Domain Data
Fine-tuning updates the weights of an existing base model. It uses thousands of labeled input-and-output examples from your task. Fine-tuning LLM workflows work best when you already collect verified historical decisions, such as moderation logs or human-reviewed forms.
How Model Distillation Transfers Knowledge
Model distillation, also called knowledge distillation, trains a compact student model to reproduce the outputs of a larger teacher model. Geoffrey Hinton, Oriol Vinyals, and Jeff Dean introduced the method in their 2015 knowledge distillation paper. It compresses a large model or ensemble into one model that is easier to deploy.
In modern business pipelines, a frontier reasoning model acts as the teacher and labels raw documents. Those machine-made answers are called pseudo-labels, a form of synthetic training data. They train the smaller student model.
| Approach | What you need | Where the training labels come from | Example in this post |
|---|---|---|---|
| Fine-tuning | A base model and a large set of verified historical examples | Human annotators or logged operational records | Airbnb fine-tuning Gemma 4 E2B on hundreds of thousands of policy examples |
| Model distillation (knowledge distillation) | A strong teacher prompt, unlabeled domain documents, and a smaller student model | Pseudo-labels generated by a frontier teacher model guided by expert rules | Docusign distilling a frontier reasoning teacher into a smaller contract extraction model |
Production Case Studies of Specialized Models
The reports below show how production teams and government agencies use specialized models, and where each result stops.
Airbnb: Fine-Tuning Gemma 4 E2B for Policy Screening
In a recent Airbnb classifier benchmark, engineers tested models that screen text for violations of Airbnb’s pricing and payment transparency policy. The classifier runs thousands of times per minute. It must return a numeric score within 200 ms.
Airbnb fine-tuned a Gemma 4 E2B model on hundreds of thousands of de-identified domain examples. They came from users who had not opted out of AI training. The team measured accuracy with the F1 score, a single metric from 0 to 1. It balances catching real violations against avoiding false alarms.
Fine-tuning raised the model’s F1 score from 0.563 to 0.902, on par with the best proprietary models tested. Median latency was 35 ms, and 99th-percentile (p99) latency was about 85 ms. The frontier models tested had a median latency near 900 ms. Their p99 was multiple seconds, even in low-thinking mode.
At thousands of requests per minute, frontier APIs cost two orders of magnitude more than one self-hosted GPU. That gap is behind Airbnb’s headline figure of about 1% of the cost. A detailed 2,700-word prompt also did not close the accuracy gap for fast models that were not fine-tuned. Airbnb describes this as fine-tuning, not distillation. The result comes from one task at one company.
Docusign: Model Distillation for Contract Extraction
In a September 2026 Docusign extraction study, the AI team described extracting more than 50 data types from over 1 million documents per day. Docusign used teacher-student distillation. Legal experts wrote extraction guidelines for a frontier reasoning teacher model. The teacher generated pseudo-labels on anonymized documents, and those labels fine-tuned a smaller student model.
Docusign does not publish the student’s size. We call it a smaller model, not an SLM of known parameter count. The student learns from the teacher’s labels, so the quality of the teacher’s prompt sets the accuracy ceiling.
Compared with the teacher, the student trails by about 1 percentage point of F1. It runs at roughly a hundredth of the teacher’s cost and a quarter of its latency. Against the non-fine-tuned frontier model it replaced in production, the seventh-generation student costs roughly a twentieth as much. It reaches about eight times the throughput, cuts inference time roughly in half, and improves accuracy by 7 percentage points.
US Public Sector: Hybrid Routing and the Open-Weight Caveat
A November 2026 TechTarget government AI report covered the October 2026 Red Hat Government Symposium. It described a hybrid pattern in US agencies. Speakers used frontier models for complex analysis. They used smaller, cheaper models for routine summarization, record extraction, and correspondence classification.
A common way to build this split is AI routing. It sends simple requests to compact models and hard cases to frontier models.
At the symposium, Lance Jenkinson, CIO and deputy assistant inspector general at the US Department of Veterans Affairs, gave a figure. About 85% of the agency’s roughly 300 AI-driven processes use open-weight models. Answers are “just as accurate, more often than not,” he said, at a far lower cost.
One caveat applies. Open-weight means the trained model weights can be downloaded and hosted on your own servers, as with the Llama, Qwen, and DeepSeek families. Open-weight models are not necessarily small. This single report is evidence for self-hosting and cost-aware routing, not proof that agencies run small language models.
NTU Research on Knowledge Distillation for Portable Devices
Distillation also helps outside text processing when computing power is scarce. A November 2023 NTU skin diagnostic feature profiled university research led by Professor Miao Chun Yan at Nanyang Technological University (NTU) in Singapore.
The team used Self-Supervised Diverse Knowledge Distillation. It lets a skin-disease classifier run on portable devices in low-resource settings, where high accuracy often needs heavy computing. Tested on over 25,000 images, the system classified eight skin diseases with 85% accuracy.
This is image classification research, not a hospital rollout or a language model. It makes no claim about savings. It still shows why distillation matters when a model must fit onto small, low-cost hardware.
When Small Language Models Do Not Pay Off
Specialized small language models are the wrong tool when traffic is low or task rules shift often. An October 2026 deepset comparison guide says a large model fits open-ended, rare, or low-volume steps better.
As deepset puts it, “if a step runs only a few dozen times a day, a frontier model may well be cheaper overall.”
Headline savings like Airbnb’s 1% figure or Docusign’s hundredth-of-the-teacher ratio describe ongoing inference bills. They leave out upfront model training costs and engineering time. Docusign’s ratio, for example, does not cover the compute used to run the teacher that labeled the data.
Read the trend evidence with the same care. Gartner’s figure is a forecast, and Airbnb and Docusign are single-company results rather than an industry-wide survey. The Veterans Affairs figure counts open-weight models, which are not always small.
Use a frontier model behind a clear prompt in these situations:
- Request volume is below break-even: In Airbnb’s benchmark, frontier APIs were cheaper than a dedicated GPU below roughly 15 to 30 requests per minute.
- Rules change from week to week: Updating a prompt is quick. Re-labeling data and retraining a model takes much longer.
- The task is broad or open-ended: Complex multi-step reasoning and rare edge cases still benefit from frontier scale.
- You lack labeled data or ML staff: Without training pipelines or experts to write teacher guidelines, setup costs can outweigh inference savings.
Could Your Business Save Thousands With a Custom Local Model?
If your business is using a frontier model for simple, repetitive tasks you could be losing money on every request. We can build a custom model for your workload that you pay for once, instead of per token, potentially saving thousands of dollars per year.
If you are interested in a custom model for your business, contact us here.
FAQs
What is SLM in AI?
SLM stands for small language model. It is a compact neural network that processes text with far fewer parameters than general-purpose frontier systems. Organizations run SLMs on single GPUs, edge servers, or mobile devices. They handle narrow tasks like classification and data extraction with fast responses and lower computing bills.
What is the difference between fine-tuning and distillation?
Fine-tuning trains a base model on existing human-labeled or historical business records. Distillation uses a large teacher model to generate training labels for a smaller student model. Choose fine-tuning when you already own verified labels. Use distillation when you have unlabeled documents that need automated scoring first.
At what request volume does a self-hosted small model beat an API?
In Airbnb’s production benchmark, a self-hosted GPU running a fine-tuned Gemma 4 E2B model became cheaper than frontier APIs above roughly 15 to 30 requests per minute. Below that level, or when a workflow runs only a few dozen times per day, pay-per-call frontier APIs cost less than dedicated hardware.
Can small language models match frontier model accuracy?
Yes, specialized small models can match or beat non-fine-tuned frontier models on narrow, well-defined tasks. Airbnb’s fine-tuned model, with about 2 billion effective parameters, reached a 0.902 F1 score on policy screening, on par with top proprietary models. At Docusign, a distilled student beat the previous production frontier model by 7 percentage points.
When should a business keep using a frontier model?
Keep a frontier model when tasks are open-ended, rare, low-volume, or changing from week to week. Below 15 to 30 calls per minute, a frontier API behind a clear prompt costs less than dedicated GPU hardware. It also avoids the upfront work of labeling data and maintaining training pipelines.
Are open-weight models the same as small language models?
No. Open-weight means the trained model weights are available to download and run on your own servers. Small refers to parameter count. The two properties are independent. Open-weight families such as Llama, Qwen, and DeepSeek include compact models and models with hundreds of billions of parameters.