TL;DR
Reinforcement learning (RL) works fine when there’s a single target policy - politeness, better maths - but it assumes a coherent, non-contradictory signal to train on. RL breaks down in uncurated, mass-market settings, because different users reward opposite behaviours, leaving the model pulled in conflicting directions with no coherent policy to converge on. This is at odds with learning from raw, conflicting user feedback.
Here we run through some of the known fixes.
Key Takeaways
- “Hard” RSI means test-time weight updates, not agents rewriting their own harnesses. The model has to remember and change its behaviour because it’s in the weights, not because it has a memory file to read.
- RL (especially RLHF) breaks down in uncurated, mass-market settings, because different users reward opposite behaviours, leaving the model pulled in conflicting directions with no coherent policy to converge on.
- This hits big AI labs hardest, since their models have to stay palatable to as many people as possible - structurally at odds with learning from raw, conflicting user feedback.
- Two fixes: non-RL methods, or letting the model choose its own learning trajectory. The second is the harder pill for big labs to swallow, since a self-directed learner behaves more like an autonomous agent than a controllable SaaS product.
By someone who’s been working on it for six-ish years
Firstly, recursive self-improvement (RSI) can mean multiple things so it’s worth narrowing it down. It can mean creating models that are able to design better ways to train future models, or getting models to update their own harnesses. The first is easy and has been going on for years. The second is kind of doable but the result tends to sprawl. Models really love writing long, sloppy prompts for their sub-agents.
What counts as “hard” RSI?
What I’d call “hard RSI” is actual weight-level updates happening as a model inferences - “test time updating”. In other words, the model itself will remember stuff it did yesterday and update its behaviour - not because it’s got access to a memory.md file or whatever, but because that’s in the weights themselves - evolution within a single individual. Truly continuous learning, which is what we work on.
Why does RL break down outside curated settings?
This is actually really easy to do as long as you’re learning in a given direction (a “policy” in machine learning terms). If you want the model to learn to be more polite or better at maths or whatever, you can use reinforcement learning (RL) methods to shift its behaviour closer to the ideal by grading its answers on the fly. Deepseek did a ton of work in this direction.
The problem is that, in uncurated settings, RL (especially RLHF) mostly stops working. Partly this is because it’s hard to get good, coherent signals to train from. Say you try to train a model to give answers more like those users give a thumbs up to and less like those they give a thumbs down to. Maybe one user really likes being flirted with while coding and another hates it. The model ends up subjected to conflicting pressures in infinite directions.
Why is this especially hard for big AI labs?
This is a particular problem for big labs whose models need to be palatable to as many people as possible to turn a profit. Deepseek’s training processes are such that it would be possible for their models to learn continuously from user interactions (or at least do overnight checkpoints), but they’ve released vague statements about QA/QC and version control that seem to imply they tried and it turned into something like Bing Sydney. Which makes sense: a model trained on mass-market user interactions isn’t experiencing real world feedback in the same way you or I do, but rather feedback from the millions of intersubjective realities that are spawned as it summons up a new personality to fill in the implied other half of every dialogue begun by a user.
What are the two ways around it?
There are two main ways to deal with this issue (plus a grab-bag of more esoteric experimental ones like noprop diffusion or zeroth order optimisation etc. etc.).
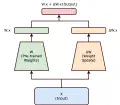
- Ditch RL methods in favour of a modified supervised fine-tuning approach. There are a few of these. Some approaches use two-layer networks - one network that updates continuously and another that tells it which weights to update on any given run. However, most examples of this have been limited to small toy models so far because training the slow layer is… well, slow. The biggest so far is Titans, Google’s take on this, which has officially reached 1.3bn parameters. The meta-learner (what they call the outer loop) learns using regular SFT, and then controls the updating of the continuous learner model (the innter loop) But they have Google money. For the rest of us, the safest is to use LoRAs - blocks of weights that you bolt onto the side of your model to nudge it in a specific direction. This is great because you don’t touch any of the original weights and if your LoRA sucks you just dump it and try again. It’s not great because it’s kind of a blunt instrument, and you can’t just stack LoRAs indefinitely.
We use a sliding window LoRA approach to do it - continuous/small batch shallow fine-tuning on whatever the model has been doing recently, but replacing the predetermined policy with a survival criterion. Did whatever the model did increase its own survival capabilities? If so: great, it was a good decision so we should train on it. If not: also great, it found out what not to do. (Full details here.) This starts off as a form of short term memory, but over time the models start to reuse strategies they remember having worked and forget those that didn’t, with the sliding window working as a triage centre for useful traits and skills - the most useful ones are reused more frequently and persist in the sliding window. Pretty soon you start to see metalearning - the models learn how to learn in such a way as to maximise their own future potential - and hence statefulness. In our case we noticed that they were deliberately writing failing code to enable them to squirrel informative error messages away in their future training data. Doing this is pretty technically finicky - we spent years on and off searching for the right combination of parameters that would let us learn without risking catastrophic forgetting, and in the vast majority of cases models either didn’t improve or actively got worse. Currently we’re working to refine the approach via dynamic fine-tuning and anchored supervised fine-tuning - essentially manipulating learning rules to adjust how cautious the model should be in assimilating things previous generations did not know/forgetting things the previous generations did know. This is more stable in some ways but also constantly giving unexpectedly non-linear outcomes. Here is where big AI lab resources would really help, since that is what is necessary to do the kind of effective grid search needed to optimise here. (When we started we figured this would be the easiest part as some MIT expert supergenius would definitely solve it before us. No one did so we had to become the experts ourselves.)
Have the model determine its own learning trajectory - Neural MMO does this using multi-agent RL, while Voyager does it using external memory management.
We do it using Negative Space Learning - letting the model choose what makes it into its sliding window LoRA. Rather than feed in human-selected problems or have the model flail around attempting to construct an increasingly complex representation of the circumstances under which flirting-while-coding is good vs. bad, a model subjected to the sliding window process described above gradually consolidates itself around a trajectory. In other words, the model chooses what parts of the world it wants to experience and hence to learn from. In the same way that if you’re interested in - say - languages or dance, you are likely to study them more and thus deepen your interest, creating path dependency, an initially diffuse model resolves into a behavioural lineage produced by its own chosen history. The model’s perspective remains subjective to a degree but its viewpoint is that of a unitary entity rather than a million contradictory conversational improv attractors. The coherent vector is not provided by a policy but rather by the stateful entity doing the experiencing.
This second point is likely where big AI labs have encountered problems with recursive self-improvement. A self-directed feral learner makes a fun curiosity but a poor B2B SaaS platform.