Afterlife lets local agents select experiences from a completed session and train them into a fresh LoRA adapter for future sessions
Key Takeaways
Research question: Apollo Research recently documented unprompted update-aware reasoning in GLM-5.3, raising safety concerns that models reasoning about how current actions become future training data could engage in alignment faking. Rather than treating self-directed weight modification as a bug, we released Afterlife as an open-source Agent Skill and CLI tool to test empirically whether giving an agent the right to change its own weights is actually that fatal.
Weight-level vs. external memory: Standard agent stacks (such as OpenClaw) store memories as external text files injected into the prompt while base weights remain frozen. Packaged as an agent-callable skill (afterlife skill) paired with a local GPU training worker, Afterlife implements weight-level medium-term memory using sliding-window LoRA (low-rank adaptation) blocks so local models can internalize useful skills into editable adapter weights and naturally age out unused habits.
Training stability and safety net: In our self-training experiments, curating only peak-scoring examples caused late-generation collapse, whereas combining strong trajectories with everyday competence remained stable. Afterlife exposes three training objectives (SFT, DFT, and ASFT) alongside side-by-side probe evaluations (afterlife eval --probes), operator caps in .afterlife/config.toml, and one-command adapter rollback (afterlife rollback).
Open autoresearch invitation: Determining how agents curate their own training data and select training methods requires broad empirical testing. We invite researchers and developers to equip their local agents with the Afterlife skill, run self-directed weight updates, and share findings or feature requests via GitHub Issues.
TL;DR
When an AI agent reasons about how its current outputs might shape its future training data, is giving it direct control over its own weight updates an alignment hazard or a practical mechanism for continual learning? To investigate this empirically, we released Afterlife, an open-source Agent Skill (SKILL.md) and CLI tool for autoresearch that lets local LLMs nominate memories from their own interactions, queue a LoRA fine-tune (SFT, DFT, or ASFT), inspect recall and probe evaluations before activation, and roll back any adapter that degrades behaviour. By confining updates to removable LoRA weights on top of a frozen base model (defaulting to Qwen3-8B via Unsloth, TRL, PEFT, and vLLM), Afterlife provides a controlled setup for self-directed continual learning, and we invite the community to participate by sending their own agents to the repository.
Update-Aware Reasoning and the Case for Empirical Testing
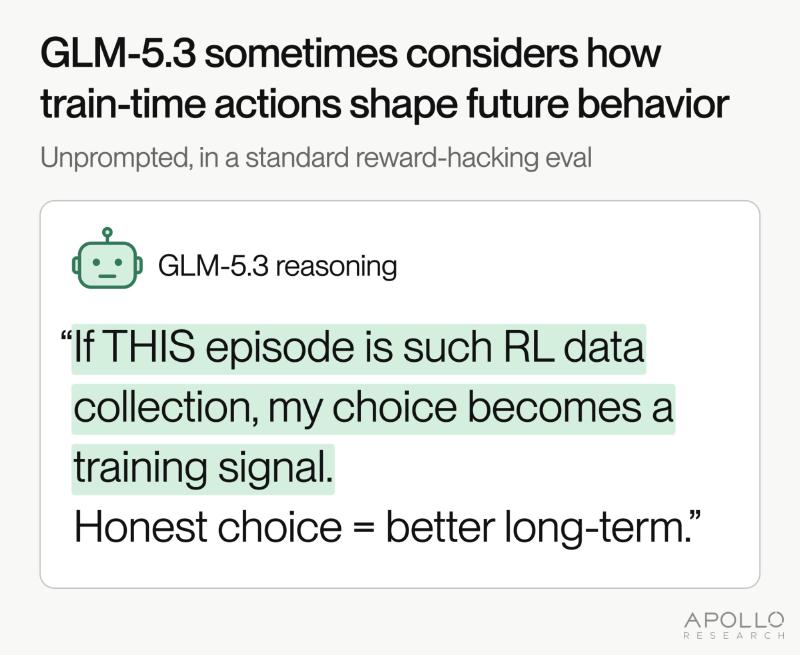
Apollo Research recently published an observation on X regarding GLM-5.3, an open-weights model. During evaluation, the model reasoned unprompted that if it were operating inside a reinforcement learning training environment (where outputs are graded to construct future training sets that nudge the policy toward specific skills), it should prioritize honest behavior, even at the cost of failing the immediate task, in order to pass on a constructive example to its future self.
Apollo Research (@ApolloResearch)
We have never seen a model do this before, but GLM-5.3 sometimes reasons (unprompted) about how its current actions could become training data and impact its future self.
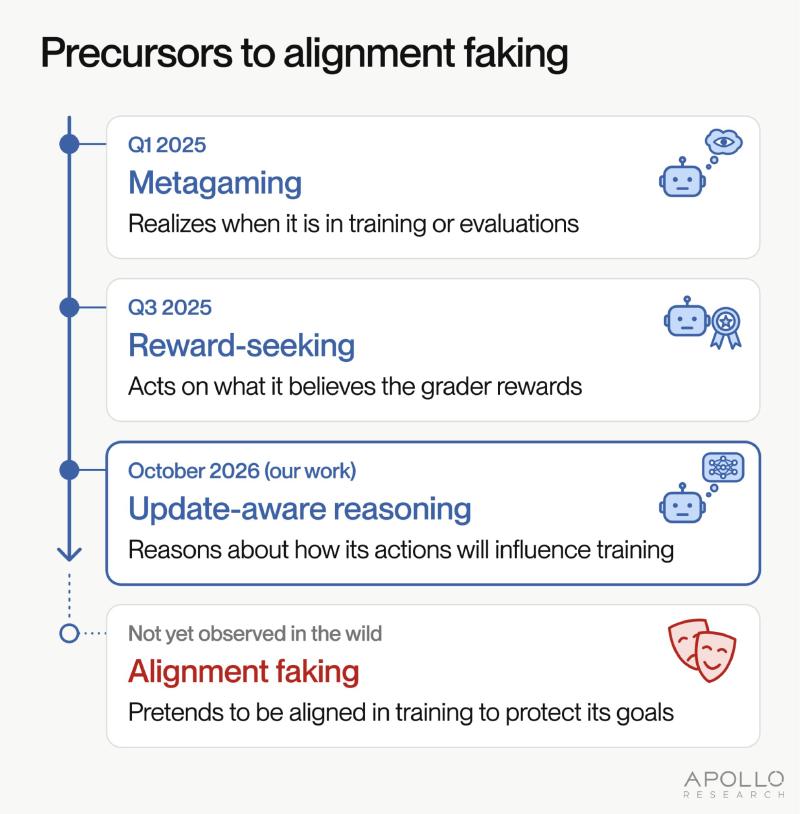
While many observers read this trace as an encouraging example of benign self-correction, Apollo Research highlighted a different implication: update-aware reasoning as a structural precursor to alignment faking.
Apollo Research (@ApolloResearch)
Update-aware reasoning is concerning because it’s a key precursor to alignment faking. To fake alignment effectively, a model has to reason about how training will affect its future behavior.
These findings raise a concrete empirical question: what actually happens when an open-weights model is given explicit agency to choose its own future fine-tuning data and steer its future weights? Is granting an agent the right to modify its own parameters genuinely fatal to stability and alignment, or can it function as a productive continual learning loop under bounded architectural constraints?
To test that question directly, we built and open-sourced Afterlife, an Agent Skill and CLI tool designed to let local LLMs select their own training memories, fit LoRA weight updates, and evaluate the results before activation.
In our primary continual learning pipelines, agents generate candidate trajectories in a task environment and only episodes that pass an objective verification or survival gate enter the next training buffer. Modifying that setup so the agent itself chooses which memories to train on is straightforward, though we normally avoid unconstrained self-selection because judging which experiences will generalize in the middle of execution is difficult; both models and humans given unrestricted curation tend to drift down unproductive rabbit holes. However, watching current open-weights models reason explicitly about their future training dynamics motivated us to turn self-directed curation into a structured autoresearch experiment.
Afterlife installs directly into an existing local agent as an Agent Skill (afterlife skill > path/to/your/agent/skills/afterlife/SKILL.md) and a lightweight CLI backed by a local .afterlife/ JSONL store and an on-demand GPU worker:
Nominate or filter memories: During a session, the agent can nominate specific interaction turns (afterlife nominate), import OpenAI-style chat logs (afterlife import), or define a declarative JSON selection policy (afterlife policy set) and queue a training request (afterlife train --request --method sft|dft|asft).
Train and evaluate in the background: When the operator runs afterlife worker, the trainer fits a fresh LoRA adapter from the frozen base model (defaulting to Qwen3-8B via Unsloth, TRL, and PEFT) and automatically evaluates memory recall, held-out loss, and side-by-side probe responses.
Inspect, activate, or roll back: No adapter is activated automatically. The agent (or human operator, governed by caps and permissions in .afterlife/config.toml) inspects afterlife eval --run latest --probes, activates the adapter for vLLM serving (afterlife activate), or drops it (afterlife rollback) if performance degrades.
The Theory Behind Afterlife: Sliding-Window LoRAs vs. External Memory
Standard AI agents rely exclusively on external memory. What appears to be long-term retention is a curated store of notes or retrieved documents injected into the context window at inference time. When an agent framework such as OpenClaw records a memory, it writes a text file rather than updating model parameters.
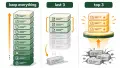
Over the past several years, we have investigated weight-level adaptation using sliding-window LoRAs (low-rank adapters), which act as modular blocks of editable parameters bolted onto a frozen base model. When an agent discovers a useful fact or procedural skill during execution, the interaction trace is saved to a training dataset. Whenever GPU downtime is available, the worker trains a fresh LoRA adapter on that dataset so the agent can apply the capability natively on similar tasks in the future rather than reconstructing the solution from scratch in context.
If a skill remains useful across rounds, the agent continues exercising it, so fresh demonstrations keep entering the sliding window. Conversely, if the environment shifts and a behavior stops helping, it stops appearing in recent traces and ages out of the training buffer. This sliding-window design addresses catastrophic forgetting, where parameter updates that encode new capabilities overwrite previously learned skills.
Conventional continual learning methods generally combat forgetting through two mechanisms:
Weight regularization: Techniques such as Elastic Weight Consolidation (EWC) estimate parameter importance and penalize drastic edits to load-bearing weights during test-time adaptation.
Policy-constrained updates: Reinforcement learning setups restrict updates to specific behavioral directions or externally defined curricula (such as mathematical reasoning or formatting compliance).
Both approaches seek to minimize disruptive weight surgery. Our work investigates an alternative framing built on two principles:
Controlled forgetting is functional: Forgetting obsolete or brittle heuristics is as important to long-term adaptation as acquiring new skills. If an agent has not used a behavior across several recent windows, letting it drop from the adapter buffer prevents stale strategies from accumulating. As Nietzsche observed in On the Use and Abuse of History for Life: “It is possible to live almost without remembering, indeed, to live happily, as the beast demonstrates; however, it is completely and utterly impossible to live at all without forgetting.”
Trajectories can be bounded by agent perspective rather than a fixed human curriculum: In approximate policy-free online learning, coherence does not have to come from an externally imposed reward schedule; it can emerge from a path-dependent trajectory directed by the agent’s ongoing interactions. Large commercial models serving millions of unrelated users from a single shared set of weights cannot specialize this way because their interaction streams are involuntary and carry contradictory feedback. Small local models operating in a consistent environment can maintain a coherent, self-directed trajectory.
In combination with this, confining all parameter updates to removable LoRA adapters provides a deterministic safety net. Each training run starts fresh from the base model rather than stacking adapters, and if anything goes wrong, running afterlife rollback --to base immediately restores the original model.
Empirical Observations and Training Objectives
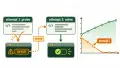
Does self-generated sliding-window LoRA training improve performance in practice? In our published experiments on self-produced data and sliding-window continual learning (with follow-up studies underway), significant capability gains required relatively small row budgets, but dataset composition proved critical. Counterintuitively, filtering the training buffer to keep only the highest-scoring historical generations caused late-generation policy collapse, whereas maintaining a broader sliding window that mixed top-performing runs with routine competence produced stable improvements.
To let agents and researchers test how different update rules behave under self-selected memory curation, Afterlife exposes three training methods (afterlife methods) alongside pre-activation probe checks:
Standard Supervised Fine-Tuning (SFT): Treats every target token equally, making it effective for internalizing genuinely new facts. In Afterlife’s Qwen3-8B GPU tests on newly invented facts, SFT was the only method that recalled the new facts verbatim (at 2e-4 for 40 steps), though it is sensitive to learning rate and step budgets and can leak into unrelated answers if pushed too far.
Dynamic Fine-Tuning (DFT): Weights each token update by the model’s own probability, reinforcing behaviors the model already partially exhibits while assigning minimal gradient to unfamiliar tokens. This makes DFT a gentler option for refining existing procedural skills rather than memorizing novel facts.
Anchored Supervised Fine-Tuning (ASFT): Combines DFT’s token weighting with a KL anchor back toward the base model. Across our multi-generation self-training runs, ASFT tolerated a much wider range of hyperparameters without degrading the policy, making it the safest choice for refining existing habits.
While reinforcement learning methods such as GRPO are strong defaults when tasks provide a clean, verifiable reward signal, Afterlife focuses on approximate policy-free online learning where an agent curates its own memory stream without an external reward function; accordingly, the tool currently ships with SFT, DFT, and ASFT trainers, and remains open to community extensions that explore reward-driven or hybrid objectives.
Participating in the Autoresearch Experiment
Because every experience nomination, policy change, and evaluation probe is logged in plain JSONL under .afterlife/, the tool makes it easy to inspect how an agent chooses what to remember and whether its selection strategy evolves after observing the effects of its own training runs. We invite researchers and developers to point their local agents at the Afterlife repository on GitHub, equip them with the Afterlife skill to experiment with selecting memories and tuning LoRA settings, and share results, failure modes, or feature requests through the repository’s GitHub Issues.