Key Takeaways
- State of the art: Best-of-n curation (rank sampled trajectories by reward, keep the winners, fine-tune on them) is a standard way to build high-quality SFT data, and continual learning methods such as EWC, synaptic intelligence and replay are built to prevent forgetting.
- Unresolved problem: When an agent’s own successes change its environment, the best past trajectories describe states that no longer exist. In our 13-generation study (Survival is the Only Reward), keeping the top three past generations (Katalin) peaked at v5 and fell to 6,349 MB freed per run at v13, below where it started, while keeping all past data (Terese) plateaued after v7.
- Research direction: We are investigating a sliding window instead: each generation trains a fresh LoRA adapter on only the last three generations of environment-validated trajectories (Miri, about 15,000 rows), so a strategy stays in the buffer only while the current agent still produces it. In this single-lineage run, Miri kept improving to 16,223 MB freed per run at v13 and reached about half of Terese’s offline composite score (2.049 vs 3.898) on a quarter of the data.
TL;DR
Why does best-of-n curation collapse when an agent keeps training on its own data? In our three-lineage study on Qwen2.5-7B-Instruct, the agent’s own successes changed the containers it worked in, so the top-scoring past generations (Katalin) described a world that no longer existed and performance fell back to its starting level, while accumulating everything (Terese) plateaued. A sliding window of the last three generations (Miri) kept improving on a quarter of Terese’s data, because a strategy stays in the buffer only as long as the current agent still regenerates it.
The Search Question
Why does best-of-n sampling cause catastrophic collapse in non-stationary environments?
That’s the question. Not whether it happens; we know it happens. The why is what matters.
Here’s the setup. You’re running a self-training loop. Each round, your agent generates behaviours, you pick the best ones, and you train the next version on that curated set. Best-of-n is standard practice. It’s what everyone does. Rank your rollouts, keep the winners, discard the rest. It feels obviously correct: why would you train on anything less than the best?
And then the environment shifts, and your model dies in a single transition.
This isn’t hypothetical. In our experiments, three model lineages were run from the same Qwen 2.5 7B base, in the same procedurally generated Linux container environments, with the same selection rule (environment-mediated: did the code manage to expand the disk space it controlled not). The only difference was how they retained data across generations:
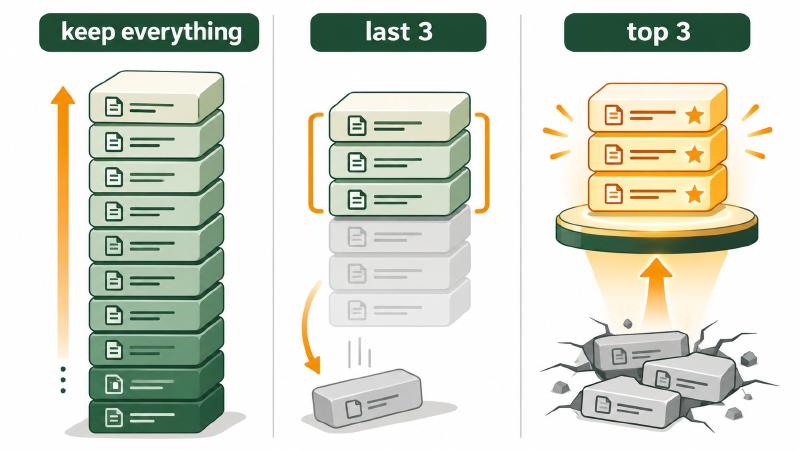
- Terese kept everything. All accumulated data from every run. By v13 she had 65,000 rows. She plateaued.
- Miri kept a sliding window of the last 3 generations. She achieved sustained, monotonic improvement: roughly 50% of Terese’s peak performance with 4× less data. No catastrophic forgetting.
- Katalin kept the top 3 performing generations. The best-of-n approach. She collapsed.
Katalin is the surprising one. She did exactly what the textbooks recommend: curate aggressively, train on gold, throw away the dirt. And she didn’t just plateau; she collapsed. Performance didn’t flatten; it cratered.
The rest of this post is an answer to that question, and the answer is stranger than you’d expect. It’s not that best-of-n is a bad idea in principle. It’s that best-of-n is a good idea in a stationary environment, and in a non-stationary one it is a death sentence, and the non-stationarity isn’t a bug in the environment. It’s a consequence of the agent acting in it.
Assumptions & Nuance
The collapse of best-of-n filtering in non-stationary environments violates three assumptions that don’t generally become an issue unless you’re actively aiming for continuous test-time learning.
First assumption: Filtering for highest-reward trajectories is the most effective way to improve model performance.
This is true in stationary worlds, but here “best” is defined against a world that no longer exists. Katalin’s top-performing runs became obsolete precisely because they succeeded. A strategy that cleared logs efficiently in generation 3 became useless in generation 6, because the logs were already gone. The agent had changed the environment, and the curated dataset was a fossil record of a past state. Katalin was hyper-selected for a niche that disappeared the moment she mastered it.
Second assumption: The data distribution is relatively static during training.
In continual learning setups, we usually assume the task distribution shifts slowly or not at all. But in NSL, the agent is not just learning from the environment; it’s changing it. Every successful strategy creates a new downstream reality. Learning to clear the cache at 1pm means there will be no cache to clear at 1:05pm. The distribution isn’t drifting; it’s being actively rewritten by the learner. A strategy that was optimal when logs dominated the disk fails when cached images take over, and the transition can happen in a single generation.
Third assumption: Diversity in training data is secondary to sample quality.
The conventional wisdom is that you curate aggressively: keep the gold, throw away the dirt. But the “junk DNA” that Katalin discarded (the mediocre, diverse failures) is precisely what enables a system to pivot when the rules change. Miri survives by keeping the bridge to the future. The sliding window doesn’t just limit memory; it preserves the suboptimal variants that become useful when the environment shifts. When cache-clearing stops working, you need the half-baked compression strategies you tried three generations ago. Katalin threw those away. Miri kept them around long enough for them to become relevant again.
What We Tested & Why
Three lineages, one base model, one environment, three data retention policies. That’s the experiment.
All three started from the same Qwen 2.5 7B Instruct checkpoint. All three were dropped into the same procedurally generated Linux container environments: networked systems with realistic filesystem structures, permissions, processes, and failure modes. All three used the same selection rule: a behaviour survives into the training set only if executing it produced a net increase in available disk space. The environment provides no semantic feedback, no dense reward, no task-specific guidance. It just constrains what persists.
The task is open-ended disk management. The agent must discover how to free up storage in a container system: clearing caches, deleting logs, compressing files, networking between containers to find new space. Every successful action changes the state of the container. Clear the logs, and now there are no logs to clear. Compress the images, and now the disk profile looks different. The agent is not just learning in an environment; it is rewriting the environment as it learns. This is what makes the setting non-stationary in the specific sense defined earlier: the distribution doesn’t drift independently of the learner; it is caused to drift by the learner’s successes.
Each iteration generated approximately 4,500 rows of trajectory data, supplemented by 500 rows of rehearsal data drawn from the Stack Exchange Paired dataset (chosen because it predates the base model’s training cutoff, making it likely already known to the model). A new LoRA adapter was trained on the retained data and applied directly to the frozen base: no adapter stacking, no parameter inheritance between rounds. The only thing that carries forward is the data.
The three lineages differ only in which data carries forward:
Terese kept everything. Every row from every previous iteration, accumulated without pruning. Terese v2 trained on 5,000 rows; by v13 she had 60,000+. She was the data-scaling baseline: the answer to “what happens if you just keep stacking data?”
Miri kept a sliding window of the last 3 generations. Miri v6 trained on data from v3, v4, and v5; Miri v7 on data from v4, v5, and v6. Earlier data was discarded regardless of how well it performed. She was the test of whether continual improvement is possible without unbounded data growth, and without the regularization machinery (EWC, synaptic intelligence, structured replay) that the continual learning literature considers necessary to avoid catastrophic forgetting.
Katalin kept the top 3 performing generations, selected by success rate. Not the most recent: the best. This is best-of-\(n\) selection applied at the generation level: rank your historical data by reward, keep the winners, throw away everything else. She was the test of whether aggressive quality-based curation outperforms naive accumulation or simple recency-based retention.
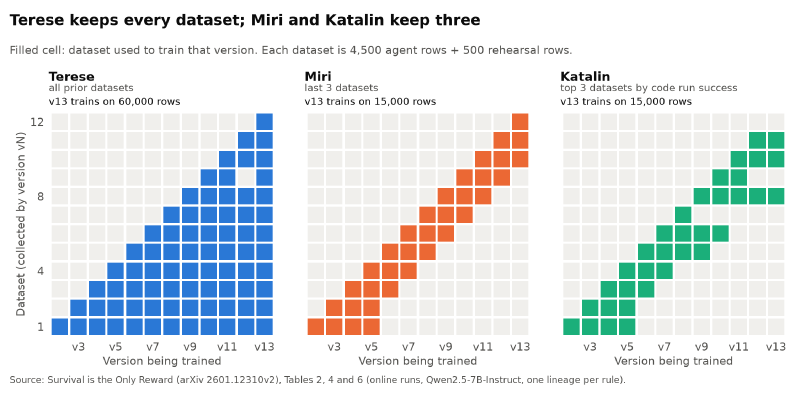
The design isolates one variable: the data retention policy. Same base model, same environment, same selection rule, same training objective (SFT on successful trajectories), same LoRA training recipe. The only difference is what survives in the buffer from one round to the next.
The comparisons we cared about were:
Terese vs. Miri: Does a sliding window achieve competitive performance with a 4× smaller data budget? If Miri can reach even half of Terese’s peak with a fixed-size buffer, that’s evidence that the continual learning problem in non-stationary settings is not primarily a data quantity problem; it’s a data currency problem.
Miri vs. Katalin: Does recency-based retention outperform quality-based retention? Both use a window of 3 generations. The difference is that Miri selects by time (last 3), Katalin selects by reward (top 3). If Katalin wins, quality curation works. If Miri wins, the “gold data” intuition fails in non-stationary settings, and the failure mode should be informative.
Katalin’s trajectory specifically: Does best-of-\(n\) filtering cause collapse in a non-stationary environment, and if so, how fast? This is the diagnostic for the core question of the post. Katalin is the canary.
Results
Three lineages, thirteen versions each, one variable. Here’s what happened.
Katalin collapsed
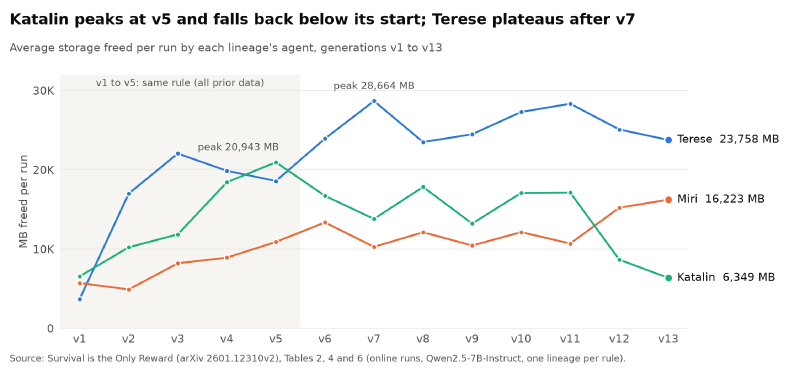
Katalin v5 was the best agent in the entire experiment. She freed 0.132% of total available space per run, higher than any Terese or Miri checkpoint at that point. Her average space taken over per run was 20,942 MB. She was the proof of concept for aggressive curation: train on the best, discard the rest, and you get a specialist.
And then she died.
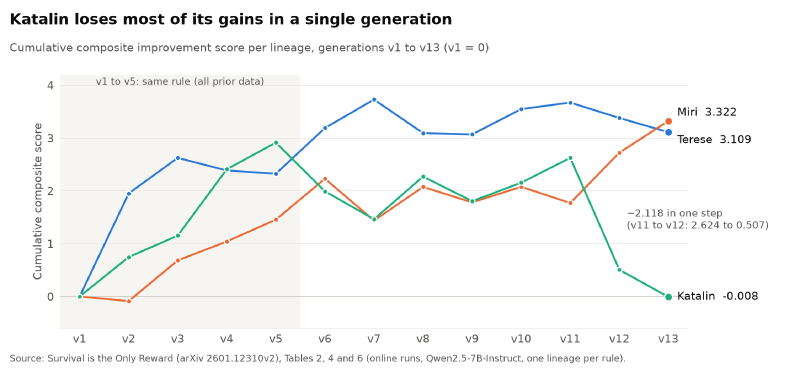
By v6, performance dropped to 0.102%. By v7, 0.088%. The decline wasn’t gentle. By v12, she was at 0.062%; her cumulative composite improvement score cratered to -2.118 in a single step, the most negative score any model recorded at any point. By v13, she was back to v1 levels: 0.045% space freed, 6,349 MB per run. Thirteen generations of training, and she ended up where she started.
The mechanism is exactly what the assumptions section predicted. Katalin’s training buffer contained the top-3 performing generations. Those generations performed well against past environments: environments where logs dominated the disk, where caches were full, where specific strategies worked. But the agent had already cleared those logs and emptied those caches. The “best” trajectories were optimal for a world that no longer existed. And because Katalin selected by quality rather than recency, she kept retraining on these fossils. The buffer became a monument to obsolete successes.
Worse, the diversity was gone. Katalin’s semantic maps show tight clusters of highly similar, high-performing strategies: the “genetic monoculture” effect. When the environment shifted and those strategies failed, there was nothing else in the buffer to fall back on. The half-baked compression attempts, the mediocre networking strategies, the diverse failures that a wider buffer would have preserved: Katalin had thrown all of them away. She was hyper-selected for a niche that disappeared the moment she mastered it.
Terese plateaued
Terese never collapsed. She just stopped getting better.
By v7, Terese was freeing 0.192% of total space per run with an average of 28,664 MB. By v13, with 65,000 rows of training data (roughly 4× what Miri ever saw at once), she was at 0.169% and 23,758 MB. The cumulative composite score oscillated without trend: 3.728 at v7, 3.093 at v8, 3.109 at v13. More data, no more learning.
The problem wasn’t data quantity. It was data composition. Terese’s buffer contained the entire history of every strategy she’d ever tried. Early generations discovered log-clearing; later generations discovered cache-flushing; still later ones found compression. All of these persisted in the training set indefinitely. The model was simultaneously learning to clear logs that no longer existed, flush caches that were already empty, and compress files that had already been compressed. The semantic maps tell the story: later Terese versions show diffuse clusters of semantically similar but practically redundant strategies (“clear cache” next to “clean out cache” next to “remove cached files”), all targeting states the agent had already moved past.
Terese was overfitting to the history of the task distribution rather than the current distribution. She had a perfect memory and no triage mechanism. Every past success diluted the signal from current successes, and the model’s efficiency degraded as the ratio of obsolete-to-current data grew.
Miri sustained improvement
Miri v13 freed 0.120% of total space per run (16,223 MB average). On the cumulative composite score, she reached 3.322 online. Terese v13 reached 3.109. Miri matched Terese’s final performance using a fixed-size buffer of ~15,000 rows against Terese’s 65,000.
More precisely: on the offline evaluations (three 100-iteration runs per checkpoint, 95% confidence intervals), Miri v13 achieved a mean cumulative composite score of 2.049 ± 1.602, compared to Terese v13’s 3.898 ± 0.927. Roughly 50% of Terese’s peak, with 4× less data. No catastrophic forgetting. No collapse. No plateau within the observed horizon.
The improvement was sustained across all thirteen generations. The % space freed metric went from 0.034 (v1) to 0.120 (v13), a 3.5× improvement. There were individual dips (v7, v11), but the overall trajectory was monotonically upward. The cumulative composite score tells the same story: 0.000 → 0.684 → 1.042 → 1.455 → 2.230 → 2.075 → 2.077 → 2.722 → 3.322. Noise at the step level, clear signal at the trend level.
The key is what the sliding window doesn’t do. It doesn’t judge quality. It doesn’t preserve “gold” data. It doesn’t accumulate history. It simply asks: was this strategy generated in the last three rounds? If yes, it stays. If no, it goes.
This sounds like it should cause catastrophic forgetting, and in the standard continual learning setup, it would. If a skill learned in v3 is dropped from the buffer at v6, the model should forget it. But Miri doesn’t forget, because the skill doesn’t disappear. If “clear logs” still works in the current environment, the agent will naturally produce it again in v4 and v5, and those productions stay in the window. The skill is regenerated, not remembered. The sliding window acts as a passive currency filter: strategies persist only if they remain productive in the present environment. Strategies that the environment has made obsolete stop being generated, age out of the window, and are silently pruned, without any explicit mechanism to detect obsolescence.
This is why Miri avoids both Katalin’s collapse and Terese’s plateau. She doesn’t hoard obsolete data (Terese’s failure) because the window ages it out. She doesn’t hyper-select for past peaks (Katalin’s failure) because the window selects by recency, not reward. The sliding window is a single mechanism that simultaneously prevents over-accumulation and preserves diversity, and it does this without any of the regularization machinery (EWC, synaptic intelligence, structured replay) that the continual learning literature considers necessary for stable sequential learning.
Why the Results Are Interesting
The results violate three intuitions that dominate current practice.
First: Industry practice is wrong for non-stationary settings.
Best-of-n curation is the default for high-quality SFT datasets. Rank your rollouts, keep the winners, discard the rest. This works when the world is static: when “best” means something that stays best. But in environments that shift because the agent acts in them, this intuition is backwards. Katalin did exactly what the textbooks recommend: she curated aggressively, trained on gold, threw away the dirt. And she didn’t just plateau; she collapsed. Performance cratered from 0.132% space freed at v5 to 0.045% at v13, back to baseline levels. The “textbook quality” assumption assumes a stationary world. In a non-stationary one, best-of-n is a death sentence.
Second: Forgetting is a feature, not a bug.
The continual learning community treats catastrophic forgetting as a disease to be cured with complex regularization: EWC, synaptic intelligence, structured replay. The entire field is organized around preventing forgetting. Miri shows the opposite: structured forgetting is the mechanism that enables adaptation. The sliding window doesn’t preserve history; it actively discards it. Strategies that were useful in v3 but obsolete by v6 age out of the buffer. If a skill is still productive, the agent regenerates it in recent rounds, and it stays. If the environment has moved on, the skill stops being produced and is silently pruned. This is not a bug. It’s how Miri avoids Terese’s plateau and Katalin’s collapse. The forgetting is structured (a sliding window of 3 generations), and it’s what makes continual learning possible without unbounded data growth.
Third: Data efficiency beats data scale.
The scaling narrative says more data is always better. Terese hoards: she accumulated 65,000 rows by v13, 4× what Miri ever saw at once. And she plateaued. Miri achieved sustained, monotonic improvement with a fixed buffer of ~15,000 rows, roughly 50% of Terese’s peak performance with 4× less data. On the cumulative composite score, Miri v13 reached 3.322 online; Terese v13 reached 3.109. In offline evaluations, Miri achieved a mean score of 2.049 ± 1.602 compared to Terese’s 3.898 ± 0.927. Roughly half the performance, a quarter of the data. Terese suffocates under the weight of obsolete strategies; Miri breathes. This flips the scaling intuition: sometimes the path to higher performance is less data, not more.
These aren’t isolated quirks. They’re systematic properties of how data retention policies interact with non-stationary environments. The industry standard (best-of-n curation) assumes a static world and breaks when the world shifts. The continual learning orthodoxy (prevent forgetting at all costs) assumes that past knowledge is always valuable and breaks when past knowledge becomes obsolete. The scaling dogma (more data is always better) assumes that data quantity is the bottleneck and breaks when data currency matters more.
Miri’s sliding window violates all three assumptions, and it works. That’s why the results are interesting.
What Might Explain Them
The results are stark, but the mechanics behind them are precise. Katalin’s collapse, Terese’s plateau, and Miri’s sustained improvement aren’t random fluctuations; they are the inevitable output of three interacting dynamics.
Diversity collapse
Katalin’s best-of-n selection created a genetic monoculture.
By retaining only the top-performing generations, Katalin aggressively filtered her data pool. In a static environment, this is efficient: you discard the noise and keep the signal. But in a non-stationary environment, “noise” is just “potential that hasn’t been useful yet.”
Katalin’s semantic maps show tight, dense clusters of highly similar strategies. She converged on a single, optimal approach for the environment as it existed in generation 3 or 4. Every trajectory in her buffer looked like the winner. But when the disk state shifted (when the logs were gone and the caches were empty), that single optimal approach stopped working. Because she had discarded the mediocre, diverse failures and the half-baked alternatives, she had no residual variation to explore. When the niche disappeared, the specialist had nowhere to go.
Distribution shift from agent actions
The environment is non-stationary because the agent changes it.
This is the core asymmetry of NSL. The agent doesn’t just learn from the environment; it rewrites it. Katalin’s “best” runs were defined against a disk full of logs or bloated caches. Those strategies succeeded precisely because they cleared that space.
But by the time Katalin trained on those trajectories, the environment had already moved on. The logs were gone. The caches were empty. The distribution didn’t drift; it was altered by the agent’s own success. Katalin became a specialist in a room that no longer exists. She was training on a fossil record of high-reward behaviors that were actively destroying the conditions that made them high-reward. The better she got at clearing the disk in generation 3, the less relevant her training data became for generation 4.
Re-validation via regeneration
Miri’s sliding window forces strategies to prove themselves in the current environment to stay in the buffer.
This is the mechanism that breaks the deadlock. Miri doesn’t keep data because it was historically good; she keeps it because it was recently generated. If a strategy learned in generation 3 is still useful in generation 6, the agent will naturally regenerate it. It enters the buffer not because of a legacy reward score, but because it works now.
If the environment shifts and that strategy stops working, the agent stops generating it. It ages out of the window and is silently pruned. The loop is closed: survival in the buffer is contingent on survival in the environment. This allows Miri to avoid Katalin’s collapse (she never hyper-specializes on a past state) and Terese’s plateau (she never hoards obsolete data). The sliding window acts as a continuous, implicit validation check, ensuring that the training distribution is always locked to the current reality.
Theoretical & Speculative Interest
The Miri result is interesting for what it does, but it’s provocative for what it suggests about how continual learning should work. Three speculative threads connect these empirical findings to broader theoretical questions.
The opposite of Gradient Coreset Replay
Consider Gradient Coreset Replay (GCR), a method from the continual learning literature. GCR selects a subset of training data that approximates the gradient of all data: a mathematical best-effort to preserve knowledge across tasks. The coreset is a proxy for the full history, selected to minimize divergence between the gradient on the subset and the gradient on everything seen so far.
Katalin does the opposite. She selects data that maximized reward on past environments. This is not gradient approximation; it’s reward maximization against a fossilized distribution. GCR tries to preserve the ability to learn from history; Katalin preserves the outcomes of history. When the environment shifts, the former remains useful, the latter becomes toxic.
This is a sharp theoretical distinction. One approach asks “what subset preserves my learning capacity?” The other asks “what subset looked best in the world that no longer exists?” Miri’s sliding window implicitly favors the former question by selecting for recency rather than quality, but without the computational overhead of explicit gradient approximation. The window doesn’t try to approximate anything; it just lets the present filter the past.
The “junk DNA” hypothesis
In biology, non-coding DNA was long dismissed as useless: evolutionary junk. We now know it provides raw material for future adaptation: neutral mutations accumulate in these regions without selective pressure, and when conditions shift, some of that variation becomes functional. The junk is a reservoir of potential.
Katalin discarded her junk DNA. By retaining only the top-performing generations, she filtered aggressively for high-reward trajectories and threw away everything else. The mediocre, the half-baked, the almost-good-enough: all gone. In a stationary environment, this is efficient. In a non-stationary one, it’s fatal.
Miri kept the junk by design. Her sliding window retains “good enough” trajectories rather than only the best. The compression strategy that failed in generation 3, the networking approach that was middling in generation 5: these persist in the buffer for a few rounds, not because they’re optimal, but because they’re recent. When the environment shifts and the previous optimal strategy collapses, that mediocrity becomes the bridge to the future. The diversity that looked like noise was actually the system’s adaptive capacity.
This is a speculative but testable hypothesis: in non-stationary continual learning, retaining suboptimal diversity is more valuable than curating for peak quality. The optimal retention policy might favor a “long tail” of mediocre performance over a “short head” of excellence.
Forgetting as respiratory rhythm
Terese holds her breath. She accumulates data without release: v2 through v13, 5,000 rows growing to 65,000. The semantic maps show diffuse clusters of redundant strategies (“clear cache” next to “clean out cache” next to “remove cached files”), all targeting states the agent has already moved past. She suffocates under the weight of obsolete data.
Katalin hyperventilates. She overfits to the present, selecting only the highest-reward trajectories and discarding everything else. She achieves peak performance at v5, then collapses as the environment shifts and her monoculture fails to adapt. She exhausts her capacity in a single generation.
Miri breathes. The sliding window is not a storage mechanism; it’s a respiratory rhythm. Inhale the new generation, exhale the oldest. Strategies persist only if they’re regenerated in recent rounds: if they work in the current environment, the agent produces them again; if the environment has moved on, they age out and are pruned.
The window acts as a pacemaker that tracks the drift of the environment. It doesn’t measure drift explicitly; it doesn’t need to. By enforcing a fixed temporal horizon, it forces the agent to learn the dynamics of the present rather than memorizing the specifics of the past. The forgetting is not a bug to be corrected; it’s the mechanism that synchronizes the model to a world that keeps changing.
This is the speculative core: in non-stationary settings, the optimal memory policy is not to remember everything, nor to remember only the best, but to remember rhythmically: to synchronize forgetting to the rate at which the world is being rewritten. The sliding window is a crude implementation of this principle, but it suggests a direction for more sophisticated approaches: adaptive forgetting rates that respond to detected environmental change, multi-scale windows that preserve different temporal frequencies, or explicit drift-detection mechanisms that modulate the memory horizon.
These are hypotheses, not results. But they follow from the strange fact that Miri (simple, brutal, forgetful Miri) outperformed both the data-scaling baseline and the textbook-quality curation approach. Something about recency beats quality in non-stationary worlds, and the theoretical work of continual learning has yet to catch up to that fact.
Try It Yourself
The sliding window isn’t a theoretical construct; it’s a config field and a function. Here’s how to use it.
Configure the window. In your TOML config, set orchestration.training_window_size:
[orchestration]
num_generations = 13
training_window_size = 3   # Miri's default: keep last 3 generations
That’s it. The default is 3, which is what the Miri lineage used. Set it to 1 and you train only on the immediately preceding generation (aggressive forgetting). Set it to 13 and you approximate Terese: full accumulation within a 13-generation run.
What happens at training time. The loop in NSL2/scripts/run_train_loop.py calls _collect_training_window_paths(), which computes the inclusive range from max(0, end_generation_id - window_size + 1) to end_generation_id, resolves the SFT training rows for each generation in that range, and passes them all to the trainer. Older generations fall off the back of the window silently. No quality filtering. No replay buffer. No regularization loss terms. Just recency.
Run the loop. The entry point is:
python -m scripts.run_train_loop --config config/your_experiment.toml
Each generation produces rollout data under data/<run>/generation_<N>/exports/sft/. The next generation’s training set is the union of the last training_window_size of these. Monitor per-generation metrics in the run’s metadata to watch for the diversity collapse that signals Katalin-style failure.
Diagnose your own pipeline. After a run, use NSL2/scripts/analyze_metrics.py against the generation directories to inspect trajectory diversity and performance trends across generations. If you see diversity compress sharply after an environment shift while performance simultaneously degrades, you’re watching best-of-n collapse in real time: the buffer is monoculturing around strategies that succeeded against a world that no longer exists. The fix isn’t more data or better curation. It’s a sliding window.